5 Statistics
5.1 Summary of this chapter
This chapter discusses several statistical topics relevant to NCA. Although NCA is primarily a (quasi-)deterministic mathematical (geometric) method rather than a statistical method based on probabilities, several statistical approaches and tools are still relevant for NCA. First, the chapter discusses the use of sampling logic in quantitative (large-n) NCA studies (Section 5.2). Second, four specific statistical tools and approaches for NCA are presented. These are a set of permutation tests for testing null hypotheses (Section 5.3), statistical modeling with NCA in particular for Monte Carlo simulation studies (Section 5.4), and the use of these simulations for evaluating the statistical quality of ceiling lines (Section 5.5) and for conducting power analyses (Section 5.6). Finally, the chapter discusses how three common problems in inferential statistics apply to NCA: reverse causality (Section 5.7), measurement error (Section 5.8) and spuriousness (Section 5.9).
5.2 Sampling logic
In large-n quantitative studies, NCA uses a sampling approach that is aligned with common practices in inferential statistics.51
For valid statistical inference, the sample should be representative of the population. Representativeness in NCA is especially important with respect to adequate coverage of cases with high values of \(Y\) and varying levels of \(X\) and combinations of \(X\) with other variables. General information on sampling logic in NCA is provided in Dul (2024b) and sampling for NCA’s statistical testing is discussed in Section 8.3. Usually, random sampling satisfies the requirements.
5.3 Permutation tests
NCA’s set of statistical tests consists of permutation tests to estimate the \(p\)-value for evaluating effect sizes and differences between effect sizes. NCA’s original test (called “Null” here) evaluates if the observed effect size differs from 0. The other tests are called:
“Contrast”, to evaluate if two conditions for the same \(Y\) have different effect sizes,
“Independent”, to evaluate if two independent groups of cases have different effect sizes,
“Paired”, to evaluate if effect sizes at two time points are different.
First, the general principles of the \(p\)-value and the permutation test are discussed, followed by a description of each test. The three newer tests are available in the NCA software in R from version 5.0.0.
5.3.1 General
According to the American Statistical Association (ASA), in statistical null hypothesis testing the \(p\)-value is a measure that helps assess the strength of evidence against a null hypothesis (Wasserstein & Lazar, 2016). In its 2016 statement on \(p\)-values, the ASA discusses what the \(p\)-value is, and what it is not. Essentially, the \(p\)-value indicates the compatibility of the data with the null hypothesis.
NCA tests the compatibility of the observed necessity effect size, or effect size difference with the null hypothesis of no relationship (the Null test) or no difference in distribution (the Contrast, Independent, and Paired tests). The unique feature of NCA’s null hypothesis tests is that it uses the necessity effect size as the test statistic. Note that no null hypothesis test can test an alternative hypothesis. If the null hypothesis is rejected, this does not imply that a specific alternative hypothesis is correct. A small \(p\)-value only suggests that the observed effect size (difference) is unlikely under the null hypothesis.
Scientific conclusions about the hypothesis of interest (the alternative hypothesis) should not be based solely on whether a \(p\)-value is below a threshold level (e.g., 0.05). For this reason, in concluding that a necessity hypothesis is supported,52 NCA not only requires a low \(p\)-value but also the presence of theoretical support and a practically relevant effect size. These are three minimum requirements for concluding about necessity. Together they protect the analyst against making false positive or false negative conclusions (Chapter 6).
NCA does not make an assumption about the type of distribution of the data (e.g., normality). The permutation test is a valid statistical approach for testing the randomness of effect size (difference) that does not rely on assumptions about the distribution of the data (like normality in t-tests or ANOVA). The permutation test constructs a null distribution empirically by resampling in a specific way from observed data. First, the test statistic, NCA’s effect size (difference), is computed using the original data. Next, resamples with the same sample size and the same sets of \(X\)- and \(Y\)-values are validly created by a specific type of permutation assuming that the null hypothesis of no relationship (or same distribution) applies. By rearranging the data randomly through permutations, any systematic relationship between \(X\) and \(Y\), or difference in effect size, is broken. This is done differently for each test (see below). For the resample (permutation), the effect size (difference) is recomputed, and this is repeated many times (e.g., 10,000) to obtain a null distribution of values for the effect size (difference). Finally, to compute the \(p\)-value, the observed effect size (difference) is compared with the effect sizes (or effect size differences) obtained under the null distribution. The \(p\)-value is the proportion of permuted effect sizes (or effect size differences) under the null that are as extreme or more extreme than the observed effect size (difference).
The validity of NCA’s four permutation tests (Null, Contrast, Independent, Paired) is based on a theorem (Hoeffding, 1952; Kennedy, 1995; Lehmann et al., 2005). The justification of the test rests on the so-called Randomization Hypothesis being true. The Randomization Hypothesis states:
Under the null hypothesis, the distribution of the dataset \(D\) is invariant under the transformation \(p\), that is, for every transformation \(p \in \mathcal{P}\), \(pD\) and \(D\) have the same distribution whenever \(D\) has distribution \(P\) in \(H_0\) (Lehmann et al., 2005, p. 633).
Here, \(D\) denotes the observed dataset (all cases and variables used in the test). The symbol \(p\) denotes one admissible randomization operation from the permutation scheme (e.g., a particular shuffling/relabeling/reassignment as defined by the test), and \(\mathcal{P}\) denotes the set of all admissible operations of that type. The expression \(pD\) denotes the transformed dataset obtained by applying \(p\) to \(D\) (e.g., shuffling \(Y\) across cases while keeping \(X\) fixed, swapping within-case labels such as \(X_1\) and \(X_2\), reassigning cases to groups while preserving group sizes, or swapping time labels within a case). Finally, \(D \sim P \in H_0\) means that the original dataset \(D\) is assumed to be generated from some distribution \(P\) that satisfies the null hypothesis \(H_0\); invariance then states that \(pD\) is distributed the same way as \(D\) under \(H_0\).
In other words, the validity of the permutation test rests on the fact that, under \(H_0\), applying any admissible transformation \(p \in \mathcal{P}\) produces a dataset \(pD\) that is distributed like the original dataset \(D\). Thus, random draws of \(p\) generate valid “null” replicates of the data. Each test simply uses a different admissible transformation set \(\mathcal{P}\) (i.e., different permissible relabelings/assignments) corresponding to the hypothesis and the design:
Null: \(H_0^{\text{}}:\; d_{X \rightarrow Y}=0\).
Contrast: \(H_0^{\text{}}:\; d_{X_1 \rightarrow Y}-d_{X_2 \rightarrow Y}=0\).
Independent: \(H_0^{\text{}}:\; d_{G_1(X \rightarrow Y)} -d_{G_2(X \rightarrow Y)}=0\).
Paired: \(H_0^{\text{}}:\; d_{T_1(X \rightarrow Y)} -d_{T_2(X \rightarrow Y)}=0\).
where \(d\) is the effect size, and \(X_1\) and \(X_2\) are two different conditions, \(G_1\) and \(G_2\) two different groups, and \(T_1\) and \(T_2\) two different time points. The differences between the four tests are shown in Table 5.1.
| Test name | Sample(s) | Question | Permutation logic |
|---|---|---|---|
| Null | One | Does \(X\) constrain \(Y\) at all? | Randomly shuffle \(Y\) across cases while keeping \(X\) fixed. |
| Contrast | One | Which condition (\(X_1,X_2\)) constrains \(Y\) more? | For each case, randomly switch the labels \(X_1\) and \(X_2\) with 50/50 probability. |
| Independent | Two (Groups) | In which group (\(G_1, G_2\)) does \(X\) constrain \(Y\) more? | Pool both groups (\(G_1\) and \(G_2\)), randomly reassign cases to two groups of the same sizes. |
| Paired | Two (Times) | Does the constraint of \(X\) on \(Y\) change over time (\(T_1, T_2\))? | For each case, randomly decide whether to switch the time labels (\(T_1,T_2\)). |
5.3.2 Assumptions for NCA’s permutation tests
Beyond representativeness, NCA’s permutation tests additionally rely on the assumption of exchangeability under the null hypothesis. Exchangeability means that, under \(H_0\), the joint distribution of the observed data is invariant under the admissible permutations (i.e., relabelings/reassignments) specified by the test’s permutation scheme. More specifically, for the difference tests, NCA’s permutation test assumes that exchangeability holds after a min-max normalization for each group that puts the \(XY\) variables in each group on the same (dimensionless) scale, for example a 0–1 scale. Such normalization does not change effect sizes for the two groups involved (Appendix D). In practical terms, this implies that no case has a special status with respect to the tested relationship once the null hypothesis of no necessity (or no difference in effect size) holds. When this condition is met, applying the test-specific permutations (permuting \(X\)-\(Y\) pairings, swapping within-case condition or time labels, or reassigning group labels) generates valid resamples from the same null distribution.
Representativeness and exchangeability are related but distinct requirements. Representativeness concerns the external validity of the sample (whether conclusions can be generalized to the population), whereas exchangeability concerns the internal validity of the permutation test (whether the permutation distribution correctly reflects \(H_0\)). Exchangeability is in general satisfied when the relevant units are independent and identically distributed under \(H_0\), and when the sampling or measurement design does not introduce systematic differences that are not respected by the permutation scheme.
5.3.3 Null test: effect size difference from 0
In the Null test, the observed effect size of a single sample is compared with the null of no relationship. This is the standard NCA null test described in detail elsewhere (Dul, Van der Laan, et al., 2020). The test addresses whether \(X\) affects \(Y\) at all, operationalized as whether effect size \(d\) > 0. The permutation logic is to generate the null distribution by randomly shuffling \(Y\)-values across cases while keeping \(X\)-values fixed. This breaks the pairing of \(X\)- and \(Y\)-values, which is admissible under the null of no relationship.
The transformation set \(\mathcal{P}\) (see the Randomization Hypothesis) contains all possible transformations (permutations) of the data under the null; for \(n\) cases this corresponds to \(n!\) permutations of \(Y\)-values across cases (permutations of case labels applied to \(Y\)). Under \(H_0\), shuffling \(Y\) does not change the joint distribution of the data, so the permuted datasets are valid null replicates. The test statistic is the \(XY\) effect size \(d\). The Null test is one-sided.
5.3.4 Contrast test: effect size difference between two conditions
In the Contrast test, two observed effect sizes from the same sample are compared with the null of no difference between them. The test addresses which condition, \(X_1\) or \(X_2\), constrains \(Y\) more within the same sample. The permutation logic is to generate the null distribution by, for each case, randomly swapping the condition labels 1 and 2 with 0.5 probability. This preserves each case’s observed part of \(X\)-values and its \(Y\)-value, but randomizes which \(X\)-value is labeled \(X_1\) versus \(X_2\), thereby removing any systematic difference between the conditions under the null.
The transformation set \(\mathcal{P}\) of admissible permutations under the null consists of all possible within-case label swaps of \(X_1,X_2\) across the \(n\) cases (i.e., \(2^n\) possible swap patterns). The null hypothesis is that the joint distribution is invariant to exchanging the labels \(1\) and \(2\), implying that \(X_1\) and \(X_2\) constrain \(Y\) equally. The test statistic is the difference in necessity effect sizes, \(d_{X_1\rightarrow Y}-d_{X_2\rightarrow Y}\). The Contrast test is two-sided.
5.3.5 Independent test: effect size difference between two groups
In the Independent test, the observed effect sizes from two independent samples (group \(G_1\) and group \(G_2\)) are compared. The test addresses in which group \(X\) constrains \(Y\) more. The permutation logic is to generate the null distribution by pooling cases from both groups and randomly reassigning them to two groups of the same sizes (i.e., permuting the group labels \(G_1\) and \(G_2\)). This removes any systematic group difference under \(H_0\) while preserving the observed \((X,Y)\) pairs.
The transformation set \(\mathcal{P}\) of admissible permutations under the null consists of all reallocations of cases to \(G_1\) and \(G_2\) that preserve the original group sizes. The null hypothesis is that the joint distribution of \((X,Y)\) is the same in both groups, so group membership is exchangeable; consequently, reassigning cases to groups does not change the distribution under \(H_0\). The test statistic is the difference in necessity effect sizes, \(d_{G_1(X\rightarrow Y)}-d_{G_2(X\rightarrow Y)}\). The Independent test is a two-sided test.
5.3.6 Paired test: effect size difference between two time points
In the Paired test, the observed effect size difference between two dependent (paired) samples (e.g., repeated measures) is compared with the null hypothesis of no effect size difference. In this design, the same cases are measured twice (e.g., at \(T_1\) and \(T_2\) on the same \(X\) and \(Y\)). The test addresses whether the constraint of \(X\) on \(Y\) changes over time. The permutation logic is to generate the null distribution by, for each case, randomly deciding whether to swap the time labels \(T_1\) and \(T_2\) (i.e., swapping the paired observations) with probability 0.5.
The transformation set \(\mathcal{P}\) of admissible permutations under the null consists of all within-case time-label swaps across the \(n\) cases (i.e., \(2^n\) possible swap patterns). The null hypothesis is that the \((X,Y)\) observations at both time points are drawn from the same distribution, so swapping the time labels within cases leaves the joint distribution unchanged. The test statistic is the difference in necessity effect sizes, \(d_{T_1(X\rightarrow Y)}-d_{T_2(X\rightarrow Y)}\). The Paired test is a two-sided test.
5.3.7 Common scope
For comparability of two effect sizes, a common scope should be selected. Depending on the question one tries to answer, this can be the pooled empirical scope (based on observed minimum and maximum scale values), a theoretical scope (e.g., based on theoretical minimum and maximum scale values), or a min-max normalized scope (e.g., \([0,1] \times [0,1]\)) that makes the scales dimensionless and numerically equal.
5.4 Statistical modeling
As mentioned earlier, NCA is primarily a (quasi-)deterministic mathematical (geometric) method rather than a statistical method based on probabilities. For a given \(XY\)-pair, the maximum value of \(Y\) for a given value of \(X\) can be expressed as the inequality:
\[\begin{equation} \tag{5.1} Y \le f_j(X_j), \qquad X_j \in [x_{j\min}, x_{j\max}], \; Y \in [y_{\min}, y_{\max}] \end{equation}\]
where \(f_j(X_j)\) is the ceiling line in the \(X_jY\)-plane (\(j = 1, \dots, J\)) within the bounding box.
In statistical terms, NCA is a ‘semi-parametric’ approach that only specifies particular features of the distribution (Greene, 2012, p. 482). In NCA, these specified features are the ceiling lines \(f_j(X)\) and the bounding boxes. It is assumed that there are no errors of measurement in variables \(X\) and \(Y\). In NCA the distribution under the ceiling is not specified. This is inherent to NCA’s goal of analyzing necessary but not sufficient conditions: a certain level of \(X\) is required for having a certain level of \(Y\) but it does not automatically produce that level of \(Y\). In other words, the aim of NCA is not to predict the presence of \(Y\) below the ceiling, but to predict the absence of \(Y\) above the ceiling.
For some applications with NCA (e.g., Monte Carlo simulations), it is needed to specify the full data generation process (DGP) and to make assumptions about the distribution of data under the ceiling. In that case the analyst must make such an assumption, and Equation (5.1) must be extended with an error term, representing the distribution below the ceiling line:
\[\begin{equation} \tag{5.2} Y = f_j(X) - \varepsilon_{j} \qquad X_j \in [x_{j\min}, x_{j\max}], \; Y \in [y_{\min}, y_{\max}] \end{equation}\]
where \(f_j(X_j)\) is the ceiling line in the \(X_jY\)-plane (\(j = 1, \dots, J\)) within the bounding box, and \(\varepsilon_j\) is a non-negative random variable representing the distance of an observation below the ceiling.53 When the border line is a ceiling line (i.e., when the upper-left or the upper-right corner of the \(X_jY\)-plot is empty), \(\varepsilon_j\) takes non-negative values only. When the border line is a floor line (i.e., when the lower-left or lower-right corner is empty), \(\varepsilon_j\) takes only non-positive values. Depending on the application, the error term is specified.
Thus, for conducting Monte Carlo simulations with NCA not only the NCA model (Section 4.3) but also the distribution of the data under the ceiling must be specified. This means that the analyst must make choices about:
The bounding box (bounded variables).
The ceiling line.
The distribution of the data.
Examples of bounded variable distributions are the uniform distribution and the truncated normal distribution. The uniform distribution can be considered a distribution with minimum assumptions: only two parameters must be assumed, namely the variable’s upper and lower bound. The truncated normal distribution needs two additional parameters (mean and standard deviation). To obtain a bivariate distribution for \(X\) and \(Y\) while ensuring an empty space above the true ceiling, the selected univariate distributions for \(X\) and \(Y\) (e.g., both uniform, or one uniform and the other truncated normal) within the bounding box \([0,1] \times [0,1]\) are combined by removing points above the true ceiling line. Figure 5.1 shows typical random samples of n = 100 drawn from the two bivariate population distributions using the nca_random function of the NCA software in R. In Figure 5.1-left both \(X\) and \(Y\) have uniform-based distributions and in Figure 5.1-right both distributions are truncated normal-based.54
In most applications of NCA, the ceiling line is estimated from the data, rather than being determined in advance (e.g., theoretically or based on earlier studies). For estimating the ceiling line with empirical data, the techniques mentioned in Section 4.4 could be used.
Figure 5.1: Random sample (n = 100) from a population with a true linear ceiling line with a uniform-based distribution (Left) and a truncated normal-based distribution (Right).
Note that a necessity relationship cannot be simulated with distributions that are unbounded in both directions with non-zero probability in every region of the \(XY\)-plane, such as the normal distribution. With such variables a necessity effect size cannot exist in the population. The reason is the following. In NCA, a necessity effect is defined by the presence of an empty ceiling zone where no observations occur because they are impossible due to a necessity constraint. This ceiling zone is bounded by the ceiling line and the bounding box. Together, the ceiling line and the bounding box define the feasible area which is the region where observations can occur. If cases are drawn from such distributions, the assumptions needed for a true necessity effect are violated. With an assumption of such distributions, both \(X\) and \(Y\) can take arbitrarily large (or small) values. As sample size increases, the maximum and minimum values increase, and the observed bounding box expands. There is no natural bound to define a fixed box for the ceiling zone. In a population with such distributions, there is always a non-zero probability that any combination of \(X,Y\) occurs, even values far above a supposed ceiling line. Therefore, no region of the space is guaranteed to be empty, and no necessity effect can exist in the population. Because in this situation the ceiling zone is never truly empty in the population, the true necessity effect size that is defined as the limit of the proportion of the bounding box that is unpopulated is exactly zero. Any non-zero effect size seen in a sample is an artifact. Even when the population has no necessity constraint, a finite sample will always have a maximum observed value of \(X\) and \(Y\), a finite bounding box (scope), and an empirical ceiling line that appears to limit the upper boundary of observations. This may give the illusion of a ceiling zone. NCA may then calculate a non-zero necessity effect size, but this is due to sampling limits not a true structural constraint.
For example, suppose \(X\) and \(Y\) are drawn from a bivariate normal distribution \(X, Y \sim \mathcal{N}(0, 1)\). In a sample of n = 100, the observed range might be approximately [-3, 3] for both \(X\) and \(Y\). A ceiling line (e.g., \(y = 2 + 0.5x\)) may appear to bound the upper edge of the \(XY\)-plot. NCA would calculate a non-zero effect size based on the empty region above this line. However, in the full population, values of \(Y\) above this line still occur with non-zero probability. As \(n \to \infty\), with a fixed theoretical scope, the ceiling zone fills in, causing the effect size to decrease to zero.With an empirical scope the effect size also decreases to zero but extremely slowly.
When NCA calculates an effect size from sample data, it estimates a property of the population. But in the case of such distributions of \(X\) and \(Y\), no necessity property exists to estimate. The observed sample statistic does not reflect a meaningful necessity effect in the population. When unbounded variables are used in Monte Carlo simulations it is inherently assumed that necessity does not exist for the phenomenon that is simulated. An analyst’s choice to use such a distribution therefore implies the analyst’s theoretical expectation that necessity does not exist in the population and that any observed empty space is an artifact. Note that even if a statistically significant empty space would have been detected, NCA does not support necessity if there is no theoretical justification for it (Chapters 6 and 7).
In the remainder of this chapter, two applications of NCA with specification of the full data generation process that include a ceiling line, are presented: the use of Monte Carlo simulation for evaluating the quality of NCA’s ceiling lines, and the use of Monte Carlo simulation for conducting a power analysis for NCA. Another application of Monte Carlo simulations for evaluating the statistical credibility of NCA in terms of True Positive Rate (sensitivity) and True Negative Rate (specificity) is presented in Chapter 6 about the credibility of NCA.
5.5 Quality of ceiling lines
When a necessity relationship is present in the population, an empty area in a sample is a manifestation of the necessity effect in the population. To identify this necessity effect, NCA estimates the ceiling line, the bounding box, and the related effect size.
5.5.1 Statistical quality criteria
When analyzing sample data for statistical inference, the calculated statistic (in NCA the ceiling line’s effect size) is an estimator of the true parameter in the population. An estimator is considered to be a good estimator when for finite (small) samples the estimator is unbiased and efficient, and for infinite (large) samples the estimator is consistent. Unbiasedness indicates that the mean of the estimator for repeated samples approximates the true parameter value; efficiency indicates that the variance of the estimator for repeated samples is small compared to other estimators of the population parameter. Consistency indicates that as sample size increases, the mean of the estimator approaches the true value of the parameter and the variance approaches zero. When the latter applies, the estimator is called asymptotically unbiased, even if the estimator is biased in finite (small) samples. An estimator is asymptotically efficient if the estimate converges relatively fast to the true population value when the sample size increases.
There are two ways to determine the unbiasedness, efficiency and consistency of estimators: analytically and by simulation. In the analytic approach the properties are mathematically derived. This is possible when certain assumptions are made. For example, the OLS regression estimator of a linear relationship in the population is ‘BLUE’ (Best Linear Unbiased Estimator) when the Gauss-Markov assumptions hold (the dependent variable is unbounded, homoskedasticity, error term unrelated to predictors, etc.).
In the simulation approach, a Monte Carlo simulation is conducted by first specifying the true population parameters (variables and distributions). Repeated random samples are drawn from this population, and the estimator is computed for each sample. This yields a sampling distribution of the estimator, which is then compared to the known population parameter.
Both analytic and simulation approaches generally assume an idealized scenario: an infinite population, random sampling, known distributions, and no measurement error. Deviations from these assumptions substantially increase analytic and computational complexity.
Data transformations are not uncommon, for example, to ensure normal distributions or meeting assumptions. However, data transformation may change the nature and content of the theory. In NCA data transformation can change the bounding box, and if not affine, these transformations are likely to change the value of the necessary condition effect size, thereby introducing spurious effect sizes. For example, if \(X\) is necessary for \(Y\), then \(\log(X)\) may not be necessary for \(\log(Y)\) and vice versa (Appendix D). In NCA, the analysis is therefore always conducted with data that represent the theoretical meaning of the concepts in the necessity hypothesis.
5.5.2 Simulation results for NCA’s effect size
For NCA, currently no analytic approach to determine bias, efficiency, and consistency exists. However, NCA can rely on simulations to evaluate the quality of its estimates. In this section, Monte Carlo simulation is used for estimating the true effect size in a population using four types of ceiling line estimation techniques. These ceiling lines are the stepwise linear ceiling line CE-FDH, and three linear ceiling lines CR-FDH, C-LP and QR. The QR-ceiling line is not recommended (Section 4.4), but is added for comparison. The theoretical scope (unit box) is selected to make the results comparable.
In Monte Carlo simulation, the full DGP needs to be specified. It is assumed that a high-high direction of necessity exists in the population (high \(X\) is necessary for high \(Y\)), with a true linear ceiling line \(Y = 0.4 + X\). The bounding box is assumed to be the unit box. The corresponding true effect size is 0.18. Next to the specification of the true ceiling line and bounding box, a Monte Carlo simulation also requires a specification of the true distribution of the data under the ceiling line. Three distributions are considered: uniform distribution, symmetric truncated normal distribution with equal means of \(X\) and \(Y\) (0.5), and left-skewed truncated normal distribution with high mean for \(X\) (0.75) and low mean for \(Y\) (0.25). The standard deviation of all truncated normal distributions is 0.2.
The simulation draws samples from these predefined population characteristics. The seven sample sizes that are selected vary between 20 and 5000. One hundred samples are drawn per sample size. This is repeated for each form of the ceiling line.55 Figure 5.2 shows a typical sample selected from each distribution, also showing the four ceiling lines that were tested.
Figure 5.2: Random samples with uniform, truncated normal and skewed truncated normal joint distribution with four ceiling lines estimation techniques. True ceiling line = \(Y = 0.4 + X\). True effect size is 0.18.
Figure 5.3: Monte Carlo simulation results for the effect size of four ceiling line estimation techniques. True ceiling line = \(Y = 0.4 + X\). True effect size is 0.18. Uniform distribution.
Figure 5.4: Monte Carlo simulation results for the effect size of four ceiling line estimation techniques. True ceiling line = \(Y = 0.4 + X\). True effect size is 0.18. Truncated normal distribution x-mean = 0.5, y-mean = 0.5.
Figure 5.5: Monte Carlo simulation results for the effect size of four ceiling line estimation techniques. True ceiling line = \(Y = 0.4 + X\). True effect size is 0.18. Skewed truncated normal distribution x-mean = 0.75, y-mean = 0.25.
Figures 5.3, 5.4, and 5.5 show the results for the uniform, truncated normal and skewed distributions, respectively. For small samples, the effect sizes are upward biased (the true effect size is smaller) for all estimation techniques. The bias of the estimated effect sizes can be large with the truncated normal and skewed distributions, caused by the limited number of points near the ceiling. These are the only points that are informative for the ceiling line in the population.
When sample size increases, the bias and the variance decrease for all estimation techniques. With increasing sample size, the effect size approaches the true effect size for three ceiling techniques: CE-FDH, CR-FDH and C-LP. This means that these techniques are asymptotically unbiased and that the three estimators are consistent. Of these ceiling lines, C-LP seems more efficient, reaching the true ceiling line more quickly and with the least variation. With increasing sample size, the QR estimation technique does not approach the true effect size and remains asymptotically biased. Possible reasons are discussed in Section 4.4.
These results only apply to the investigated situations with a true ceiling line that is linear, and data that have no measurement error. Therefore, in this situation the C-LP line may be a preferred technique. Such ‘ideal’ circumstances may apply in simulation studies, but seldom apply in reality. When the true ceiling line is linear but cases have measurement error, the CR-FDH line may perform better because measurement error usually reduces the effect size (ceiling line moves upwards). When the true ceiling line is not linear, CE-FDH may perform better because this line can better follow the non-linearity of the border (Figure 8.1). Further simulations need to be done to clarify the different statistical properties of the ceiling lines under different circumstances. In these simulations the effects of different population parameters (effect size, ceiling slope, ceiling intercept, non-linearity of the ceiling, distribution under the ceiling), and of measurement error (error-in-variable models) on the quality of the estimations could be studied.
5.6 Power analysis
“The power of a test to detect a correct alternative hypothesis is the pre-study probability that the test will reject the test hypothesis (the probability that \(p\) will not exceed a pre-specified cut-off such as 0.05)” (Greenland et al., 2016, p. 345). The higher the power of the test, the more sensitive the test is to reject the null hypothesis (and to accept the assumed alternative necessity hypothesis) if necessity exists in the population. Knowledge about the power of NCA’s statistical test is useful for planning an NCA study. It can help to establish the minimum required sample size for being able to detect, with a high probability (e.g., 0.8), an existing necessity effect size (difference) that is considered relevant (e.g., for the Null test effect size = 0.10). Note that a post-hoc power calculation as part of the data analysis of a specific study does not make sense (e.g., Christogiannis et al., 2022; Lenth, 2001; Zhang et al., 2019). In a specific study, power does not add new information to the \(p\)-value. Because power is a pre-study probability, a study with low power (e.g., with a small sample size) can still produce a small \(p\)-value and conclude that a necessary condition exists, although the probability of identifying this necessity effect is less than with a high-powered study (e.g., with a large sample size).
Statistical power increases when effect size and sample size increase. For a given expected necessity effect size in the population, the probability of not rejecting the null hypothesis when necessity is true can therefore be reduced by increasing the sample size.
Power of NCA’s statistical test can be evaluated by simulation.56 The simulation presented evaluates the power of NCA’s Null test. The simulation includes five population effect sizes ranging from 0.10 (small) to 0.50 (large) (Figure 5.6). The population effect size is the result of a linear population ceiling line with slope = 1 and an intercept that corresponds to the given population effect size.
Figure 5.6: Five ceiling lines (slope = 1) with corresponding effect sizes of 0.10, 0.20, 0.30, 0.40, and 0.50.
For the simulations, bivariate population distributions are obtained with the procedure as described in Section 5.4. A large number of samples (500) of a given sample size are randomly drawn from the bivariate population distribution. This is done for 2 × 5 × 11 = 100 situations: two bivariate distributions (uniform-based or truncated normal-based), five effect sizes (0.10, 0.20, 0.30, 0.40, 0.50), and 11 sample sizes (5, 10, 20, 30, 40, 50, 100, 200, 500, 1000, 5000). In each situation, NCA’s \(p\)-value is estimated for all 500 samples. The power is calculated as the proportion of samples with estimated \(p\)-value less than or equal to the selected threshold level of 0.05. This means that if, for example, 400 out of 500 samples have \(p < 0.05\), the power of the test in that situation is 0.8. A power value of 0.8 is a commonly used benchmark for a high-powered study.57
The relationship between sample size and power for different population necessity effect sizes is shown in Figure 5.7 for the uniform distribution and in Figure 5.8 for the truncated normal distribution. The figures show that when the effect size to be detected is large, the power increases rapidly with increasing sample size. A large necessity effect of about 0.50 can almost always be detected (power ~ 1.0) with a sample size of about 30. However, to obtain a high power of 0.8 for a small effect size of about 0.1, the sample size needs to be doubled (to about 60) with a uniform distribution, and to more than 10 times larger (to about 300) with a truncated normal distribution.
In general, the minimum required sample size to detect a necessary condition is larger for a truncated normal distribution than for a uniform distribution. The reason is that the truncated normal distribution has a lower density of cases in the lower-left and upper-right corners of the \(XY\)-plot, such that the empty space in the upper-left corner is less frequently challenged during the permutation test (Figure 5.1). Additional simulations indicate that sample sizes must be larger when the density of observations near the ceiling is smaller, in particular when there are few cases in the upper-right or lower-right corners under the ceiling. Also, larger samples are usually needed when the ceiling line is more horizontal and to a lesser extent when it is more vertical. On the other hand, when sample sizes are large even very small effect sizes (e.g., 0.05) can be detected. Note that a high-powered study only increases the probability of detecting a necessity effect when it exists. Low-powered studies (e.g., with a small sample size) can still detect necessity (\(p < 0.05\)), but have a higher risk of false negative results: concluding that necessity is not supported, when it actually does exist. Note that in small-n studies a dichotomous necessary condition where \(X\) and \(Y\) can have only two values, can be easily falsified when necessity does not exist in the population using purposive case selection (Section 8.3.2).
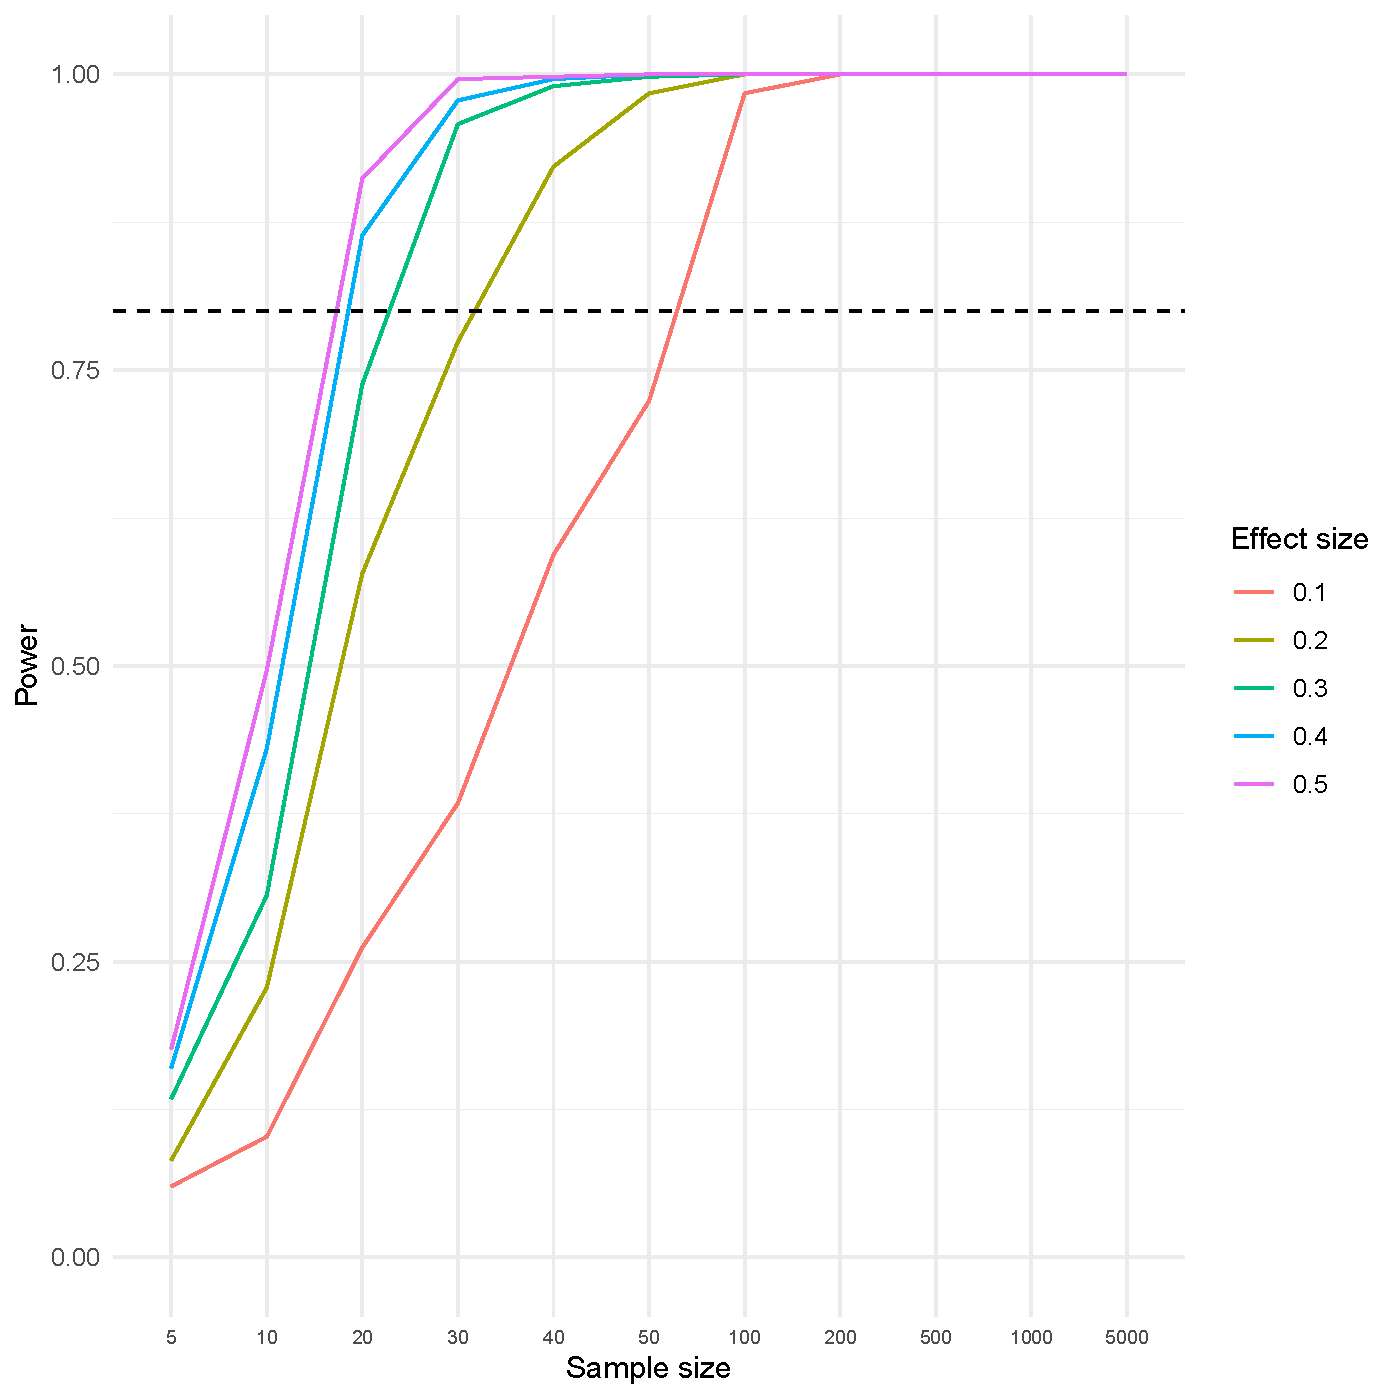
Figure 5.7: Power as a function of sample size and effect size for a uniform-based distribution. Curves for effect size: from right to left = from 0.10 to 0.50 effect size.
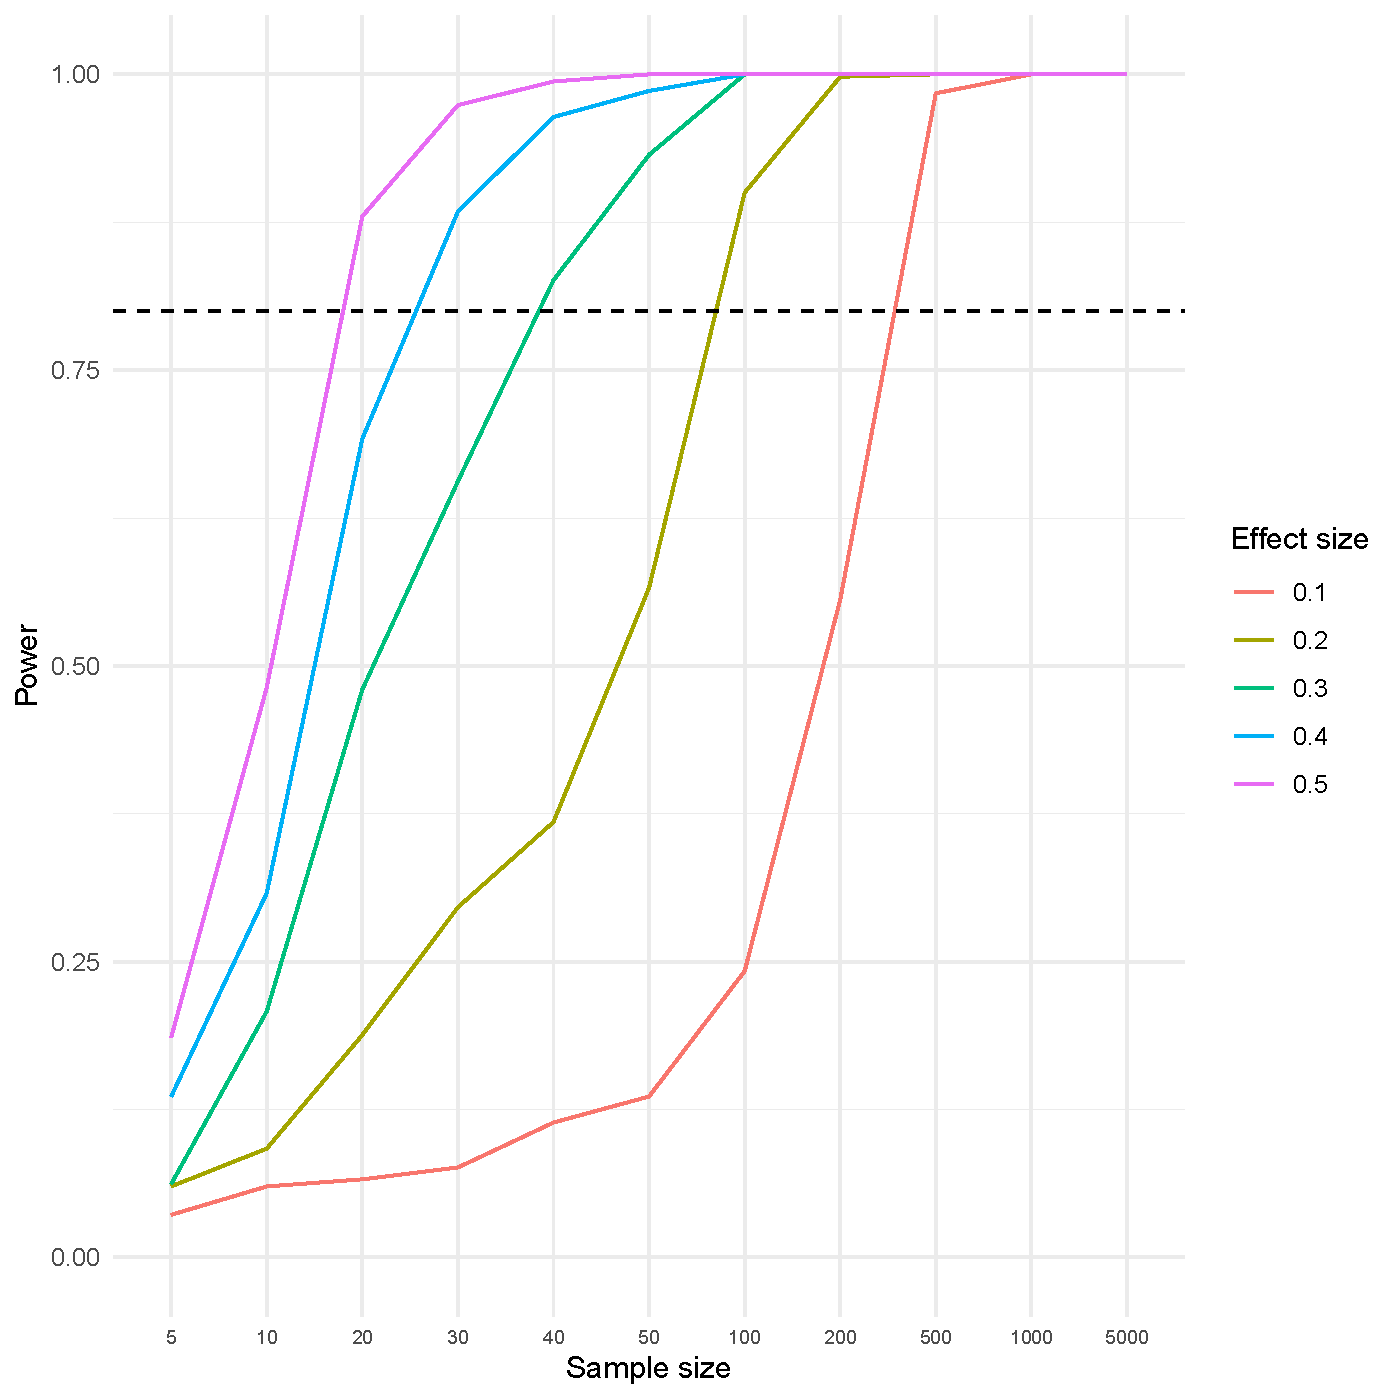
Figure 5.8: Power as a function of sample size and effect size for a truncated normal-based distribution. Curves for effect size: from right to left = from 0.10 to 0.50 effect size.
5.7 Reverse causality
Reverse causality occurs when the direction of cause and effect between two variables is the opposite of what is assumed or hypothesized. It may invalidate causal interpretations in observational studies. Reverse causality may also be a concern in NCA. When a hypothesis is formulated in NCA, it is expected that \(X\) causes \(Y\) and not that \(Y\) causes \(X\): first \(X\), then \(Y\) and not first \(Y\), then \(X\). NCA requires having a theoretical expectation (formal necessity hypothesis, see Chapter 7) that defines the causal direction. For example, if it is hypothesized that the presence or high level of \(X\) is necessary for the presence or high level of \(Y\), with \(X\) on the horizontal axis and \(Y\) on the vertical axis, the upper-left corner of the \(XY\)-plot is the expected empty corner (Section 3.5 and Chapter 7).
If the temporal order is not guaranteed by the study design (Section 8.2.1), and if it cannot be theoretically excluded, an observed empty area in the upper-left corner could not only represent high-high \(X \rightarrow Y\)-necessity (presence of high level of \(X\) is necessary for presence or high level of \(Y\)), but could also represent low-low \(Y \rightarrow X\)-necessity (absence or low level of \(Y\) is necessary for absence or low level of \(X\)), thus implying that \(Y\) is a necessary cause of \(X\) (low-low-necessity). This is illustrated in Figure 5.9 where the hypothesized causal condition is shown on the left and the alternative causal direction on the right. In Figure 5.9-right the \(XY\)-plot is rotated 180 degrees in the vertical and horizontal directions, such that the empty corner appears in the lower-right corner. \(Y\) is now on the horizontal axis and \(X\) on the vertical axis. This visualizes that a high level of condition \(Y\) ensures (is sufficient for) a certain minimum level of outcome \(X\), and the ‘ceiling line’ becomes a ‘floor line’. If such an effect can be theoretically justified (namely that a single cause ensures a certain minimum level of the outcome), the observed empty area in the upper-left corner (Figure 5.9-left) has an alternative causal interpretation: \(Y\) is a low-low necessary cause of \(X\): absence of \(Y\) is necessary for absence of \(X\). Testing ‘forward’ necessity causality (\(X \rightarrow Y\)) in the true presence of reverse causality (\(Y \rightarrow X\)) may lead to false positive conclusions. However, this risk may be absent or low when reverse necessity causality is unrealistic (e.g., human life does not cause oxygen) or when, in multicausal phenomena, a single variable is unlikely to produce the outcome at a certain level. When reverse causality is not excluded by study design or theoretically, potential reverse causality should be considered.58
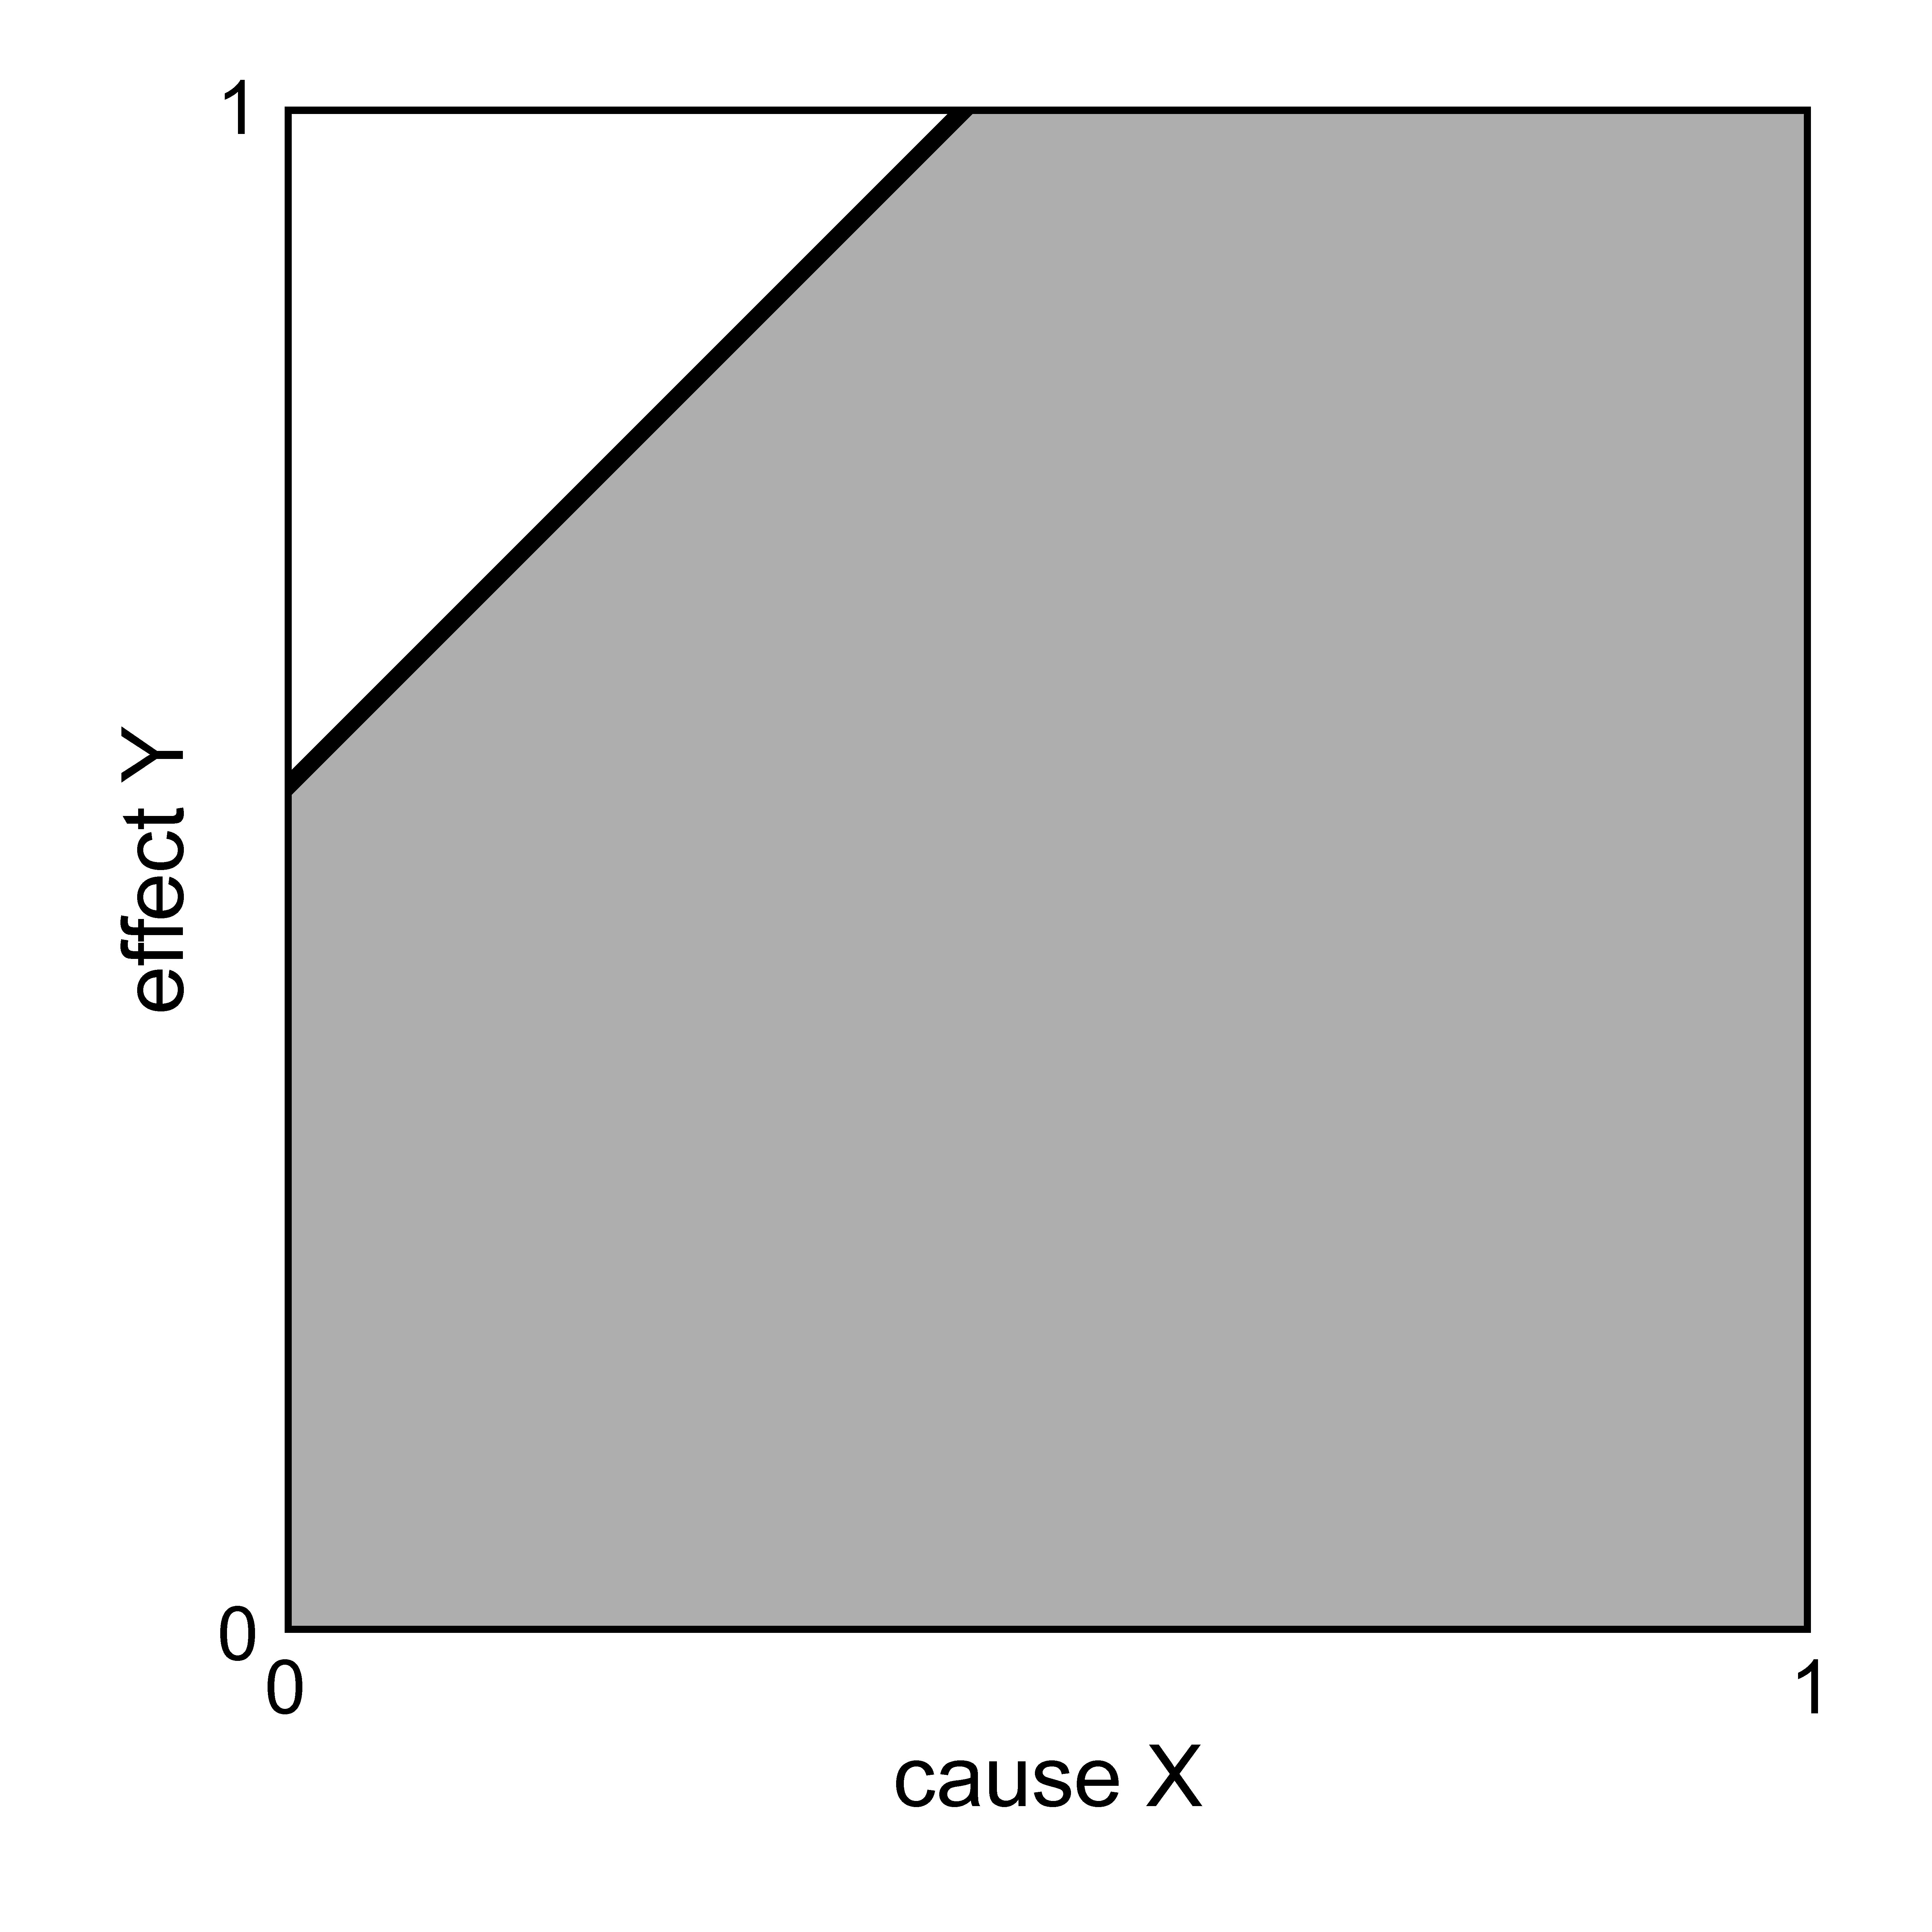
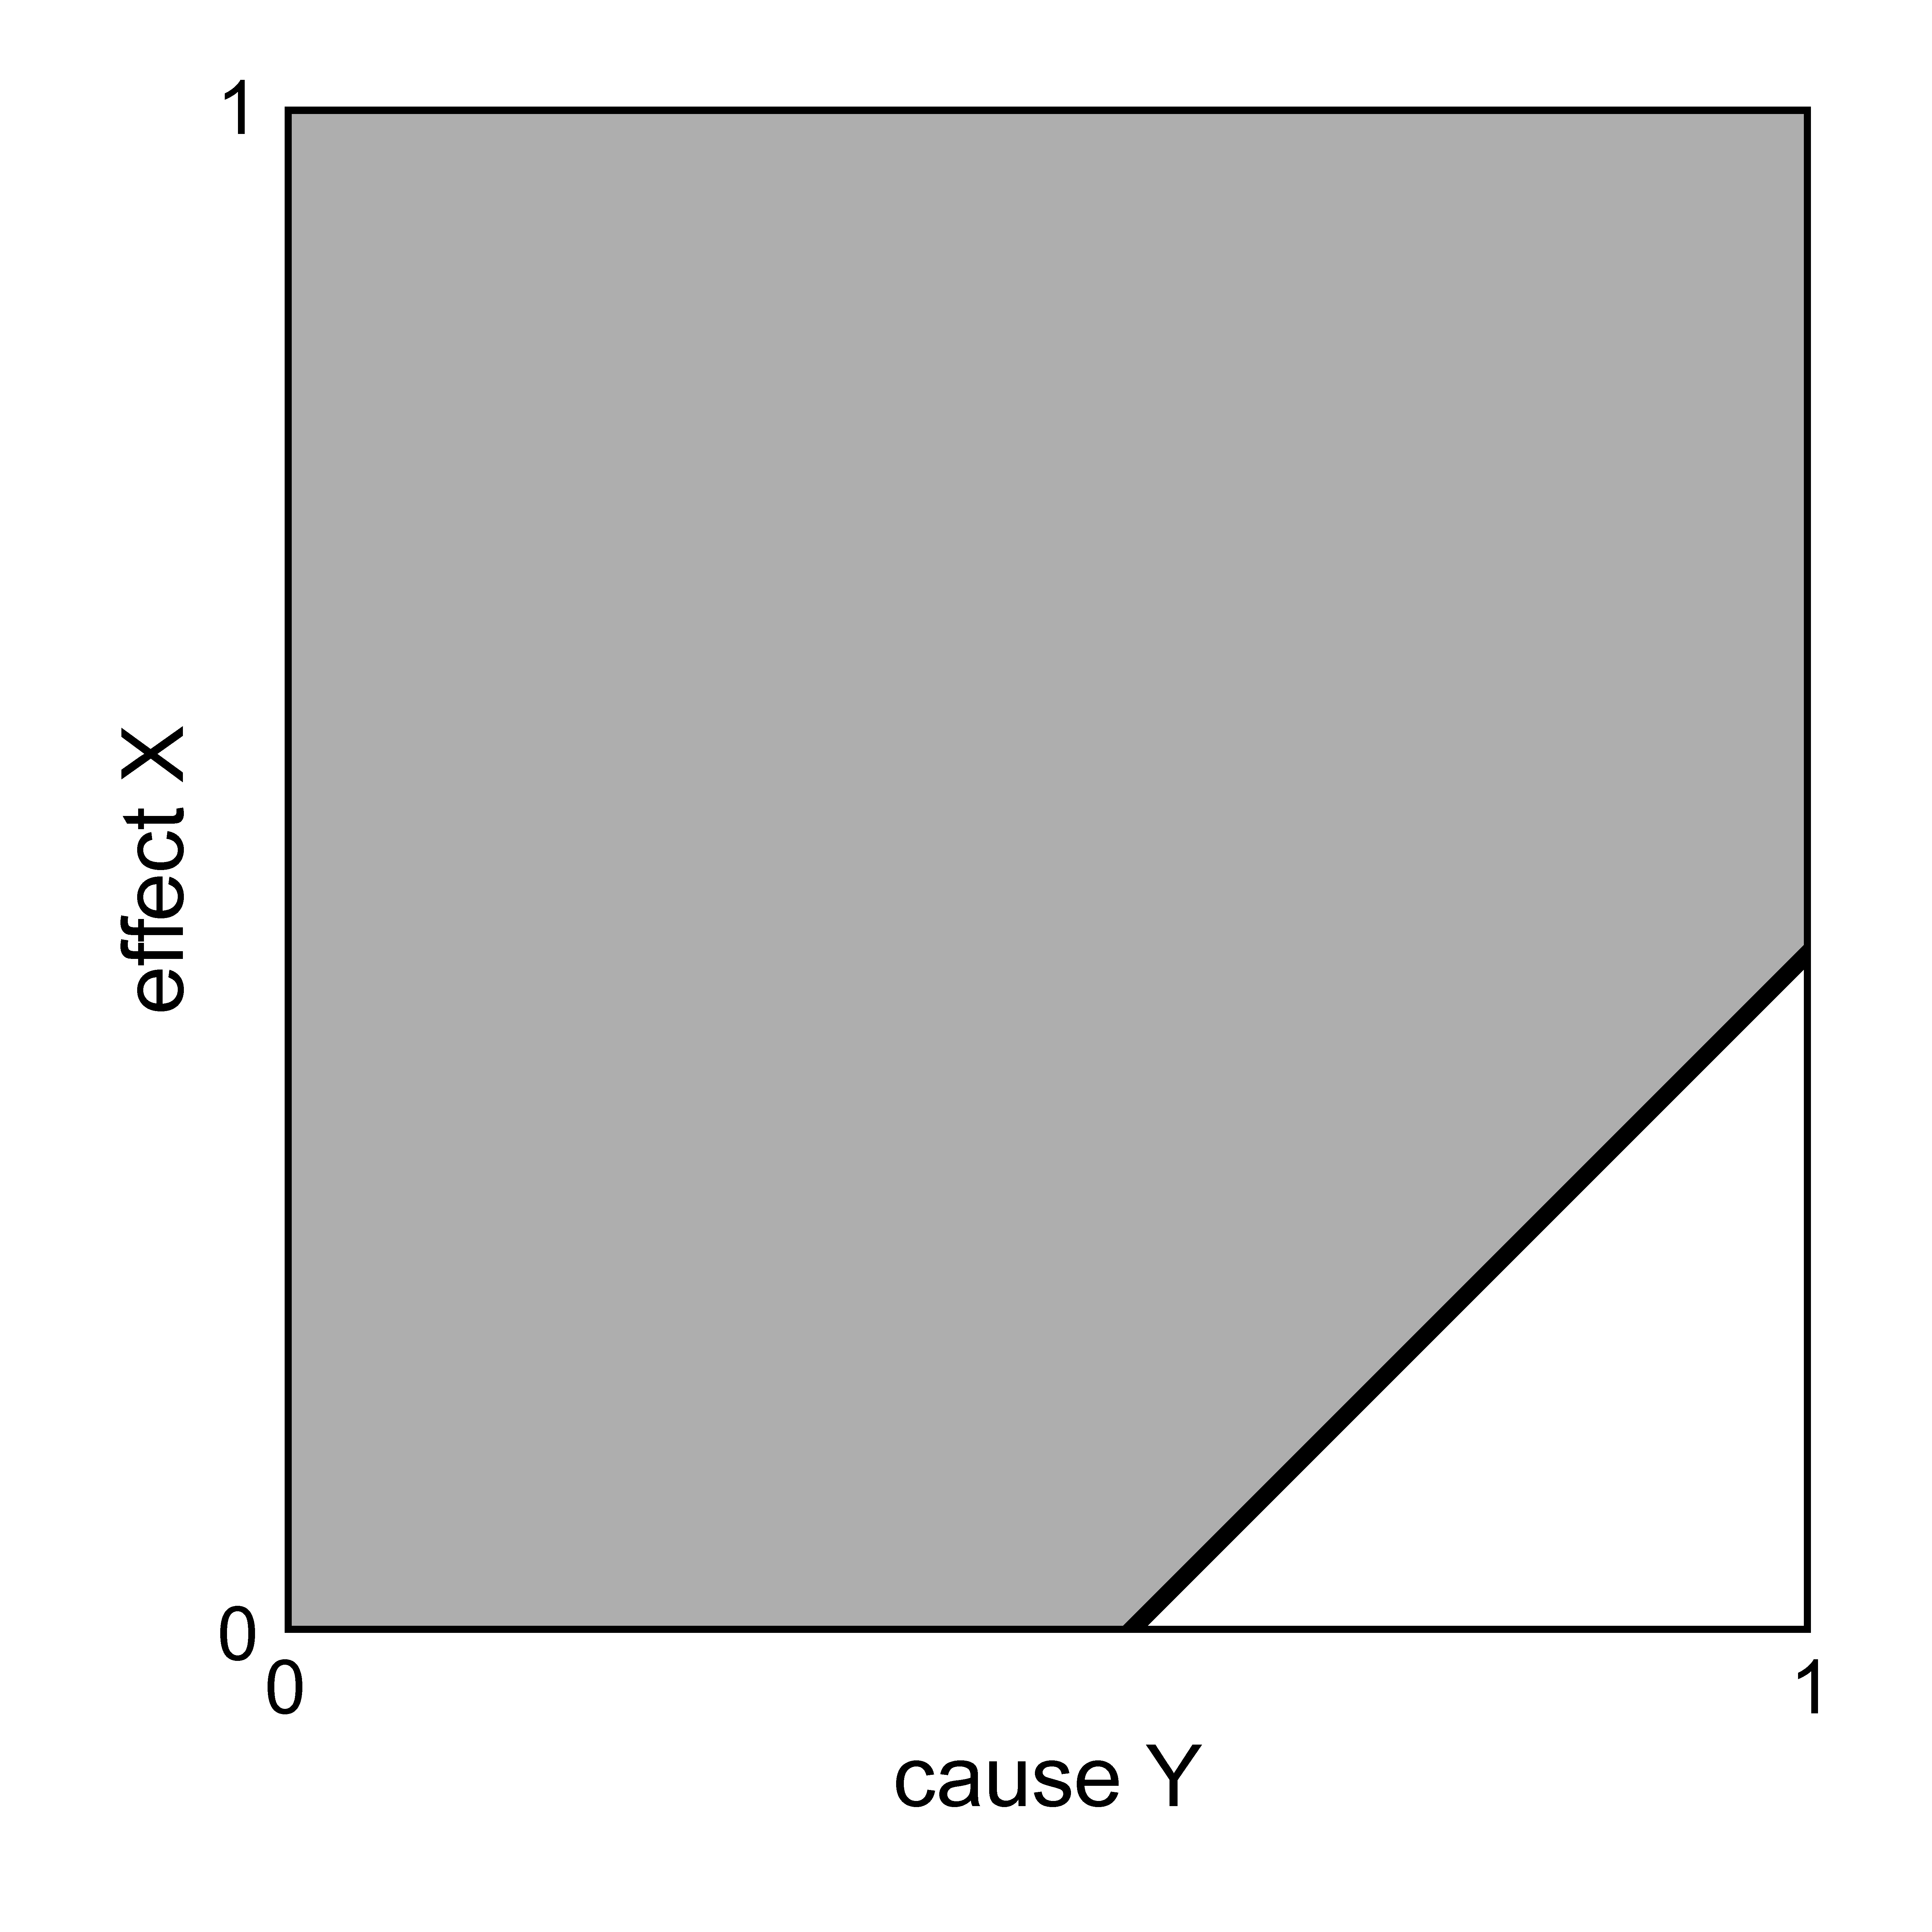
Figure 5.9: Reverse causality in NCA. Left: Expected empty area: X causes Y. Right: Possibility of reverse causality: Y causes X.
5.8 Measurement error
For valid estimations, many methods assume no measurement error in the data; NCA is no different. Measurement error may occur in practice and this affects the findings. In NCA, the effect of measurement error depends on the location of the affected cases. Cases with measurement error that are near the ceiling zone can have a strong influence on the effect size. A case with measurement error may be in the otherwise empty area. This would result in an underestimation of the effect size. Measurement error in cases that are far below the ceiling line generally do not influence the effect size (depending on the size of the measurement error). When the analysis is done with the empirical rather than theoretical scope (Section 4.3), cases with measurement error that are near the borders of the bounding box can affect the size of the box and thus the necessity effect size. Cases with measurement error that can have a large influence on the effect size, are treated in NCA as potential ceiling or scope outliers that can be analyzed separately (Section 9.8).
5.9 Spuriousness
5.9.1 Lack of theoretical support
An observed relationship is spurious when an alternative causal explanation is more credible, either because it is theoretically more plausible or it fits the empirical evidence better. In NCA, an apparent effect size may be spurious for several reasons.
The first important reason is the lack of theoretical support: the absence of a convincing necessity hypothesis. During the development of a formal hypothesis, thought experiments are used to make plausible that without \(X\) it is not possible to obtain \(Y\). (Chapter 7). Empty spaces in an \(XY\)-plot can arise from many reasons other than necessity. The importance of a strong theoretical justification is illustrated by the fact that NCA rejects necessity when such a hypothesis is not available (Section 6.2).
This is also important because NCA lacks a diagnostic signal in the data indicating that a relationship could be spurious. In particular, the observed effect size is insensitive to including or excluding third variables in the analysis.59 This contrasts with regression analysis, where adding a third variable, such as a confounder that causes both \(X\) and \(Y\), as a control variable will often change the regression coefficient of the hypothesized \(XY\) relationship (omitted variable bias when the third variable is excluded). This signals that the original \(XY\)-relationship may be spurious.60
In the context of NCA, a third variable \(Z\) that is considered a sufficiency cause for \(X\) (produces \(X\)) and a necessity cause for \(Y\), may be a better causal explanation for the observed empty space in the \(XY\)-relationship than the necessity of \(X\) for \(Y\). If so, the original hypothesis about the \(XY\)-relationship may be considered spurious. Considering a third variable \(Z\) (provided that theoretical support is available for it) as being sufficient for \(X\) and necessary for \(Y\) allows conducting a multiple NCA in which both \(X\) and \(Z\) are evaluated as potentially necessary conditions. However, including the third variable in the analysis does not change the effect size of the \(XY\) necessity relationship; instead it can add an explanation of what enables \(Y\).
For example, for driving a non-automatic electric car, having the handle in the Drive position (\(X\)) is necessary for the car to drive (\(Y\)). Furthermore, a driver (\(Z\)) is sufficient for positioning the handle in the Drive position (but not necessary as the handle may already be in the Drive position or another person may place it there). A driver is also necessary for the car to drive (but not sufficient, because \(X\) and many other conditions must also be satisfied). NCA would identify both \(X\) and \(Z\) as necessary conditions if the necessity pattern is observed and theoretical support is available. The estimated effect size for the \(XY\) relationship, as estimated from the observed XY data pattern, is not affected by assumptions on the presence or absence of \(Z\). Moreover, \(Z\) does not make the data pattern of the \(XY\) relationship spurious.
Only when theoretical support for the \(XY\)-relationship is lacking or weak can it be helpful to consider an alternative necessary condition \(Z\) that is also sufficient for \(X\), to assess theoretically whether the observed \(XY\) effect size may be attributable to that causal structure. For example, based on an example presented by Mahoney (2007), suppose the situation that an analyst proposes a weak hypothesis that having no beard (\(X\)) is necessary for pregnancy (\(Y\)), and observes a statistically significant necessity effect size that meets NCA’s criteria for non-rejection. A more credible alternative explanation is that oestrogen (\(Z\)) is necessary for pregnancy, and sufficient for having no beard. This theoretical reasoning reveals that the original hypothesis is not defensible. Thus, possible spuriousness in NCA lies not in the data pattern but in the theory attached to it. Claiming that a theoretically justified \(XY\) necessity relationship is spurious due to a third variable \(Z\) that is sufficient for \(X\) and necessary for \(Y\), amounts to proposing a competing theoretically justified and empirically supported causal explanation in which \(Z\) is a sufficient cause for \(X\) and a necessary cause for \(Y\) and that this alternative explanation is more credible.
In general, it is not easy to find theoretically justified sufficiency relationships involving a single sufficiency cause, except when variables are conceptually very similar. Potential sufficiency relationships of \(ZX\) can be analyzed with NCA by analyzing the lower-right corner of the \(ZX\)-plot (or the lower-right corner of the \(XZ\)-plot when \(X\) is considered as a sufficient cause for \(Z\) and a necessary cause for \(Y\)).
5.9.2 Low-quality data
The second important reason is inadequate data. For estimating necessity from sample data, it is essential that the sample represents the population of interest. This target population must be part of the theoretical domain, which is the universe of cases where the theory (formal necessity hypothesis) is expected to hold (also called boundary conditions, scope conditions, range of applicability, contextual constraints, etc.).
When the sample is drawn from a population that is (partly) outside the theoretical domain, or when the sample is selective (sampling a subgroup of the population), the sample is not representative and existing necessity may not be identified; in that case the observed “non-necessity” relationship is spurious (a false negative conclusion). The same holds for samples that are too small to identify an existing necessity relationship in the population (lack of power, see Section 5.6). Similarly, with a sample from outside the theoretical domain, a non-existing necessity relationship may be observed but is spurious (a false positive conclusion).
An additional requirement is that the sample covers all possible combinations of variables, such that cases near the expected empty corner are included. Because population characteristics are normally unknown, adequate coverage can be achieved through random sampling (also needed to meet the requirements for NCA’s statistical test) to obtain a large-n sample, or through replication studies with new samples from the same population. If these requirements are not met, the identified empty space (or non-empty space) may be spurious (Section 5.2).
Unreliable or invalid measurement of \(X\) or \(Y\) (Section 5.8) may also result in spuriousness. The same applies to inappropriate data transformations (e.g., nonlinear transformations) that distort the data pattern (Section 8.5.2).
With a well-specified necessity theory (Chapter 7) and adequate data (Chapter 8), the risk of spurious necessity relationships can be substantially reduced, though never fully eliminated.
References
In qualitative (small-n) applications of NCA, such as case studies, purposive case selection can be used without conducting statistical tests, see Section 8.2.3.↩︎
In the context of statistical testing, this book may use the term “support” of a hypothesis in the meaning of “non-rejection”↩︎
NCA’s statistical model differs from a regression model. The regression model is discussed in Section 11.3.1, see Equation (11.1).↩︎
The
nca_randomfunction in theNCAsoftware can be used to generate data from a population with a specified linear ceiling line (intercept and slope) for two types of distributions (uniform-based and truncated normal-based).↩︎Additional simulations have been done with different distributions (Massu et al., 2020) but these results are similar and are not reported here.↩︎
A pre-study power analysis for the Null test can be done with the
nca_powerfunction in theNCAsoftware.↩︎To keep computation time reasonable, the number of permutations to estimate NCA’s \(p\)-value for a given sample is limited to 200, and the number of resamples is set to 500; more accurate power estimations are possible with more permutations and more resamples.↩︎
The uncertainty about the temporal order between \(X\) and \(Y\) could be a reason for doing time-lagged study or a necessity experiment. See Section 8.2.↩︎
This is also an attractive feature when interpreting observational data causally.↩︎
Regression models describe the conditional expectation \(E[Y\mid X]\), i.e., the central trend of \(Y\) given \(X\). In a two-dimensional \(XY\)-plot, a fitted line shows the unadjusted bivariate association between \(X\) and \(Y\). When potential confounders are included in a multiple regression model, the conditional (adjusted) trend may differ from the unadjusted line, often with different intercepts and slopes. The unadjusted relationship is sometimes referred to as total (bivariate) effect (including the influence of confounders), whereas the adjusted relationship corresponds to the net effect, isolating the association between \(X\) and \(Y\) after accounting for confounding. The difference between adjusted and unadjusted association can be used as a diagnostic tool for potentially spurious relationships.↩︎