9 Data analysis
9.1 Summary of this chapter
In the previous chapters, the formal hypothesis was developed (Chapter 7) and the dataset with scores of condition(s) \(X\) and outcome \(Y\) became available (Chapter 8). This chapter focuses on testing the hypothesis quantitatively by analyzing the data using the NCA software in R. First, the example that is used to illustrate the analysis is presented (Section 9.2). After the hypotheses are formulated, the steps for testing them with the data are: (1) Model specification (Section 9.3); (2) Selection of model evaluation criteria (Section 9.4); (3) Visual inspection of the \(XY\)-plot (Section 9.5); (4) Ceiling line estimation (Section 9.6); (5) Effect size and \(p\)-value estimation (Section 9.7); (6) Outlier analysis (Section 9.8); (7) Model fit metrics calculation (Section 9.9); (8) Necessity-in-kind decision (Section 9.10); (9) Bottleneck analysis for necessity-in-degree (Section 9.11); (10) Robustness checks to evaluate the sensitivity of the findings for choices made in steps (1), (2), and (6) (Section 9.12).
9.2 Illustrative example
In this chapter, the elements of NCA’s data analysis are illustrated with the example called nca.example that is part of the NCA software (Appendix B). Before any data analysis with NCA can start, a formal necessity hypothesis (Chapter 7) and an adequate dataset (Chapter 8) must be available.
The formal necessity hypothesis for the illustrative example is as follows:
Hypothesis: Individualism is necessary for Innovation performance (high-high).
Focal unit = Country.
Concept \(X\) = Individualism: the extent to which a country’s people feel independent, as opposed to being interdependent as members of larger wholes.
Concept \(Y\) = Innovation: the country’s transformation of knowledge into new products, processes, and services.
Theoretical domain = All countries in the world.
Causal explanation = (Summary) Enabler: In highly individualistic societies, individuals have greater freedom to experiment and propose disruptive ideas, which contributes to producing innovative products and services. Constraint: Without enough individualism, potential innovators lack the autonomy and psychological safety to transform ideas into innovations, such that high levels of a country’s innovation are not achievable. No substitute: R&D infrastructure, financial resources, or government policies or other known contributing factors to innovation cannot compensate for the absence of an individualistic mindset. Temporal aspects: Individualism must be present before innovation is possible, must stay present to maintain innovation and is needed in all time periods.
The example’s data consists of archival data (Section 8.5.1), collected from two different sources. Data on cultural dimensions were obtained from Hofstede’s (1980) country cultures study. The value for a country’s Risk taking was obtained by subtracting the country’s Uncertainty avoidance from 135. Data on Innovation performance are from a study by Gans & Stern (2003) on innovation differences between countries. Both studies are large-n observational studies. By combining the datasets, a convenience sample of 28 countries with information on the three variables was obtained. Scores for the cultural variables are aggregated questionnaire item scores (for details see Hofstede, 1980). Scores for Innovation performance equal the country’s innovation index (Gans & Stern, 2003). The data and how they were obtained have the following characteristics:
Study design = observational study.
Sampling = convenience sampling (two different sources); n = 28 countries.
Measurement = Individualism by questionnaires; Innovation performance by document analysis.
Dataset =
nca.example(part of theNCAsoftware forR).
9.3 Model specification
NCA’s model specification consists of specifying the bounding box and the ceiling line (Section 4.3).
9.3.1 Bounding box specification
NCA assumes that \(X\) and \(Y\) are bounded variables \((x_{min}, x_{max}, y_{min}, y_{max})\) (Section 4.3). The bounds define the bounding box where observations could be possible given the extreme values of \(X\) and \(Y\). Two types of bounding boxes can be distinguished.
The bounding box with a theoretical scope is defined by theoretical bounds of \(X\) and \(Y\).80 It may be that theoretical limits exist, such as for human body temperature \((27^\circ{C} \le T \le 44^\circ{C}\)). The theoretical bounds may be known or approximated (e.g., from previous empirical studies). It is also possible that \(X\) and \(Y\) are measured on scales with known minimum and maximum values, such as Likert scales or percentage scales.
The bounding box with an empirical scope is defined by the minimum and maximum values of \(X\) and \(Y\) that are observed (in the dataset). This option is often selected when theoretical bounds are unknown. It can also be selected to avoid overestimation of the effect size.
In a situation where groups of similar cases are compared (e.g., measured at different time points in a longitudinal study, resamples from a population in simulation study), the theoretical or scale minima and maxima or the observed minimum and maximum values of the pooled dataset should be selected as the common theoretical scope of each single group for comparability (Sections 5.3.7 and 8.2.2.2).
In the illustrative example, the empirical scope is selected. The scales used for collecting the data do not have minimum and maximum values and no strong theoretical rationale exists for selecting other extreme values for \(X\) and \(Y\) than those observed in the dataset.
9.3.2 Ceiling line specification
Specifying the ceiling line involves choosing the location (relative to an empty corner) and the form.
The location depends on the direction of the hypothesis (Section 3.5), which defines the expected empty corner. The proposed hypothesis of the illustrative example is a high-high hypothesis where presence/high value of \(X\) is necessary for presence/high value of \(Y\). Therefore, the expected empty corner is the upper-left corner of the \(XY\)-plot (corner 1).
Next to the location, also the form of the ceiling line needs to be specified (Sections 4.3.2 and 4.4). NCA assumes that the ceiling line is non-decreasing. A linear ceiling line (e.g., CR-FDH or C-LP) may be specified when the border between the area with and without cases is theoretically assumed to be linear, which is the most common assumption. The CR-FDH ceiling allows some noise above the ceiling such that the ceiling zone is not perfectly empty near the ceiling line (see model fit metric noise, Section 4.5.4). This line may be selected when noise exists in the data such as measurement error. The C-LP line may be selected when the data are obtained from high-quality measurement approaches, or are perfect as for example in simulated data. This line may also be selected to ensure that the linear ceiling line has no cases in the ceiling zone. The default CR-FDH ceiling is often selected when the condition and outcome have many levels (e.g., are continuous).
For modeling purposes, a linear ceiling line may be attractive (Sections 4.3.2.3 and 4.4.1.3). For a given bounding box, it requires only two parameters such as ceiling intercept and ceiling slope. These parameters may be theoretically decided (e.g., based on earlier data or other knowledge) or empirically estimated with the data. The latter is most commonly used.81 Although estimation of a ceiling line and effect size are not needed when the ceiling line and scope are predefined, the other steps of the data analysis are still relevant.
A segmented linear (non-decreasing) ceiling line (e.g., CE-FDH or CE-VRS) may be specified when the border is non-linear (but non-decreasing). The CE-FDH ceiling is a piecewise linear function where peers (dominant points) are connected by line segments (Sections 4.3.2.1 and 4.4.1.1). CE-FDH is a stepwise linear ceiling line that connects peers with horizontal and vertical line segments. The CE-VRS is a concave piecewise linear ceiling with linear segments that connect a selection of the CE-FDH peers such that the ceiling is concave (Sections 4.3.2.2 and 4.4.1.2). When estimated from data, both lines do not have points in the ceiling zone. CE-FDH may also be selected when the condition or outcome have few levels (e.g., are discrete) or when the ceiling line is irregular or non-linear. When the non-linearity is concave, the CE-VRS line may be an option. The default segmented ceiling line is CE-FDH.
For modeling purposes, a piecewise linear ceiling line may be attractive for an irregular border between feasible area and ceiling zone because it can better follow the non-linearity (though non-decreasing) of the border than a linear ceiling line. It is less attractive when the number of line segments is large. This requires a large number of parameters to specify the model, which makes the model complex (see the model fit metric complexity Section 4.5.1) and has the risk of overfitting (Section 9.9.1).
Analysts should critically reflect on the choice of ceiling line prior to conducting the analysis, and aim to select a ceiling line that is expected to best suit the study (Section 5.5). The most commonly used ceiling lines are the default lines CE-FDH for non-linear ceilings and discrete variables, and CR-FDH for linear ceilings and continuous variables.
In the illustrative example, the ceiling line is specified in two steps. Since the \(X\)- and \(Y\)-data are continuous and it is not expected a priori that the border is non-linear, the linear default ceiling line (CR-FDH) is provisionally selected. After exploration of outliers (Section 9.8) and model fit (Section 9.9), a better ceiling line may be selected (if available) to test the hypothesis.
9.4 Selection of evaluation criteria
NCA applies three main criteria for a binary decision to reject or non-reject (support) a necessary condition hypothesis: adequate theoretical support, a sufficiently large effect size, and a low \(p\)-value.82 For non-rejection all three criteria must be satisfied: theoretical support, a large effect size (\(d\)) and a small \(p\)-value (Section 6.2). If any of these criteria is not satisfied, the hypothesis is rejected. The first requirement can be satisfied if a formal necessity hypothesis is available that gives the required theoretical support. The process of developing a formal necessity hypothesis is discussed in Chapter 7.83 The other two criteria are discussed below.
9.4.1 Effect size threshold
Generally, the larger the effect size, the more practically relevant the necessary condition. For the binary decision about the hypothesis, a threshold level must be selected. Ideally, the selection is based on practical considerations: the minimum level of \(d\) that is considered relevant for practice. Since such a consideration may be difficult, analysts often select the arbitrary benchmark suggested in Dul (2016b): \(d\) = 0.10. However, in situations where a weak constraint can have significant consequences, a lower threshold level may be selected; when consequences are costly or critical, a higher threshold may be needed.
In the illustrative example, the selected effect size threshold is \(d\) = 0.10.
9.4.2 \(p\)-value threshold
The \(p\)-value is meant to reduce the risk of false positive conclusions: concluding that a non-existing necessary condition exists. A high \(p\)-value suggests that the observed data are compatible with the null of no relationship (Section 5.3). For this purpose, a threshold \(p\)-value (\(\alpha\)) is selected to evaluate if the observed effect size is statistically significant, meaning that the data are not compatible with the null hypothesis (the data may be compatible with an alternative hypothesis). The threshold \(p\)-value must be small enough to make it plausible that the observed effect size is not compatible with the situation of no effect between \(X\) and \(Y\). Often, \(\alpha\) = 0.05 is selected. For exploration, a higher threshold level (\(\alpha\) = 0.10) is sometimes applied. For claims of new discoveries, Benjamin et al. (2018) suggest using \(\alpha\) = 0.005.
In the illustrative example, the selected \(p\)-value threshold is \(\alpha\) = 0.05, which is commonly used.
9.4.3 Selection of target outcome
For the practical application of NCA results, it is (optionally) possible to specify the target outcome \(y_c\), which is a specific level of \(Y\) that is considered relevant for practical action. The model estimates the corresponding target condition level \(x_c\) that is necessary for achieving the target outcome. If necessity-in-kind (NiK) is supported and a bottleneck analysis of necessity-in-degree (NiD) is warranted (see below Sections 9.10 and 9.11), NCA identifies the condition target level required to make the desired target outcome possible. A bottleneck case is a case that does not satisfy the necessary level \(x_c\) for achieving the target level \(y_c\). Bottleneck cases may be the focus for practical action based on NCA results (Chapter 12).
If the outcome is desirable (e.g., performance), the target outcome is the minimum performance level that must be achieved. If the outcome is undesirable (e.g., disease), the target outcome is the maximum level of the condition below which the undesired target outcome will not occur. These “rules” apply to all cases.
In the illustrative example, the outcome is desired (innovation performance). The selected target outcome is “very good innovation performance”, defined as the level corresponding to the 90th percentile in the dataset, that is, being part of the top 10% performers.
9.5 Visual inspection of the \(XY\)-plot
After hypothesis formulation, data collection, model specification and selection of evaluation criteria, the starting point for NCA’s data analysis is a visual inspection of the \(XY\)-plot. This is a qualitative examination of the data pattern. By visual inspection the following questions can be answered:
- Is the expected corner of the \(XY\)-plot empty?
- Is the selected ceiling line appropriate (or if the ceiling line is not specified: what is an appropriate ceiling line)?
- Which cases are possibly outliers?
- What is the data pattern in the rest of plot?
An \(XY\)-plot for the illustrative example can be produced using the NCA software for R as follows:84
# Load the NCA package and the example
library(NCA)
data(nca.example)

# Run the NCA analysis
model <- nca_analysis(nca.example, 1, 3, ceilings = "cr_fdh")
nca_output(model, summaries = FALSE)
With this code the \(XY\)-plot is displayed where \(X\) = Individualism and \(Y\) = Innovation performance. All 28 cases are shown as dots (Figure 9.1-left). The plot also shows the selected ceiling line (CR-FDH).85 Figure 9.1-right shows the same plot and now with annotations for the visual inspection.86
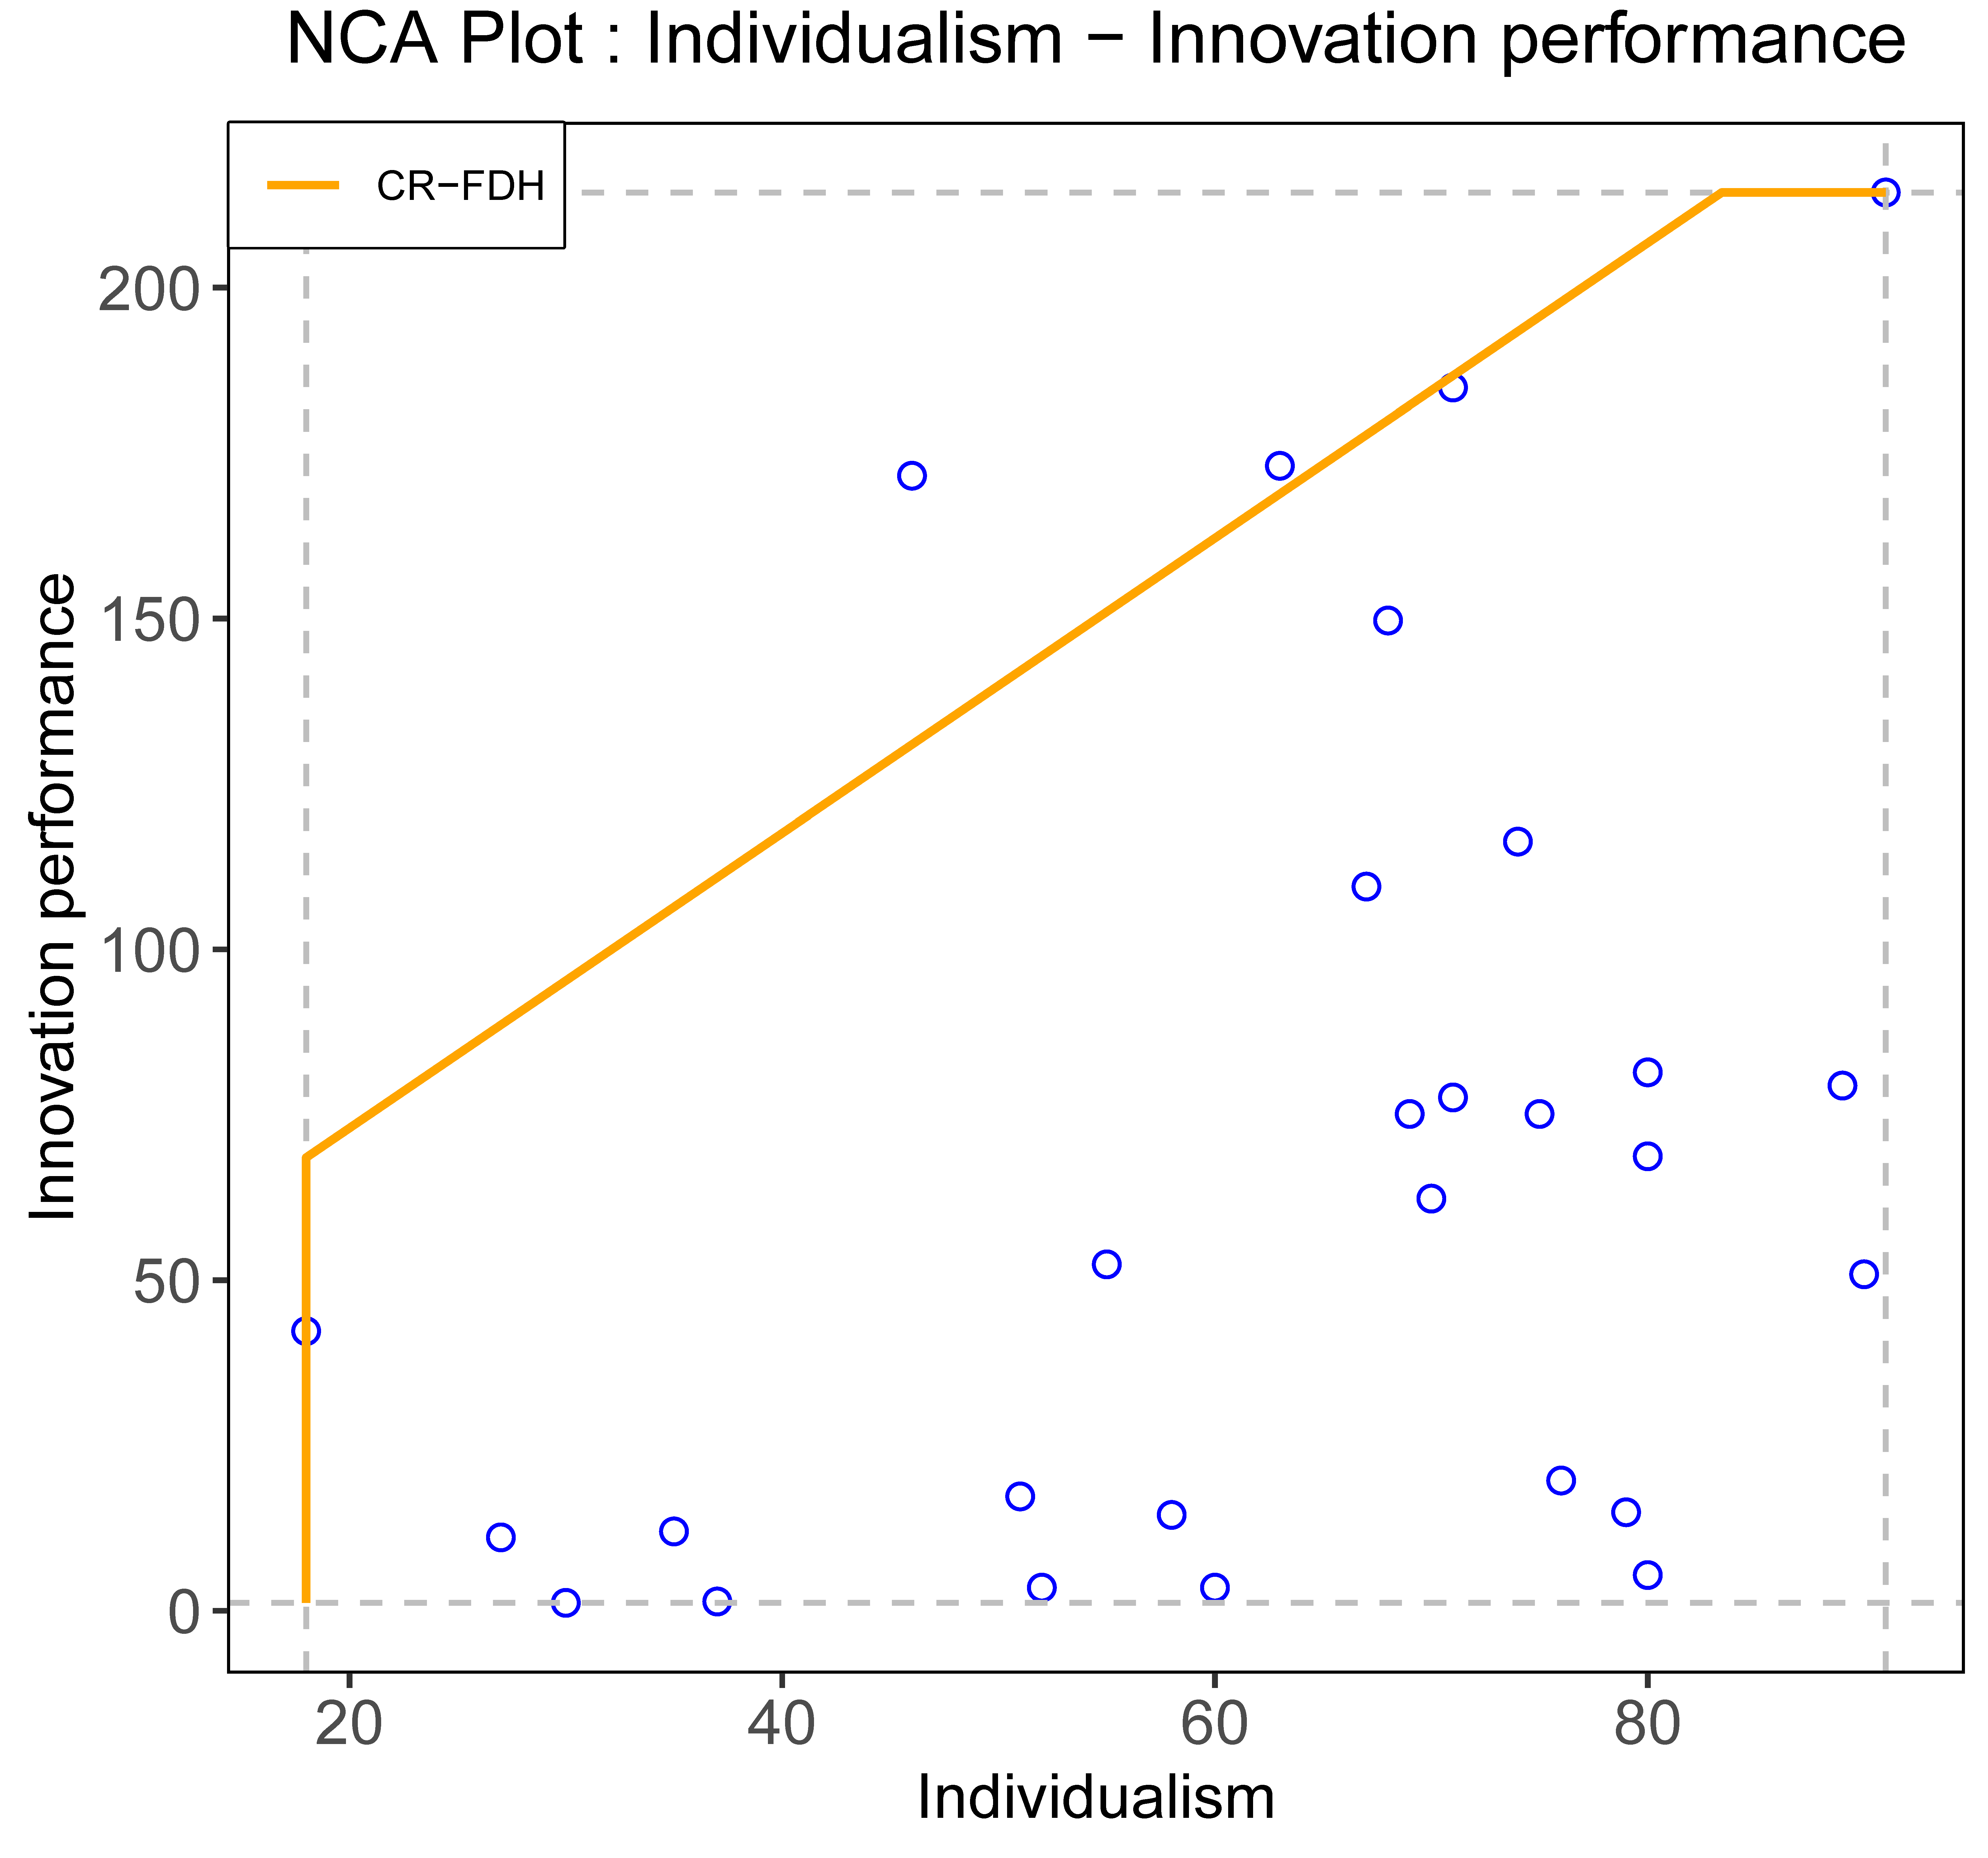
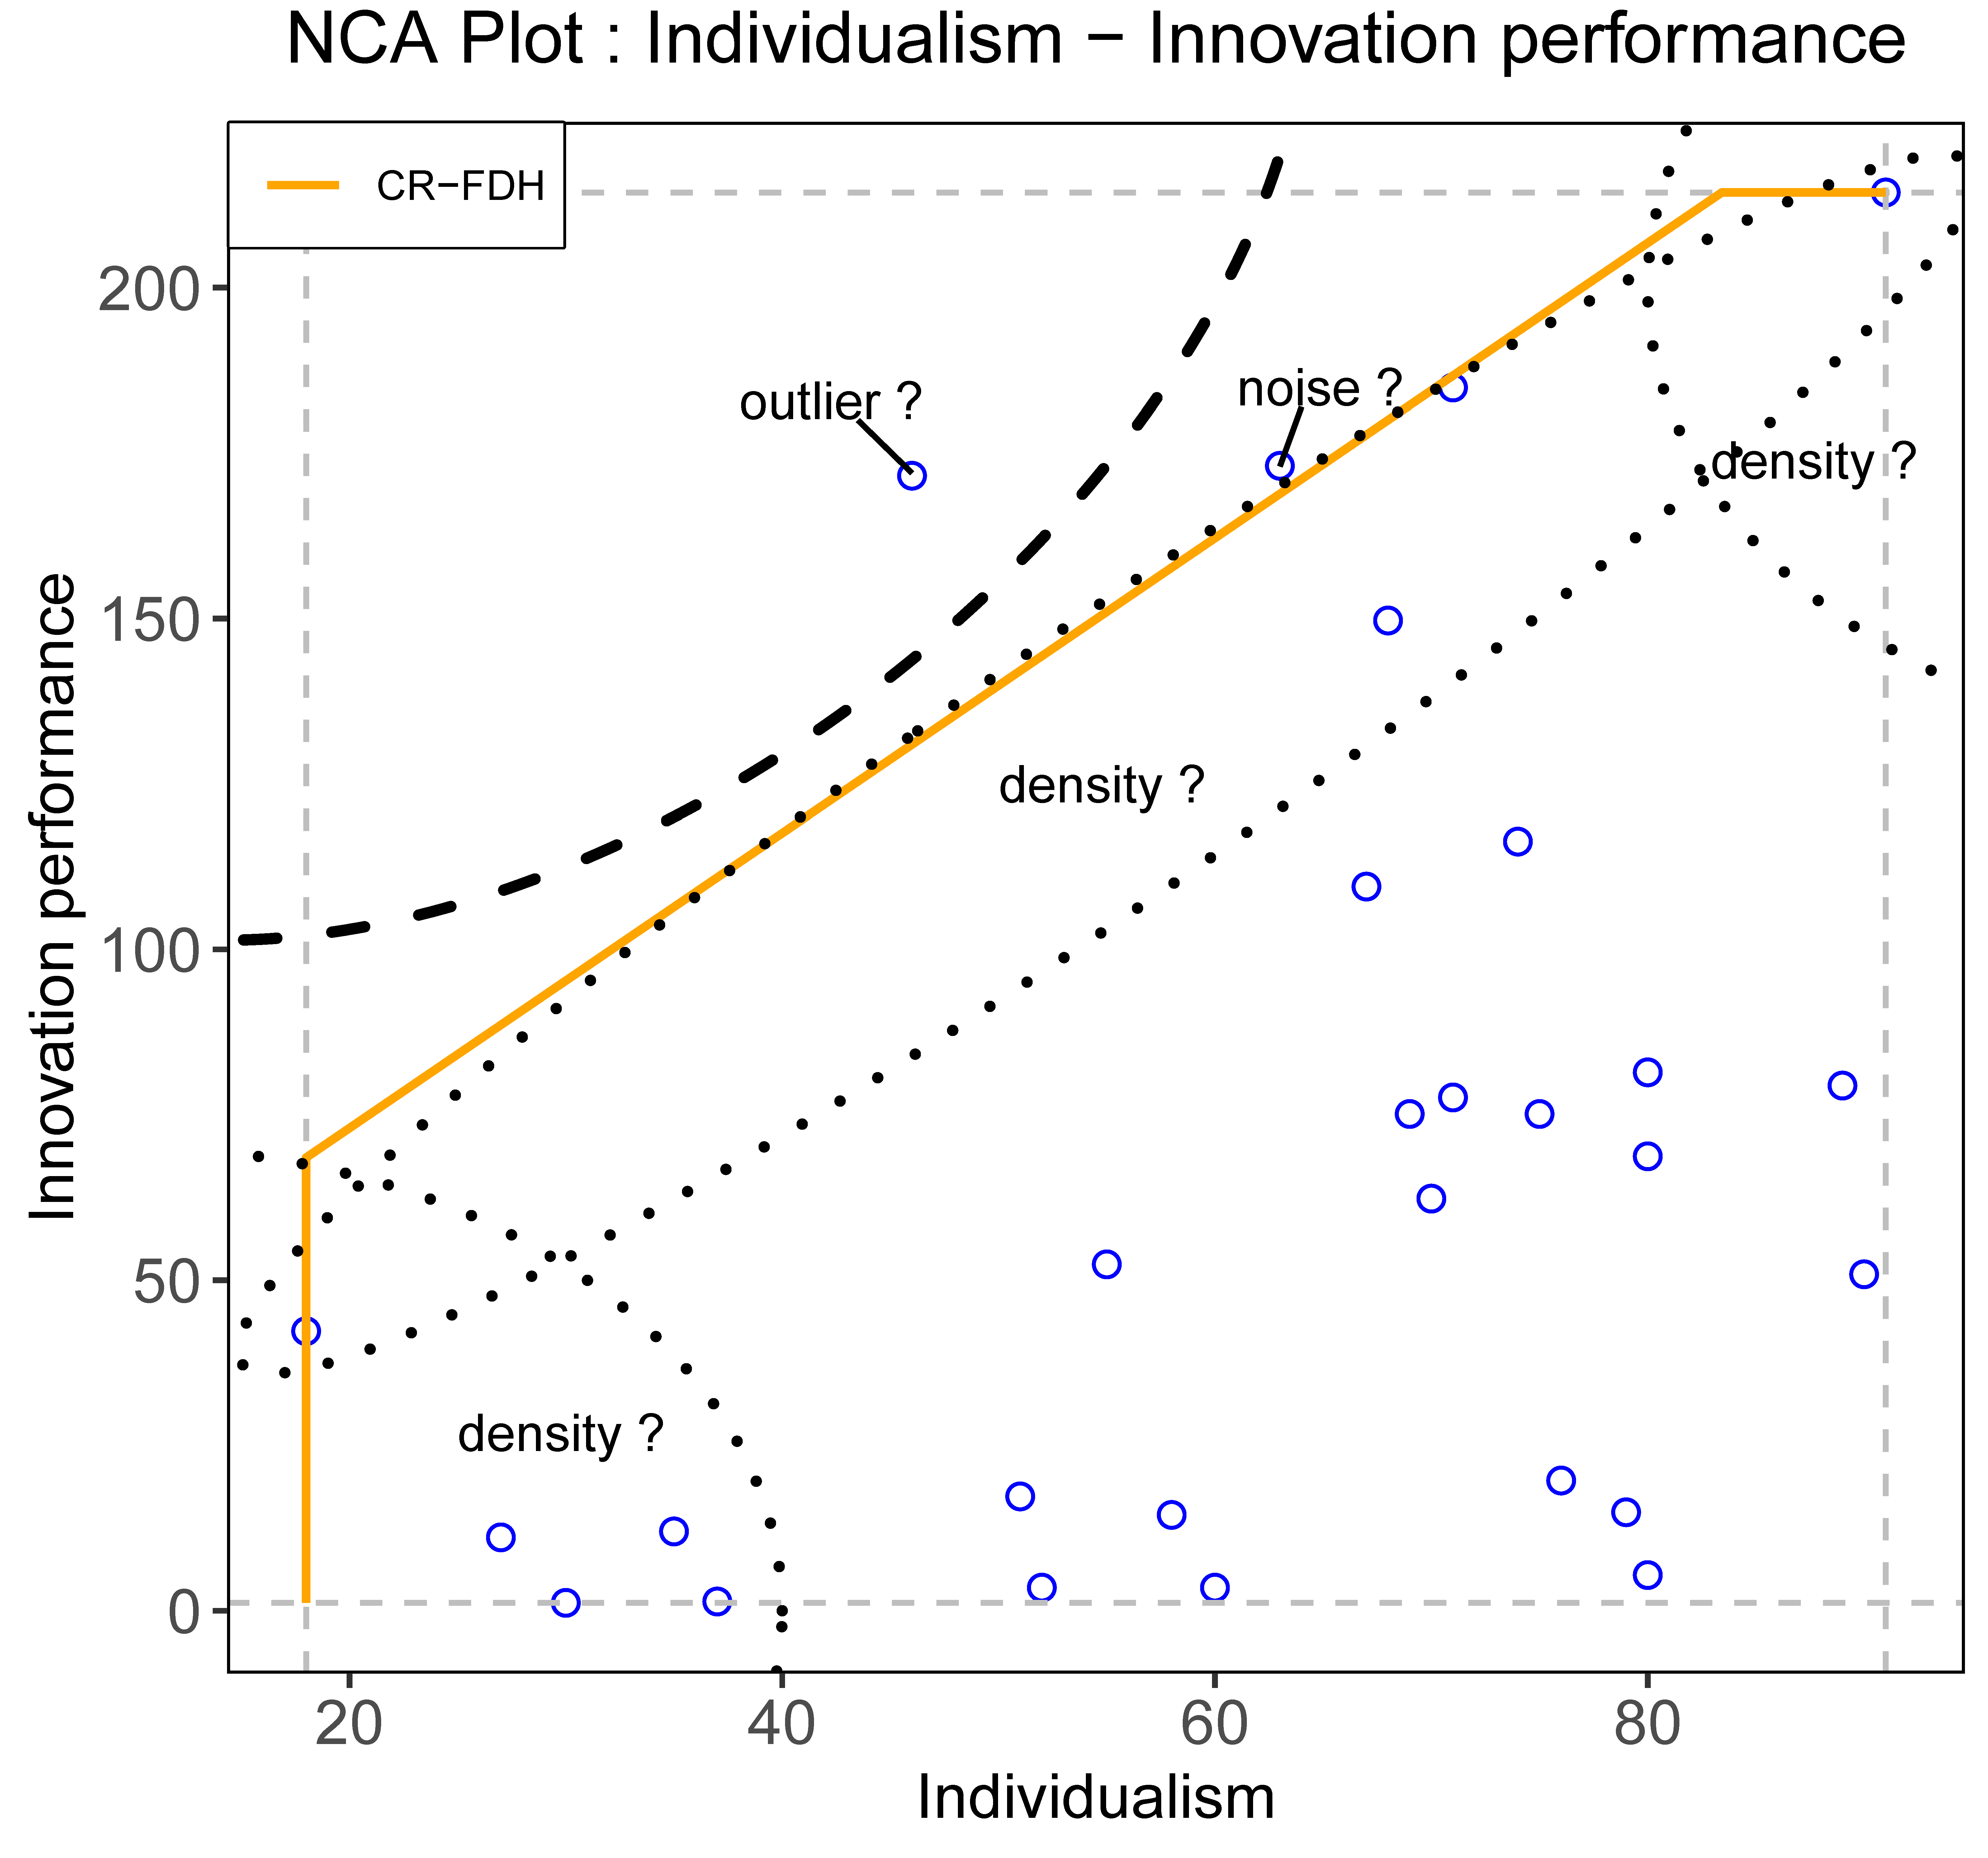
Figure 9.1: Visual inspection of the \(XY\)-plot of the illustrative example. Left: output from the NCA in R package. Right: same output with annotations.
9.5.1 Is the expected corner empty?
According to the hypothesis, a high level of \(X\) is necessary for a high level of \(Y\) such that the upper-left corner is expected to be empty. Figure 9.1 shows, generally, that cases with a low value of \(X\) have a low value of \(Y\), and that cases with a high value of \(Y\) have a high value of \(X\). The upper-left corner is indeed empty. A non-empty expected empty corner with cases near the geometrical corner would have indicated that the hypothesis should be rejected, unless only a few cases are located there without cases in the surrounding empty area; such cases could be outliers and would need further inspection. One case in Figure 9.1 could be a candidate outlier, see Section 9.5.3.
9.5.2 Is the selected ceiling line appropriate?
In the illustrative example the border is assumed to be linear, and the CR-FDH ceiling line is (provisionally) selected during the model specification. However, the \(XY\)-plot shows that the border is somewhat irregular. This suggests that representing the border by a linear ceiling may not be optimal, causing model fit issues. This will be evaluated in more detail using model fit metrics (Section 9.9).
9.5.3 Which cases are possible outliers?
Outliers are cases that are relatively ‘far away’ from other cases. NCA defines an outlier as a case that has a large influence on the effect size when removed (Section 9.8). This means that cases that help to produce the ceiling line (peers) and cases that define the empirical bounding box (observed minimum and maximum values of \(X\) and \(Y\)) are potential outliers. Isolated potential outliers may be identified by visual inspection of the \(XY\)-plot and may give rise to conducting a formal outlier analysis (Section 9.8).
In the illustrative example, one point is located in the apparent ceiling zone relatively far away from other points and from the ceiling line (Figure 9.1). This point is a candidate for being an outlier case, and an outlier analysis is therefore warranted. The other points in the ceiling zone (above the ceiling) also contradict strict necessity, but may not be considered an outlier but rather noise because the point is closer to other points and to the apparent ceiling line. Noise may, for example be due to measurement error, and can be captured with the model fit metric noise (Section 4.5.4).
9.5.4 What is the data pattern in the rest of the plot?
Although NCA focuses on the analysis of the expected empty corner and the ceiling line, the distribution of cases in the rest of the \(XY\)-plot can also be informative for the credibility of necessity (Chapter 6). In particular, the density of cases near the ceiling line and density of cases in adjacent corners to the empty corner (upper-right and lower-left) may contain information that is relevant for necessity.
9.5.4.1 Density of cases near the ceiling line
Cases just below the ceiling line ‘support’ the ceiling line. With no or very few cases just below the ceiling line, the line may not be informative. The informativeness of the ceiling line is captured with NCA’s model fit metric called support (Section 4.5.5).87
The cases near the ceiling should not be clustered but preferably spread along the ceiling line. The spread of the ceiling line is captured with NCA’s model fit metric spread (Section 4.5.5). In the illustrative example, the cases near the ceiling line do not seem to be clustered and are reasonably spread.
Theoretically, the ceiling line represents a sharp border between the area with and the area without cases. This means that the densities just below and just above the ceiling should be different with considerably more cases just below the ceiling compared to just above the ceiling. This feature of the ceiling line is captured in NCA’s sharpness metric (Section 4.5.6).
In the illustrative example, few cases are present just below the ceiling and the densities just below and just above the ceiling are not very different, such that the ceiling is not a sharp border.
9.5.4.2 Density of cases in adjacent corners
The presence of many cases in the lower-left corner, and/or in the upper-right corner, may be supportive for the non-randomness of the necessary condition. If only a few cases are present in these corners, the emptiness of the upper-left corner could be a random effect. To mimic the null-distribution where \(X\) and \(Y\) are unrelated, NCA’s permutation test re-samples from the observed sample while shuffling labels of observations (see NCA’s null hypothesis test, Section 5.3.3). To challenge randomness, it is important that enough cases are in the upper-right or lower-left corners. If these cases do not exist, the \(p\)-value will be high, resulting in a rejection of the necessity hypothesis, despite the presence of an expected empty corner and possibly despite presence of a necessary condition in the population (false negative conclusion).
In the illustrative example, it appears that a reasonable fraction of cases is present in the lower-left corner, suggesting that the \(p\)-value may be small such that the necessity explanation of the observed empty corner is not rejected. Section 9.7 presents the formal evaluation of the effect size regarding statistical significance.
9.6 Ceiling line estimation
During model specification (or after visual inspection of the \(XY\)-plot) the location and form of the ceiling line are specified. When the specific ceiling parameters (Section 4.3.3) are not yet available (the most common situation) NCA estimates these parameters. For a linear ceiling line these are the intercept and the slope, for a segmented linear ceiling line these are the coordinates of the peers. For most types of ceiling lines (CE-FDH, CR-FDH, CE-VRS, CR-VRS, C-LP) this is done by first estimating the Free Disposal Hull (Section 4.4). The CE-FDH ceiling line corresponds to this line, whereas the other ceiling lines are derived from this line by using all or a selection of peers or otherwise based on the peers (C-LP) as explained in Section 4.3.2.
In the illustrative example, the CR-FDH ceiling line is selected (Figure 9.1-left), but without specifying its parameters (ceiling line intercept and ceiling line slope). The ceiling line parameters can be estimated with the NCA software for R as follows:
library(NCA)
data(nca.example)

# Run the NCA analysis with the specified ceiling line
model <- nca_analysis(nca.example, 1, 3, ceilings = "cr_fdh")

# Extract intercept & slope
Intercept <- nca_extract(model = model,
                         x = "Individualism",
                         ceiling = "cr_fdh",
                         param = "Intercept")
Slope     <- nca_extract(model = model,
                         x = "Individualism",
                         ceiling = "cr_fdh",
                         param = "Slope")

# Print the ceiling line equation
cat(
  "Ceiling line equation (CR-FDH):  Y =",
  round(Intercept, 3), "+",
  round(Slope, 3), "* X", "\n"
)
## Ceiling line equation (CR-FDH): Y = 28.353 + 2.23 * XThe estimated ceiling intercept is 28.353 and the estimated ceiling slope is 2.23.
9.7 Effect size and \(p\)-value estimation
The effect size (Section 4.4.1) can be calculated from the ceiling zone (Section 4.3.2) and the scope (Section 4.3). The ceiling zone is calculated from the (estimated) parameters of the ceiling line. The scope is calculated from the observed or theoretically determined minimum and maximum values of \(X\) and \(Y\). The effect size is the test statistic for NCA’s permutation test to estimate the \(p\)-value (Section 5.3).
For the illustrative example, the calculations and estimations can be done with the NCA software for R. The number of repetitions for obtaining the permutation distribution for estimating the \(p\)-value is set at 10,000. This number generally balances accuracy and computation time.
library(NCA)
data(nca.example)

# Run the NCA analysis with the specified ceiling line
# 10,000 repetitions for estimating the p-value
set.seed(123) # for reproducibility of the estimated p-value
model <- nca_analysis(nca.example, 1, 3,
                      ceilings = "cr_fdh",
                      test.rep = 10000)
## Setting up parallelization, this might take a few seconds... Do test for : cr_fdh - IndividualismDone test for: cr_fdh - Individualism# Show the results
print(model) ##
## ---------------------------------------------------------------------------## Effect size(s):## cr_fdh p
## Individualism 0.31 0.168
## ---------------------------------------------------------------------------During the computation a message “Do test for: …” appears when the analysis is running, which changes into “Done” when the analysis is finished. The results show that the effect size \(d\) = 0.31, which is greater than the selected threshold level of \(d\) = 0.10. However, this result is not statistically significant given the estimated \(p\)-value of 0.168 for the selected threshold level of \(\alpha\) = 0.05. Therefore, the initial conclusion is that the hypothesis is rejected.88
9.8 Outlier analysis
Including or excluding outliers from a data analysis can change the results. This applies to any data analysis method, and also to NCA. In NCA, an outlier is an ‘influential’ case that has a large influence on the necessity effect size when removed.
9.8.1 Outlier types
Because the effect size is calculated by dividing a numerator (ceiling zone) by a denominator (scope), and an outlier is defined by its influence on this division (effect size), two types of outliers can exist in NCA: ceiling outliers and scope outliers.
A ceiling outlier is a case that helps to determine the position of the ceiling line and that largely changes the effect size if it is removed from the dataset. Since the peers determine the ceiling line, they are potential ceiling outliers. When a ceiling outlier is removed, it usually increases the ceiling zone and thus increases the necessity effect size. A scope outlier is a case that determines the empirical scope and that largely changes the effect size if it is removed. When a scope outlier is removed, it usually decreases the scope and thus increases the effect size. When a case is both a ceiling outlier and a scope outlier, it determines not only the position of the ceiling but also the size of the scope. When such a case is removed, it simultaneously decreases the ceiling zone and the scope. The net effect is often a decrease of the necessity effect size.
Duplicate cases are cases with exactly the same \(X\)- and \(Y\)-values. They are possible when the variable scores are discrete, for example when measured with a Likert scale. When duplicate cases determine the ceiling line or scope, the effect size will not change when only one of the duplicates is removed. Therefore, single cases that have a duplicate have no influence on the effect size when removed, and cannot be outliers. A set of duplicate cases can be outliers and can be removed as a set. Cases that are below the ceiling line and have no extreme values of \(X\) or \(Y\) cannot be outliers.
9.8.2 Outlier identification
There are no scientific rules for deciding if a case is an outlier. The decision depends primarily on a judgment by the analyst. For a first impression of possible outliers, the analyst may visually inspect the \(XY\)-plot as discussed in Section 9.5.3. In the literature, rules of thumb are used for identifying outliers. For example, a variable score is an outlier score ‘if it deviates more than three standard deviations from the mean’, or ‘if 1.5 interquartile ranges is above the third quartile or below the first quartile’. These pragmatic rules address only one variable (\(X\) or \(Y\)) at a time. Such single variable rules of thumb may be used for identifying potential scope outliers (unusual minimum and maximum values of condition or outcome), but they are not suitable for the identification of potential ceiling outliers. The reason is that ceiling outliers depend on the combination of \(X\)- and \(Y\)-values. For example, a case with a non-extreme \(Y\)-value may be a regular case when it has a large \(X\)-value, because it does not define the ceiling. Then removing the case does not change the effect size. However, when \(X\) is small, the case may define the ceiling; removing the case may change the effect size considerably. This means that both \(X\) and \(Y\) must be considered when identifying ceiling outliers in NCA.
All potential ceiling outliers and potential scope outliers can be evaluated one by one by calculating the absolute and relative effect size changes when the case is removed (with replacement).
Such an outlier analysis can be done with the NCA software for R using the nca_outliers function. The output is a list of potential outliers, ranked by how much the effect size decreases when the outlier is removed.89 For the illustrative example, the outlier analysis can be done as follows:
library(NCA)
data(nca.example)

# Run the NCA outlier analysis
outliers <- nca_outliers (nca.example, 1, 3, ceiling = 'cr_fdh')

# Show the results
print(outliers)
## outliers eff.or eff.nw dif.abs dif.rel ceiling scope
## 1 Japan 0.31 0.44 0.13 44.0 X
## 2 USA 0.31 0.22 -0.08 -26.8 X X
## 3 South Korea 0.31 0.36 0.06 18.2 X X
## 4 Finland 0.31 0.31 0.00 1.4 X
## 5 Sweden 0.31 0.30 0.00 -0.6 X
## 6 Mexico 0.31 0.31 0.00 0.1 XThe table shows in the first column the case names of the potential outliers. The second column displays the original effect size when no cases are removed (eff.or) and the third column displays the new effect size when the outlier is removed (eff.nw). The fourth column shows the absolute difference (dif.abs) between the new and the original effect sizes, and the fifth column the relative difference (dif.rel) between the new and the original effect sizes expressed as a percentage. A negative sign means that the new effect size is smaller than the original effect size.
The output shows six potential outliers. The new effect sizes range from 0.22 to 0.44, absolute differences range from −0.08 to +0.13, and relative differences range from −26.8% to +44%. Three outliers are just ceiling outliers (Japan, Finland, Sweden), one is just a scope outlier (Mexico), and two cases are both ceiling and scope outlier (USA and South Korea). South Korea defines the ceiling line and the minimum \(X\) of the scope. USA defines the ceiling line and maximum \(X\) and maximum \(Y\) of the scope. Mexico does not define the ceiling line but defines the minimum \(Y\).
For an inspection of the cases in the \(XY\)-plot, the plotly = TRUE argument in the nca_outliers function can be used to display an interactive plot with highlighted potential outliers (the static version is shown in Figure 9.2).
library(NCA)
data(nca.example)

nca_outliers (nca.example, 1, 3, ceiling = 'cr_fdh' , plotly = TRUE) 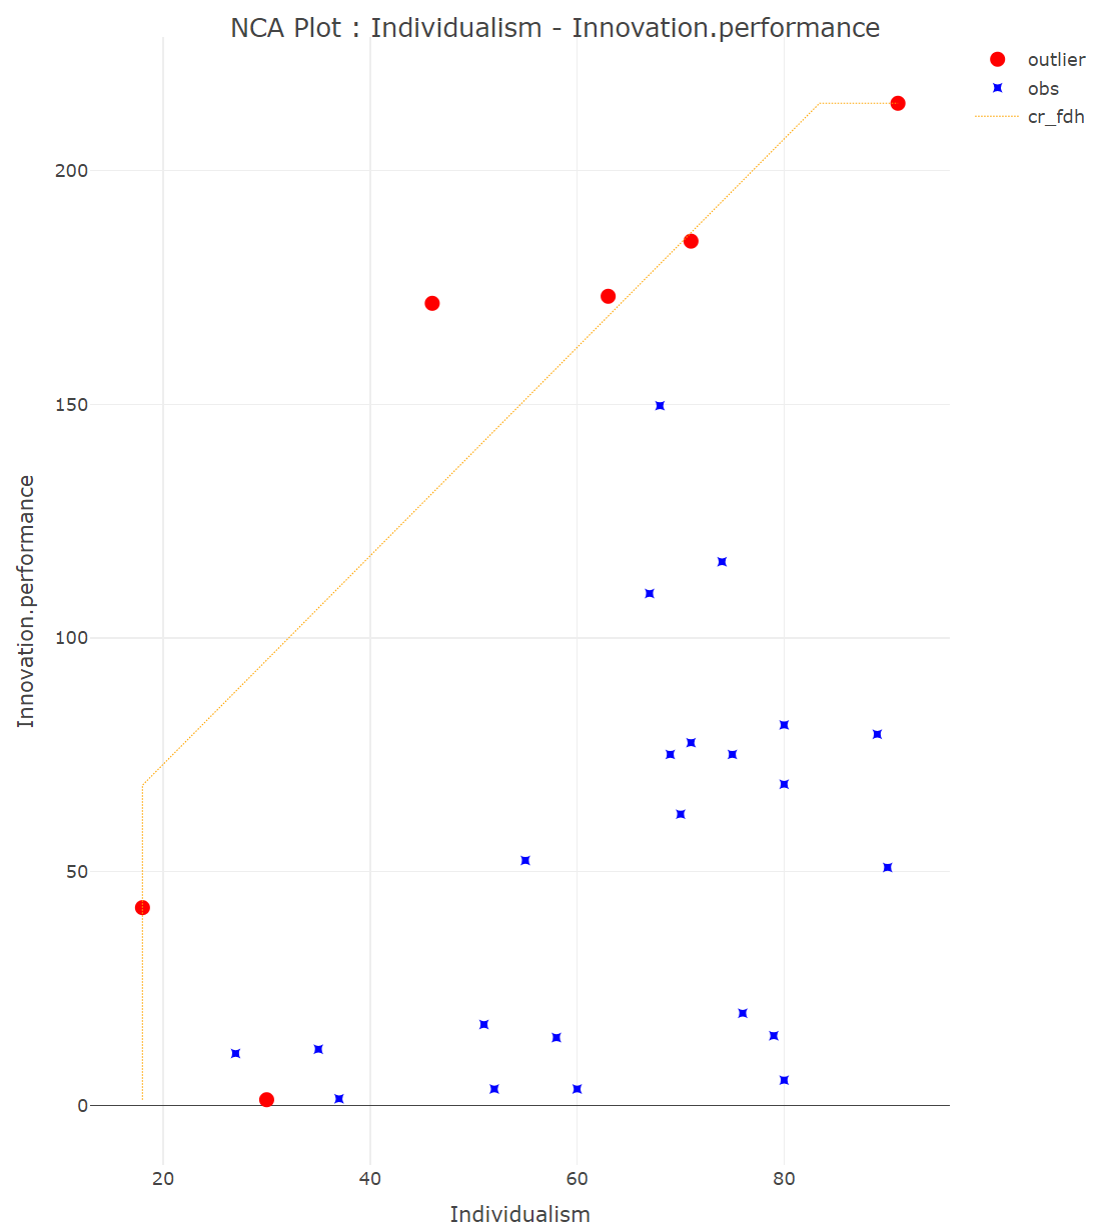
Figure 9.2: Plotly plot with potential ceiling and scope outliers distinguished from other observations.
From the three potential ceiling outliers that are not also a scope outlier (Japan, Finland, Sweden) and are in the center of the plot (Figure 9.2), two cases increase the effect size when removed, and one decreases it. The relative effect size differences when cases are removed range from −0.6% to 44.0%.90 The potential scope outlier that is not also a ceiling outlier (Mexico) increases the effect size when removed, but its influence is marginal. The two potential ceiling outliers that are also potential scope outliers, USA and South Korea, change the effect size when removed with relative effect size differences of −26.8% and 18.2%, respectively.
All other cases are not potential outliers because they have no influence on the effect size when removed. Note that after a potential outlier is removed and the effect size difference is calculated, the case is added again to the dataset before another potential outlier is evaluated (removing with replacement).
In the nca_outlier function it is also possible to evaluate two or more potential outliers at once by specifying \(k\) = number of potential outliers. This evaluates the change of effect size when \(k\) potential outliers are removed as a group (and replaced as a group). Evaluating multiple outliers is useful in the following situations:91
Existence of duplicate cases that are far from the other cases.
Existence of a cluster of cases that is far from the other cases.
Existence of multiple single cases that are not near each other, but far from the other cases.
Sometimes, removing more outliers does not lead to a larger change in effect size compared to removing just one or two of them. When the argument condensed = TRUE is used, these larger combinations are normally hidden from the results. However, a combination is still shown if it produces a larger effect size change than any other combination that does not include one of the cases in that combination. In other words, even with condensed = TRUE, a combination remains visible when it adds meaningful new information that cannot be explained by smaller or unrelated combinations.
The remaining combinations are sorted by how much they change the effect size (from largest to smallest). This is the absolute value of the difference between the original effect size and the new effect size. If several combinations cause the same change, smaller combinations are listed first. Only the top combinations are shown, up to the user-specified limit (default = 25).
For \(k\) > 2 the procedure repeats with a next round of identifying new outliers. In general, all possible \(\binom{n}{k} = \frac{n!}{k!(n-k)!}\) outlier combinations are evaluated, where \(k\) is the combination size and \(n\) is the total number of outliers found so far.
In the illustrative example, the results for \(k\) = 2 potential outliers are:
library(NCA)
data(nca.example)

outliers <- nca_outliers (nca.example, 1, 3, ceiling = 'cr_fdh', k = 2,
                          condensed = TRUE)
print(outliers)
## outliers eff.or eff.nw dif.abs dif.rel ceiling scope
## 1 Japan - South Korea 0.31 0.51 0.20 65.6 X X
## 2 Japan - Finland 0.31 0.50 0.19 63.1 X
## 3 Japan - Sweden 0.31 0.47 0.16 52.0 X
## 4 Japan - Mexico 0.31 0.44 0.14 44.1 X X
## 5 Japan 0.31 0.44 0.13 44.0 X
## 6 USA - Sweden 0.31 0.19 -0.12 -39.4 X X
## 7 USA - Finland 0.31 0.22 -0.09 -28.7 X X
## 8 USA 0.31 0.22 -0.08 -26.8 X X
## 9 USA - Mexico 0.31 0.22 -0.08 -26.7 X X
## 10 South Korea - Finland 0.31 0.38 0.07 23.6 X X
## 11 Japan - USA 0.31 0.37 0.06 20.5 X X
## 12 South Korea - Sweden 0.31 0.37 0.06 19.7 X X
## 13 South Korea - Mexico 0.31 0.36 0.06 18.3 X X
## 14 South Korea 0.31 0.36 0.06 18.2 X X
## 15 Japan - Austria 0.31 0.36 0.05 17.0 X
## 16 South Korea - Portugal 0.31 0.35 0.05 15.0 X X
## 17 USA - South Korea 0.31 0.28 -0.03 -9.3 X X
## 18 South Korea - Greece 0.31 0.31 0.01 2.3 X X
## 19 Finland - Mexico 0.31 0.31 0.00 1.5 X X
## 20 Finland 0.31 0.31 0.00 1.4 X
## 21 Finland - Sweden 0.31 0.31 0.00 1.1 X
## 22 Sweden 0.31 0.30 0.00 -0.6 X
## 23 Sweden - Mexico 0.31 0.31 0.00 -0.5 X X
## 24 Mexico 0.31 0.31 0.00 0.1 X## # Not showing 33 possible outliersThe output shows 24 combinations of potential outliers with the largest influence on the effect size when a combination of two outliers or a single outlier is removed (see dif.abs and dif.rel for the absolute and relative differences, respectively). A potential outlier combination consists always of at least one single outlier. Removing Japan in combination with South Korea, Finland, Sweden or Mexico, increases the effect size change. When Japan is removed in combination with other countries, the change of the effect is less than when only Japan is removed.92
From the example it appears that Japan is the most serious potential single outlier.
9.8.3 Outlier decision approach
After potential outliers are identified, the next question is what to do with them. NCA suggests a two-step approach for making a decision about an outlier. In the first step, it is evaluated whether the outlier is caused by a sampling or case-selection error, or a measurement error. In the second step, it is decided if an ‘outlier for unknown reasons’ should be part of the phenomenon (using the deterministic perspective on necessity) or if it should be considered an exception.
Figure 9.3: Outlier decision tree for Step 1 of the outlier decision approach.
In the first step of NCA’s outlier decision approach, the potential outlier case is selected. Next, it is evaluated if the case has sampling or case selection error. This refers to a case not being part of the theoretical domain of the formal necessity hypothesis. For example, the case may be a large company, whereas the necessity theory applies to small companies only. An outlier case due to sampling or case selection error should be removed from further analysis. If the case is not an outlier because of sampling or selection error, it should be evaluated if the case may have measurement error. The condition or the outcome may have been incorrectly scored, which could happen for a variety of reasons. If the case has measurement error and this error can be corrected, the outlier case becomes a regular case and is kept for the analyses.
If the measurement error cannot be corrected, two situations may apply. If the measurement error occurs in the outcome score, the case should be removed from further analysis of all necessary conditions (if there are multiple necessary conditions). If the measurement error occurs in the condition score, the case should be removed from further analysis of that condition, but the analyst must decide to keep it or remove it for the analysis of other conditions. This depends on the analyst’s judgement if the case is generally problematic, or only regarding the specific condition where it was identified as an outlier case (the case may not be an outlier case for other conditions).
If the outlier is not caused by sampling/selection error or measurement error or no information about sampling error or measurement error is available, the outlier may be considered an ‘outlier for unknown reasons’. The analyst may then decide to apply an outlier rule that is justifiable and convincing. A mechanistic outlier rule (e.g., based on percentages) to decide whether the case should be kept or removed is usually not desirable. Such rules are arbitrary but their consequences on the results are usually large. Therefore, applying a mechanistic outlier rule is generally not advised. If it is used anyway and outliers are removed mechanistically, it should be reported and justified, and a robustness check should be done comparing the results with and without applying the outlier rule (Section 9.12).
Note that concluding that necessity is rejected because of presence of outliers may be an important result. The condition may on average influence the outcome, but apparently it is not essential as cases exist that can compensate the absence or a low value of the condition. The outliers that reject necessity may be best or innovative cases that are able to achieve a desired outcome without or with a low level of the condition. If the outcome is undesirable, outlier cases may need different action to reduce the outcome than standard actions focused on the condition. In other words, outliers may be informative rather than being errors. Rejecting necessity due to outliers and discussing outliers may be a more valuable result than accepting necessity after removal of outliers. If no outlier rule is applied (the preferred approach), the potential outlier case is kept, and the next step of NCA’s outlier decision approach begins.
Figure 9.4: Outlier decision tree for Step 2 of the outlier decision approach.
The decision tree for the second step is illustrated in Figure 9.4. This picks up from the decision to keep the outlier case because the case has no known error, and no outlier rule is applied. To continue the analysis two perspectives are distinguished for necessity causality: the deterministic perspective, and the typicality perspective (Section 2.4.3 and Dul, 2024a). The deterministic perspective, in principle, does not allow points above the ceiling. However, some noise may be tolerated, namely when the case is close to the ceiling in the medium purity ceiling zone (Section 4.5.4). If this perspective is adopted the analysis continues with the outlier.
The typicality perspective, in principle, allows outlier cases that are further away from the ceiling, but only if they are rare. These outliers are called exceptions. Accepting the typicality perspective means accepting that the outlier is not an error but behaves differently than other cases with another (unknown) explanation than necessity. Thus, the typicality perspective can only be adopted if the case:
is a rare exception.
is (presumably) not an error.
is isolated and far from the ceiling (not noise).
behaves differently than other cases for unknown reasons.
If the typicality perspective is adopted, the analysis continues without the outlier, because it does not represent the necessity phenomenon that is studied. It can, however, be studied separately because of the unusual characteristic. Since a case without an error is removed from the analysis, a robustness check should be done with and without the exception to show how it affects the results.
If the typicality perspective is not adopted, the analysis continues with the outlier.93
In general, the handling of outliers (keep or remove) relies on a series of decisions made by the analyst. It is advised to perform robustness checks to evaluate the sensitivity of the results to specific outlier decisions and to report the results (Section 9.12).
In the illustrative example, the outlier approach is applied as follows. The case Japan is the only potential outlier to be considered. The first step of the outlier decision approach (Figure 9.3) is the evaluation of whether Japan could be an outlier case because of sampling/selection error. The theoretical domain of the hypothesis was defined as “all countries in the world” (Section 9.2). Japan is one of these countries, so sampling/selection error does not apply.
Next, the question is whether Japan’s scores for \(X\) and/or \(Y\) could have measurement error. This seems unlikely as these scores are obtained from a reputable archival dataset that has been widely used elsewhere, and discussions of measurement error specifically for Japan have not emerged before. The next consideration is to apply an outlier rule for Japan.
Since a mechanistic outlier rule is not preferred, and Japan is a ceiling outlier for which no generally accepted outlier rules are available, the result of the first step of the outlier decision approach is to keep Japan as outlier case for further consideration.
In the second step of the outlier approach (Figure 9.4) it is decided to consider Japan as an exception for unknown reasons. One speculation may be that Japan’s high level of innovation is focused more on incremental innovation of systems than on disruptive start-up style of innovation based on high-risk and high failure entrepreneurship of individuals. Despite the relatively small number of cases in the dataset (28) the illustrative example considers Japan a rare exception. This means that the full analysis must be re-done to obtain an estimate of the main necessity effect without Japan, and that Japan is considered an exception, to be discussed separately in the report. Additionally, a robustness check should be conducted and reported, comparing the results with and without the exception.
In the following analysis, Japan is removed from the nca.example dataset, followed by re-doing the data analysis:
library(NCA)
data(nca.example)

nca.exampleN <- nca.example[-14,] #exclude Japan
set.seed(123) # for replicability of estimated  p-value
modelN <- nca_analysis(nca.exampleN, 1,3,
                       ceilings = 'cr_fdh',
                       test.rep = 10000)
## Setting up parallelization, this might take a few seconds... Do test for : cr_fdh - IndividualismDone test for: cr_fdh - Individualismnca_output(modelN, plots = FALSE, summaries = TRUE)##
## ---------------------------------------------------------------------------## NCA Parameters : Individualism - Innovation performance## ---------------------------------------------------------------------------
##
## Number of observations 27
## Scope 15563.6
## Xmin 18.0
## Xmax 91.0
## Ymin 1.2
## Ymax 214.4
##
## cr_fdh
## Ceiling zone 6872.010
## Effect size 0.442
## # above 3
## Slope 2.580
## Intercept -20.338
## p-value 0.025
## p-accuracy 0.003
##
## Complexity 1
## Fit 80.1%
## Ceiling accuracy 88.9% (24)
## Noise 11.1% (3)
## Exceptions 0 % (0)
## Support 14.8% (4)
## Spread 0.42
## Sharpness 0.50
##
## Abs. ineff. 1819.580
## Rel. ineff. 11.691
## Condition ineff. 0.014
## Outcome ineff. 11.679The results show that the effect size \(d\) = 0.44 and the \(p\)-value = 0.025. Both values meet the selected threshold levels of \(d\) = 0.10 and \(\alpha\) = 0.05 such that the necessity hypothesis is not rejected (see, however, Section 9.9 about model fit and Section 9.12 about robustness checks).
To compare the results with and without the exceptions, it is possible to extract the \(XY\)-plot of this analysis that is done without the exception, and then to add the exception back to show its original position, and to include the original ceiling line as well using the following script.
library(NCA)
library(ggplot2)
data(nca.example)
# Coordinates of the exception
x <- nca.example["Japan", "Individualism"]
y <- nca.example["Japan", "Innovation performance"]

# Intercept and slope of original ceiling line
model <- nca_analysis(nca.example, 1, 3, ceilings = "cr_fdh")
model
a <- nca_extract(model, x = "Individualism",
                 ceiling = "cr_fdh",
                 param = "Intercept")
b <- nca_extract(model, x = "Individualism",
                 ceiling = "cr_fdh",
                 param = "Slope")

#2 NCA without exception
modelN <- nca_analysis(
  nca.example[row.names(nca.example) != "Japan", ], 1, 3,
  ceilings = "cr_fdh", custom = c(a,b) )
modelN

# XY plot for comparison
out <- nca_output(modelN, plots = TRUE, summaries = FALSE)
p <- out$plots[["Individualism"]] +
  geom_point(aes(x = x, y = y), shape = 1, colour = "blue") +
  geom_point(aes(x = x, y = y), shape = 4, colour = "red",
             size = 2, stroke = 1.2)
print(p)
Figure 9.5: \(XY\)-plot of illustrative example with one exception (crossed out). Light line: ceiling line after removal of the exception. Dark line: ceiling line before removal of the exception.
Figure 9.5 shows the \(XY\)-plot with the outlier case, the original ceiling line and the new ceiling line. The above procedures are for one outlier at a time. The judgment becomes more complex when the analyst considers removing more than one outlier one by one or at the same time. For example, after removing the first outlier, a case that was originally not part of the first set of single potential outliers, may be identified as a new potential outlier, etc. Generally, removing outliers is not advised unless the analyst has very good reasons for it.
9.9 Model fit
In Chapter 4, specific model fit metrics for NCA were introduced to evaluate how well the chosen necessity model (bounding box and ceiling line) represents the necessity relationship suggested by the data. Since NCA’s model is mathematical and not statistical (no error term), common statistical model fit metrics such as R\(^2\) or likelihood-based fit metrics are not applicable. To illustrate the use of NCA’s model fit metrics, they are applied to the illustrative example. In the NCA software for R, the values of the model fit metrics can be obtained using summaries = TRUE in the nca_output function as follows:
library(NCA)
data(nca.example)

nca.exampleN <- nca.example[-14,] #exclude Japan
set.seed(123) # for replicability of estimated  p-value
modelN <- nca_analysis(nca.exampleN, 1,3,
                       ceilings = 'cr_fdh',
                       test.rep = 10000)
## Setting up parallelization, this might take a few seconds... Do test for : cr_fdh - IndividualismDone test for: cr_fdh - Individualismnca_output(modelN, plots = FALSE, summaries = TRUE)##
## ---------------------------------------------------------------------------## ---------------------------------------------------------------------------
##
## Number of observations 27
## Scope 15563.6
## Xmin 18.0
## Xmax 91.0
## Ymin 1.2
## Ymax 214.4
##
## cr_fdh
## Ceiling zone 6872.010
## Effect size 0.442
## # above 3
## Slope 2.580
## Intercept -20.338
## p-value 0.025
## p-accuracy 0.003
##
## Complexity 1
## Fit 80.1%
## Ceiling accuracy 88.9% (24)
## Noise 11.1% (3)
## Exceptions 0 % (0)
## Support 14.8% (4)
## Spread 0.42
## Sharpness 0.50
##
## Abs. ineff. 1819.580
## Rel. ineff. 11.691
## Condition ineff. 0.014
## Outcome ineff. 11.6799.9.1 Complexity
Complexity refers to the ceiling degrees of freedom. Linear ceiling lines (C-LP, CR-FDH, CR-VRS) have fixed, low complexity (\(cp = 1\)), whereas segmented lines, such as CE-FDH (stepwise linear) and CE-VRS (concave linear) have higher complexity which depends on the number of peers that define the ceiling. Complexity is a model fit metric that needs to be balanced between a low score for good generalizability but possibly poor boundary fit, and a high score for good boundary fit but poor generalizability and greater susceptibility to small measurement errors (i.e., risk of overfitting).
For the illustrative example, the complexity is 1 because the selected ceiling line is a linear ceiling line (CR-FDH).
9.9.2 Fit
As discussed in Section 4.5.2, fit is the closeness of a chosen ceiling line’s effect size to the CE-FDH benchmark (100%), expressed as a percentage. This metric indicates how well a ceiling line follows the data border. Low values (e.g., < 80%) suggest poor fit with the irregularity of the boundary.
For the illustrative example, the fit is 80.1%.
9.9.3 Ceiling accuracy
Ceiling accuracy refers to the number of points on or below the ceiling line (Section 4.5.3). High ceiling accuracy means the ceiling line correctly separates the ceiling zone from the feasible area. If there are no points above the ceiling, the ceiling accuracy is 100%. A ceiling accuracy below for example 95% suggests that too many cases exist above the ceiling, and that the ceiling line may be too low.
In the illustrative example, the ceiling accuracy is 88.9%.
9.9.4 Noise
As discussed in Section 4.5.4, noise refers to points just above the ceiling that violate strict necessity. The medium-purity zone is the area of tolerable noise if the percentage of points is low, for example < 5%.
Figure 9.6 shows the NCA ribbon in the \(XY\)-plot of the illustrative example. The upper part of the ribbon represents iso-purity = 0.9. It shows that three points are in the medium-purity zone. With N = 27 this implies that noise is 11.1%.
Figure 9.6: The NCA ribbon in the \(XY\)-plot of the illustrative example (without outlier) with the preliminary CR-FDH ceiling line. Upper dotted line: iso-purity = 0.9. Lower dotted line: iso-solidity = 0.8.
9.9.5 Exceptions
Section 4.5.4 discusses the role of exceptions in NCA. An exception is a rare case that seriously violates necessity. Exceptions are located in the low-purity zone that is far from the ceiling. No points are allowed in the low-purity zone for deterministic necessity. If a rare point is in the low-purity zone it could be an exception that behaves differently than the entire group and needs to be discussed separately. Figure 9.6 shows that in the illustrative example there are no points in the low-purity zone, suggesting that there are no exceptions. The case (Japan) that was classified as exception in the outlier analysis is removed from the dataset. This choice is evaluated in the robustness check below (Section 9.12).
9.9.6 Support
Support quantifies how strongly the data in the feasible area support the ceiling line (Section 4.5.5). The points on the ceiling line and in the medium-solidity zone serve this purpose. For good support, at least for example 5% of cases in the feasible area should be located on or near the ceiling line in the medium-solidity zone.
In the illustrative example, one point is on the ceiling line and three points are below it in the medium-solidity zone. This implies that 4 cases (14.8%) are on the ceiling line or in the medium-solidity zone (support = 14.8%).
9.9.7 Spread
As discussed in Section 4.5.5, spread quantifies the extent to which observations in the feasible area near the ceiling are dispersed, rather than clustered along the ceiling line. Spread is 1 if all points are spaced uniformly, and is close to 0 if the points are clustered. A spread value of for example > 0.5 may be adequate.
In the illustrative example, the spread is 0.42.
9.9.9 Evaluation of model fit
In summary, the model fit parameters with the CR-FDH ceiling line are:
\[ \begin{aligned} \textit{Complexity} & = 1 \\ \textit{Fit} & = 80.1\% \\ \textit{Ceiling accuracy} & = 88.9\% \\ \textit{Noise} & = 11.1\% \\ \textit{Exceptions} & = 0 \\ \textit{Support} & = 14.8\% \\ \textit{Spread} & = 0.42 \\ \textit{Sharpness} & = 0.50 \end{aligned} \]
In all, the model fit of the illustrative example suggests that, although necessity is not rejected based on the effect size and the \(p\)-value (and the availability of theoretical support), its support from the perspective of model fit is not strong. Although after removing Japan, no further outliers exist in the low-purity zone of the ceiling zone, relatively many points are just above the ceiling in the medium-purity zone, as indicated by the metrics ceiling accuracy (too low) and noise (too high). Also, the ceiling line does not provide a clear separation between feasible area and ceiling zone, as indicated by the sharpness metric (too low). This suggests that an alternative linear ceiling line that is placed somewhat higher would give a better model fit. The C-LP ceiling line could be a candidate (Section 4.4). Therefore, the provisional model specification using the default CR-FDH ceiling line may be replaced by a model with a C-LP ceiling line to improve model fit:
library(NCA)
data(nca.example)
nca.exampleN <- nca.example[-14,]

set.seed(123)
modelFINAL <- nca_analysis(nca.exampleN, 1,3,
                           ceilings = 'c_lp',
                           test.rep =10000)
## Setting up parallelization, this might take a few seconds... Do test for : c_lp - IndividualismDone test for: c_lp - Individualismnca_output(modelFINAL, summaries = TRUE)##
## ---------------------------------------------------------------------------## ---------------------------------------------------------------------------
##
## Number of observations 27
## Scope 15563.6
## Xmin 18.0
## Xmax 91.0
## Ymin 1.2
## Ymax 214.4
##
## c_lp
## Ceiling zone 5094.910
## Effect size 0.327
## # above 0
## Slope 2.907
## Intercept -10.020
## p-value 0.034
## p-accuracy 0.004
##
## Complexity 1
## Fit 59.4%
## Ceiling accuracy 100 %
## Noise 0 % (0)
## Exceptions 0 % (0)
## Support 18.5% (5)
## Spread 0.41
## Sharpness 1.00
##
## Abs. ineff. 5373.780
## Rel. ineff. 34.528
## Condition ineff. 18.892
## Outcome ineff. 19.278Figure 9.7 shows the \(XY\)-plot with the C-LP ceiling line.
Figure 9.7: \(XY\)-plot of final results of illustrative example without exception and with the C-LP ceiling line.
The results show that the effect size \(d\) = 0.33 is greater than the selected threshold level of \(d\) = 0.10 and is statistically significant given the estimated \(p\)-value of 0.034 and selected threshold level of \(p\) = 0.05. Therefore, the initial conclusion that the hypothesis is supported remains.
Figure 9.8 shows the C-LP ceiling line with the NCA ribbon.
Figure 9.8: The NCA ribbon in the \(XY\)-plot of the illustrative example (without outlier) with the final C-LP ceiling line. Upper dotted line: iso-purity = 0.9. Lower dotted line: iso-solidity = 0.8.
The new model fit parameters for the C-LP ceiling line are (old values between parentheses):
\[ \begin{aligned} \textit{Complexity} & = 1 (1) \\ \textit{Fit} & = 59.4\% (80.1\%) \\ \textit{Ceiling accuracy} & = 100\% (88.9\%) \\ \textit{Noise} & = 0\% (11.1\%) \\ \textit{Exceptions} & = 0 (0) \\ \textit{Support} & = 18.5\% (14.8\%) \\ \textit{Spread} & = 0.41 (0.42) \\ \textit{Sharpness} & = 1.00 (0.50) \end{aligned} \]
All but one model fit metrics are the same or have improved. The fit metric has decreased to 59.4%. This indicates that the C-LP line poorly fits the irregular form of the border between the feasible area and the empty space.
The example shows that assessing and achieving model fit is an act of balancing between several indicators of fit, and that it is unlikely that all indicators will reach an optimal level. The analyst must make certain choices that should be justified and reported for transparency.
In the illustrative example the analysis with the C-LP model is selected to evaluate the hypothesis.
9.10 Conclusion about necessity-in-kind
After the analysis, a binary conclusion can be made about the hypothesis. The hypothesis is supported (not rejected) if the observed effect size is equal to or above the effect size threshold, and the \(p\)-value is below the \(p\)-value threshold, and there is theoretical support (the formal hypothesis). The hypothesis is rejected if the observed effect size is below the effect size threshold, or the \(p\)-value is equal to or above the \(p\)-value threshold, or there is no theoretical support (no formal hypothesis).
Given these choices made for the illustrative example, the hypothesis is supported because there is:
- theoretical support (Section 9.2);
- practical significance: the effect size \(d\) = 0.33 is at least \(d\) = 0.10;
- statistical significance: the \(p\)-value \(p\) = 0.034 is less than \(p\) = 0.05.
9.11 Bottleneck analysis: necessity-in-degree
For additional insights, a supported necessary condition in kind can also be formulated quantitatively as a necessary condition in degree: level \(x\) of \(X\) is necessary for level \(y\) of \(Y\).
In the illustrative example a target outcome corresponding to 90th percentile was selected: a performance level that is so high that it can only be achieved by 10 percent of the cases.
The target condition that is required for the target outcome can be directly observed from the \(XY\)-plot in which the ceiling line and the target outcome are drawn. Figure 9.9 shows the target outcome level for the illustrative example as a horizontal line \(y\) = 159.0, which corresponds to the selected 90th percentile level. This line intersects with the ceiling line at point \(x\) = 58.17.94
Figure 9.9: The final \(XY\)-plot of the illustrative example showing the target outcome for the 90th percentile and the corresponding required target level of the condition.
The bottleneck table is a helpful tool for evaluating necessary conditions in degree for any target level of the outcome. The bottleneck table is the tabular representation of the ceiling line, in which the first column represents the outcome and the next columns represent the necessary conditions. The values in the first column are the levels of \(Y\), and the values in the next columns are the levels of \(X\), corresponding to the ceiling line. By reading the bottleneck table row by row from left to right, the required threshold level(s) of the condition(s) \(X\) for a particular level of \(Y\) can be evaluated.
The bottleneck table can be produced with the NCA software using the argument bottlenecks = 'TRUE' in the nca_output function. For the illustrative example the bottleneck table can be produced as follows:
library(NCA)
data(nca.example)
nca.exampleN <- nca.example[-14,]

modelFINAL <- nca_analysis(nca.exampleN, 1,3, ceilings = 'c_lp')
nca_output (modelFINAL, summaries = FALSE, plots = FALSE,
            bottlenecks = TRUE)
##
## ---------------------------------------------------------------------------## Bottleneck C-LP (cutoff = 0)## Y Innovation performance (percentage.range)## 1 Individualism (percentage.range)## ---------------------------------------------------------------------------
## Y 1
## 0 NN
## 10 NN
## 20 0.7
## 30 10.8
## 40 20.8
## 50 30.9
## 60 40.9
## 70 51.0
## 80 61.0
## 90 71.1
## 100 81.1## In the default bottleneck table, the values of the outcome and the condition are expressed as ‘percentage range’ with 11 levels between 0% and 100%, corresponding to steps of 10%. The ‘percentage range’ format of the bottleneck table means that the values of \(X\) and \(Y\) are linearly transformed by min-max normalization (with 0% and 100% bounds) to obtain values between 0 and 100 percent. 0% corresponds to the minimum value, 100% to the maximum value, and 50% to the mid-value between these two extremes. This transformation facilitates the comparison of \(X\)- and \(Y\)-values within and between studies. However, as illustrated below, other formats to represent \(X\) and \(Y\) may be more informative for a specific study.
The bottleneck table of the illustrative example shows that up to target outcome of 20%, \(X\) is not necessary for \(Y\) (‘NN’). For higher levels of the target outcome, \(X\) is necessary. For a target outcome of 50%, at least \(x\) = 30.9% is needed, and for 90%, at least \(x\) = 71.1% is needed.
To obtain a more detailed picture, the size of the steps can be adjusted, for example to 5 using the step.size argument in the nca_analysis function:
library(NCA)
data(nca.example)
nca.exampleN <- nca.example[-14,]

modelFINAL <- nca_analysis(nca.exampleN, 1,3, ceilings = 'c_lp',
                           step.size = 5)
nca_output (modelFINAL, summaries = FALSE, plots = FALSE,
            bottlenecks = TRUE)
##
## ---------------------------------------------------------------------------## Bottleneck C-LP (cutoff = 0)## Y Innovation performance (percentage.range)## 1 Individualism (percentage.range)## ---------------------------------------------------------------------------
## Y 1
## 0 NN
## 5 NN
## 10 NN
## 15 NN
## 20 0.7
## 25 5.7
## 30 10.8
## 35 15.8
## 40 20.8
## 45 25.8
## 50 30.9
## 55 35.9
## 60 40.9
## 65 45.9
## 70 51.0
## 75 56.0
## 80 61.0
## 85 66.0
## 90 71.1
## 95 76.1
## 100 81.1## 9.11.1 Levels expressed as actual values
The levels of \(X\) and \(Y\) in the bottleneck table can also be expressed as actual values. Actual values are the values of \(X\) and \(Y\) as they are in the original dataset (and in the \(XY\)-plot). This way of expressing the levels can help to compare the bottleneck table results with the original data and with the \(XY\)-plot results. Expressing the levels of \(X\) with actual values can be done with the argument bottleneck.x = 'actual' in the nca_analysis function, and the actual values of \(Y\) can be shown in the bottleneck table with the argument bottleneck.y = 'actual' as follows:
library(NCA)
data(nca.example)
nca.exampleN <- nca.example[-14,]

modelFINAL <- nca_analysis(nca.exampleN, 1,3, ceilings = 'c_lp',
                           bottleneck.y = "actual",
                           bottleneck.x = "actual")
nca_output (modelFINAL, plots = FALSE, summaries = FALSE,
            bottlenecks = TRUE)
##
## ---------------------------------------------------------------------------## Bottleneck C-LP (cutoff = 0)## Y Innovation performance (actual)## 1 Individualism (actual)## ---------------------------------------------------------------------------
## Y 1
## 1.20 NN
## 22.52 NN
## 43.84 18.530
## 65.16 25.865
## 86.48 33.200
## 107.80 40.534
## 129.12 47.869
## 150.44 55.204
## 171.76 62.539
## 193.08 69.874
## 214.40 77.209## While the default number of steps remains the same, the scores in which \(X\) and \(Y\) are expressed has been changed to actual values.
For practical purposes, specific values for \(Y\) can be selected, for example, values that correspond to the scale for scoring \(Y\), or specific target values of interest. The steps argument in the nca_analysis function can be used for this purpose. For the illustrative example, the step values may correspond to for example the minimum and maximum \(Y\)-values and multiples of 10, as follows:
library(NCA)
data(nca.example)
nca.exampleN <- nca.example[-14,]

min_y <- min(nca.exampleN$`Innovation performance`)
max_y <- max(nca.exampleN$`Innovation performance`)
modelFINAL <- nca_analysis(nca.exampleN, 1,3, ceilings = 'c_lp',
                           bottleneck.y = "actual",
                           bottleneck.x = "actual",
                           steps = c(min_y, seq(10, 210, by = 10),max_y))
nca_output (modelFINAL, plots = FALSE, summaries = FALSE,
            bottlenecks = TRUE)
##
## ---------------------------------------------------------------------------## Bottleneck C-LP (cutoff = 0)## Y Innovation performance (actual)## 1 Individualism (actual)## ---------------------------------------------------------------------------
## Y 1
## 1.2 NN
## 10.0 NN
## 20.0 NN
## 30.0 NN
## 40.0 NN
## 50.0 20.649
## 60.0 24.089
## 70.0 27.530
## 80.0 30.970
## 90.0 34.411
## 100.0 37.851
## 110.0 41.291
## 120.0 44.732
## 130.0 48.172
## 140.0 51.612
## 150.0 55.053
## 160.0 58.493
## 170.0 61.933
## 180.0 65.374
## 190.0 68.814
## 200.0 72.255
## 210.0 75.695
## 214.4 77.209## 9.11.2 Levels expressed as percentiles
The levels of \(X\) and \(Y\) can also be expressed as percentiles. The percentile is a score where a certain percentage of scores fall below that score. For example, the 90th percentile of \(X\) is a score of \(X\) that is so high that 90% of the observed \(X\)-scores fall below that \(X\)-score, and thus only 10% above it. Similarly, the 5th percentile of \(X\) is a score of \(X\) that is so low that 5% of the observed \(X\)-scores fall below that \(X\)-score, and 95% above it.
The \(X\)- and \(Y\)-values in the bottleneck table can be expressed by percentiles by using the argument bottleneck.x = 'percentile' and/or bottleneck.y = 'percentile' in the nca_analysis function.
For a given target level of \(Y\) that is expressed in percentiles (e.g., the 90th percentile target outcome as pre-defined in the illustrative example), the actual bottleneck value of \(X\) can be obtained as follows, which corresponds to the above approach to find the target condition:95
library(NCA)
data(nca.example)
nca.exampleN <- nca.example[-14,]

modelFINAL <- nca_analysis(nca.exampleN, 1,3, ceilings = 'c_lp',
                           bottleneck.y = "percentile",
                           bottleneck.x = "actual",
                           steps = c(0, 90))
nca_output (modelFINAL, plots = FALSE, summaries = FALSE,
            bottlenecks = TRUE)
##
## ---------------------------------------------------------------------------## Bottleneck C-LP (cutoff = 0)## Y Innovation performance (percentile)## 1 Individualism (actual)## ---------------------------------------------------------------------------
## Y 1
## 0 NN
## 90 58.170## A useful approach is to express \(Y\)-values as actual values and \(X\)-values as percentiles, as follows:
library(NCA)
data(nca.example)
nca.exampleN <- nca.example[-14,]

min_y <- min(nca.exampleN$`Innovation performance`)
max_y <- max(nca.exampleN$`Innovation performance`)
modelFINAL <- nca_analysis(nca.exampleN, 1,3, ceilings = 'c_lp',
                           bottleneck.y = "actual",
                           bottleneck.x = "percentile")
nca_output (modelFINAL, plots = FALSE, summaries = FALSE,
            bottlenecks = TRUE)
##
## ---------------------------------------------------------------------------## Bottleneck C-LP (cutoff = 0)## Y Innovation performance (actual)## 1 Individualism (percentile)## ---------------------------------------------------------------------------
## Y 1
## 1.20 NN (0)
## 22.52 NN (0)
## 43.84 3.7 (1)
## 65.16 3.7 (1)
## 86.48 11.1 (3)
## 107.80 18.5 (5)
## 129.12 18.5 (5)
## 150.44 29.6 (8)
## 171.76 37.0 (10)
## 193.08 51.9 (14)
## 214.40 74.1 (20)## In this format, the bottleneck table can be interpreted as follows. The percentile level of \(X\) corresponds to the percentage of cases that are unable to reach the threshold level of \(X\) that is required for the target level of \(Y\) (in the same row). The number between brackets corresponds to the number of cases that were not able to achieve the target outcome. For example, in the row with target level \(Y\) = 150.44, the percentile score of \(X\) is 29.6. This means that 29.6% of the cases (= 8 cases) were not able to achieve the required level of \(X\) for the target level of \(Y\).
Thus, percentile scores of \(X\) provide an indication of the importance of the bottleneck by revealing how many cases in the sample were unable to reach the required level of the necessary condition for a particular level of the outcome.
9.11.2.1 Levels expressed as percentage of maximum
The final way of expressing the levels of \(X\) and \(Y\) is less commonly used: the percentage of their maximum levels. It indicates how far the score is from the maximum score. The bottleneck table can be expressed with percentage of maximum by using the arguments bottleneck.x = 'percentage.max' or bottleneck.y = 'percentage.max' in the nca_analysis function.
9.11.3 Multiple necessary conditions
The bottleneck table can include multiple necessary conditions for which necessity-in-kind has been established (Section 4.6). Conditions that are not necessary (e.g., because theoretical support is missing, the effect size is too small, or the \(p\)-value is too large), should not be included in the table. For the illustrative example, the bottleneck table can be extended with the condition Risk taking. Theoretical arguments suggest that Risk taking is necessary for Innovation performance, and the criteria for effect size and \(p\)-value are also satisfied according to the analysis below. For consistency, the same form of the ceiling line (C-LP), type of scope (empirical), and evaluation criteria (\(d \geq\) 0.10 and \(p\) < 0.05) are used. Again, the outlier that was detected earlier is excluded from the analysis:
library(NCA)
data(nca.example)
nca.exampleN <- nca.example[-14,]

set.seed(123)
modelFINAL <- nca_analysis(nca.exampleN,
                           c(1,2),3,
                           ceilings = 'c_lp', test.rep = 10000,
                           bottleneck.y = "actual",
                           bottleneck.x = "percentile",
                           steps = c(min_y, seq(10, 210, by = 10),max_y))
## Setting up parallelization, this might take a few seconds... Do test for : c_lp - IndividualismDone test for: c_lp - Individualism
## Do test for : c_lp - Risk takingDone test for: c_lp - Risk takingprint(modelFINAL)##
## ---------------------------------------------------------------------------## Effect size(s):## c_lp p
## Individualism 0.33 0.034
## Risk taking 0.33 0.002
## ---------------------------------------------------------------------------nca_output (modelFINAL, summaries = FALSE,
bottlenecks = TRUE)##
## ---------------------------------------------------------------------------## Bottleneck C-LP (cutoff = 0)## Y Innovation performance (actual)## 1 Individualism (percentile)## 2 Risk taking (percentile)## ---------------------------------------------------------------------------
## Y 1 2
## 1.2 NN (0) NN (0)
## 10.0 NN (0) NN (0)
## 20.0 NN (0) NN (0)
## 30.0 NN (0) 3.7 (1)
## 40.0 NN (0) 3.7 (1)
## 50.0 3.7 (1) 7.4 (2)
## 60.0 3.7 (1) 7.4 (2)
## 70.0 7.4 (2) 7.4 (2)
## 80.0 11.1 (3) 14.8 (4)
## 90.0 11.1 (3) 14.8 (4)
## 100.0 18.5 (5) 22.2 (6)
## 110.0 18.5 (5) 37.0 (10)
## 120.0 18.5 (5) 37.0 (10)
## 130.0 18.5 (5) 37.0 (10)
## 140.0 22.2 (6) 44.4 (12)
## 150.0 29.6 (8) 48.1 (13)
## 160.0 33.3 (9) 51.9 (14)
## 170.0 37.0 (10) 51.9 (14)
## 180.0 40.7 (11) 59.3 (16)
## 190.0 48.1 (13) 59.3 (16)
## 200.0 63.0 (17) 70.4 (19)
## 210.0 70.4 (19) 81.5 (22)
## 214.4 74.1 (20) 81.5 (22)## 
Figure 9.10: \(XY\)-plots of final results of illustrative example including a second necessary condition.
The results show that the ceiling lines and the effect sizes are similar for the two conditions. Risk taking is necessary with an effect size of \(d\) = 0.33 and a \(p\)-value of \(p\) = 0.002. The bottleneck table for the two conditions shows that different values of Individualism and Risk taking are needed to make the outcome possible. For example, for \(Y\) = 30, Individualism is not necessary, but Risk taking is necessary. However, this is not a very important bottleneck because only 3.7% (1 case) cannot achieve the required level of \(X\) for this target level of \(Y\). To be able to achieve a target level of for example \(Y\) = 170, both Individualism and Risk taking are necessary. This target outcome cannot be achieved by 37.0% of cases (10 cases) for Individualism, and 51.9% of cases (14 cases) for Risk taking. If for a given case the required level of one of the two conditions is not achieved, the corresponding level of the outcome will not be reachable.
9.11.4 Interpretation of the bottleneck table for other corners
The above sections refer to analyzing the upper-left corner in the \(XY\)-plot, corresponding to the situation that the presence or a high value of \(X\) is necessary for the presence or a high value of \(Y\). As indicated above, in the situation that \(X\) is expressed as ‘percentage range’, ‘actual value’ or ‘percentage maximum’ the bottleneck table shows the minimum required level of \(X\) for a given value of \(Y\). When \(X\) is expressed as ‘percentiles’, the bottleneck table shows the percentage of cases that are unable to reach the required level of \(X\) for a given value of \(Y\).
However, the interpretation of the bottleneck table is different when other corners than the upper-left corner are analyzed (Figure 3.8).
9.11.4.1 Bottleneck table for corner = 2
For corner = 2, the upper-right corner is empty suggesting that the absence or low value of \(X\) is necessary for the presence or high value of \(Y\). This means that for a given value of \(Y\), the value of \(X\) must be equal to or lower than the threshold value according to the ceiling line. When \(X\) is expressed as ‘percentage range’, ‘actual value’ or ‘percentage maximum’, the bottleneck table shows the maximum required level of \(X\) for a given value of \(Y\). In other words, for each row in the bottleneck table (representing the target level of \(Y\)), the corresponding level of \(X\) must be at most the level mentioned in the bottleneck table. When \(X\) is expressed as ‘percentiles’, the bottleneck table still shows the percentage and number of cases that are unable to reach the required level of \(X\) for a given value of \(Y\).
9.11.4.2 Bottleneck table for corner = 3
For corner = 3, the lower-left corner is empty suggesting that the presence or high value of \(X\) is necessary for the absence or low value of \(Y\). This means that for a given value of \(Y\), the value of \(X\) must be equal to or higher than the threshold value according to the ‘ceiling line’, which is now a floor line. When \(X\) is expressed as ‘percentage range’, ‘actual value’ or ‘percentage maximum’ the bottleneck table shows the minimum required level of \(X\) for a given value of \(Y\). In other words, for each row in the bottleneck table (representing the desired level of \(Y\)), the corresponding level of \(X\) must be at least the level mentioned in the bottleneck table. However, the first column in the bottleneck table (representing \(Y\)) is now reversed. The first row has a high \(Y\)-value and the last row has the low value. When percentage-based scores of Y are used (i.e., percentiles, percentages of the range, and percentages of the maximum), a low percentage now corresponds to a high level of \(Y\) and a high percentage to a low level. When \(X\) is expressed as ‘percentiles’, the bottleneck table still shows the percentage and number of cases that are unable to reach the required level of \(X\) for a given value of \(Y\).
9.11.4.3 Bottleneck table with corner = 4
For corner = 4, the lower-right corner is empty suggesting that the absence or low value of \(X\) is necessary for the absence or low value of \(Y\). This means that for a given value of \(Y\), the value of \(X\) must be equal to or lower than the threshold value according to the ‘ceiling line’, which is now a floor line. When \(X\) is expressed as ‘percentage range’, ‘actual value’ or ‘percentage maximum’ the bottleneck table shows the maximum required level of \(X\) for a given value of \(Y\). For each row in the bottleneck table (representing the desired level of \(Y\)), the corresponding level of \(X\) must be at most the level mentioned in the bottleneck table. The first column in the bottleneck table (representing \(Y\)) is again reversed. The first row has a high \(Y\)-value and the last row has the low values as the desired outcome is low. Again, when percentages are used for \(Y\) (percentile or percentage of maximum) a low percentage corresponds to a high level of \(Y\) and a high percentage to a low level of \(Y\), and when \(X\) is expressed as ‘percentiles’, the bottleneck table still shows the percentage and number of cases that are unable to reach the required level of \(X\) for a given value of \(Y\).
9.11.5 NN and NA in the bottleneck table
‘NN’ (Not Necessary) in the bottleneck table means that \(X\) is not necessary for \(Y\) for the particular level of \(Y\). With any value of \(X\) it is possible to achieve the particular level of \(Y\).
‘NA’ (Not Applicable) in the bottleneck table is meant to warn that it is impossible to compute a value for \(X\). There are two possible reasons: the first of which occurs more often than the second:
The maximum possible value of the condition for the particular level of \(Y\) according to the ceiling line is lower than the actually observed maximum value. This can happen for example when a CR ceiling (which is a trend line) intersects the right bound (\(X\) = \(x_{max}\)) of the bounding box. If this happens, the analyst can either explain why NA appears in the bottleneck table, or can change NA into the highest observed level of \(X\). The latter can be done with the argument
cutoff = 1in thenca_analysisfunction.In a bottleneck table with multiple conditions, one case determines the \(y_{max}\)-value and that case has a missing value for the condition with the NA (but not for another condition). When all cases are complete (have no missing values) or when at least one case with a complete observation (\(x\),\(y_{max}\)) for the given condition exists, NA will not appear. The analyst can choose to explain why NA appears, or to exclude the incomplete case from the bottleneck table analysis (and accept that the \(y_{max}\) in the bottleneck table does not correspond to the actually observed \(y_{max}\)).
9.12 Robustness checks
When conducting an empirical study, the analyst must make a variety of theoretical and methodological choices to obtain results. For example, as shown above the choice of the form of the ceiling line was not obvious. Often, plausible alternative choices can be made for several aspects of the analysis. To evaluate the sensitivity of the results to the analyst’s choices, robustness checks can be conducted. Typically, the checks focus on the sensitivity of the main estimates and the study’s main conclusion (e.g., rejection or non-rejection of the hypothesis based on effect size and \(p\)-value).96
In NCA, the effect size and the \(p\)-value are two main estimates for concluding whether a necessity relationship is credible. These estimates can be sensitive to several choices. Some choices may not be specific for NCA, for example choices related to the data that are used as input to NCA (study design, sampling, measurement, Section 8.2) or the statistical significance level (\(\alpha\), Section 9.4.2). Other choices are NCA-specific, such as the choice of the ceiling line (e.g., CE-FDH or CR-FDH in the model specification, Section 9.3), the choice of the scope (empirical or theoretical, Section 9.3.1), the threshold level of the necessity effect size (e.g., 0.10 or different, Section 9.4.1), the target outcome (Section 9.4.3) and the handling of NCA-relevant outliers (inclusion/ exclusion, Section 9.8).
This section discusses several choices that are candidates for a robustness check in NCA. These choices refer to model specification (ceiling line and scope, Section 9.3), the selection of evaluation criteria for the hypothesis (threshold levels for \(d\), and \(p\)-value, level of the target outcome, Section 9.4), and the handling of outliers (Section 9.8). The analyst selects only relevant robustness checks. It makes no sense to do a robustness check for outliers if the visual inspections of the \(XY\)-plots clearly indicate that there are no outliers, or that a certain ceiling line is clearly the preferred choice for theoretical or empirical reasons.
For the illustrative example, the effect of the analyst’s choices on the conclusion is evaluated. The choices made in the illustrative example for the final analysis were:
Ceiling line = C-LP
Scope = empirical
Effect size threshold = 0.10
\(p\)-value threshold = 0.05
Target outcome: 90th percentile
Outliers: one outlier removed (considered an exception; application of the typicality necessity).
9.12.1 Different ceiling line choice
In the illustrative example, the final choice was made to conduct the primary analysis with the C-LP ceiling line based on the evaluation of model fit (Section 9.9.9). One of the weaknesses of this selection is the low fit metric, that suggests that the line does not follow the irregular borderline well. The CE-FDH ceiling line is a reasonable alternative ceiling line that performs better regarding this aspect, although this line is more complex and may risk overfitting (Section 9.9.1). The analysis with this ceiling line is as follows:
library (NCA)
data(nca.example)
nca.exampleN <- nca.example[-14,]

#ceiling line change
set.seed(123)
modelN2 <- nca_analysis(nca.exampleN, 1,3, ceilings = 'ce_fdh', test.rep = 10000)
## Setting up parallelization, this might take a few seconds... Do test for : ce_fdh - IndividualismDone test for: ce_fdh - IndividualismmodelN2##
## ---------------------------------------------------------------------------## ce_fdh p
## Individualism 0.55 0.006
## ---------------------------------------------------------------------------nca_output(modelN2, summaries = FALSE)
Figure 9.11: Ceiling robustness check for the illustrative example: Results with CE-FDH ceiling line.
The results with the alternative ceiling line show that the effect size \(d\) = 0.55 is larger than the original effect size \(d\) = 0.33 and that the \(p\)-value is smaller (0.006 compared to 0.034). Both ceiling lines produce the same conclusion that necessity is supported, which suggests a robust result. However, given the low fit metric, the bottleneck table analysis would yield different results.
9.12.2 Different choice of the scope
In the illustrative example the choice was made to use the empirical scope. The reason was that this scope usually avoids overestimation of the effect size, and that the variables have no natural upper or lower bound (unlike, for example, Likert scales or percentage scales). However, it may be possible to assume lower and upper limits for the variables. For example, the minimum and maximum observed values for Individualism in all countries are 6 and 91, respectively (Hofstede, 1980), whereas the minimum and maximum values in the analyzed dataset of 28 countries are 18 and 91, respectively. Based on this, the theoretical bounds for Individualism could be set at [6, 91]. According to Gans and Stern (2003), Innovation performance ranged between 1.2 and 214.4 in the year 2000. They predicted that, by 2005, the maximum innovation performance would be 258. Assuming that Innovation performance cannot be negative, the minimum theoretical value could be set at 0. This means that the theoretical bounds for Innovation performance could be set at [0, 258], resulting in a relevant theoretical scope of [6,91] \(\times\) [0,258].
This can be analyzed with the following R-code:
library (NCA)
data(nca.example)
nca.exampleN <- nca.example[-14,]

set.seed(123)
modelN3 <- nca_analysis(nca.exampleN, 1,3,
                        ceilings = 'c_lp',
                        test.rep = 10000,
                        scope = c(6,91,0,258))
## Setting up parallelization, this might take a few seconds... Do test for : c_lp - IndividualismDone test for: c_lp - IndividualismmodelN3##
## ---------------------------------------------------------------------------## c_lp p
## Individualism 0.49 0.031
## ---------------------------------------------------------------------------nca_output(modelN3, summaries = FALSE)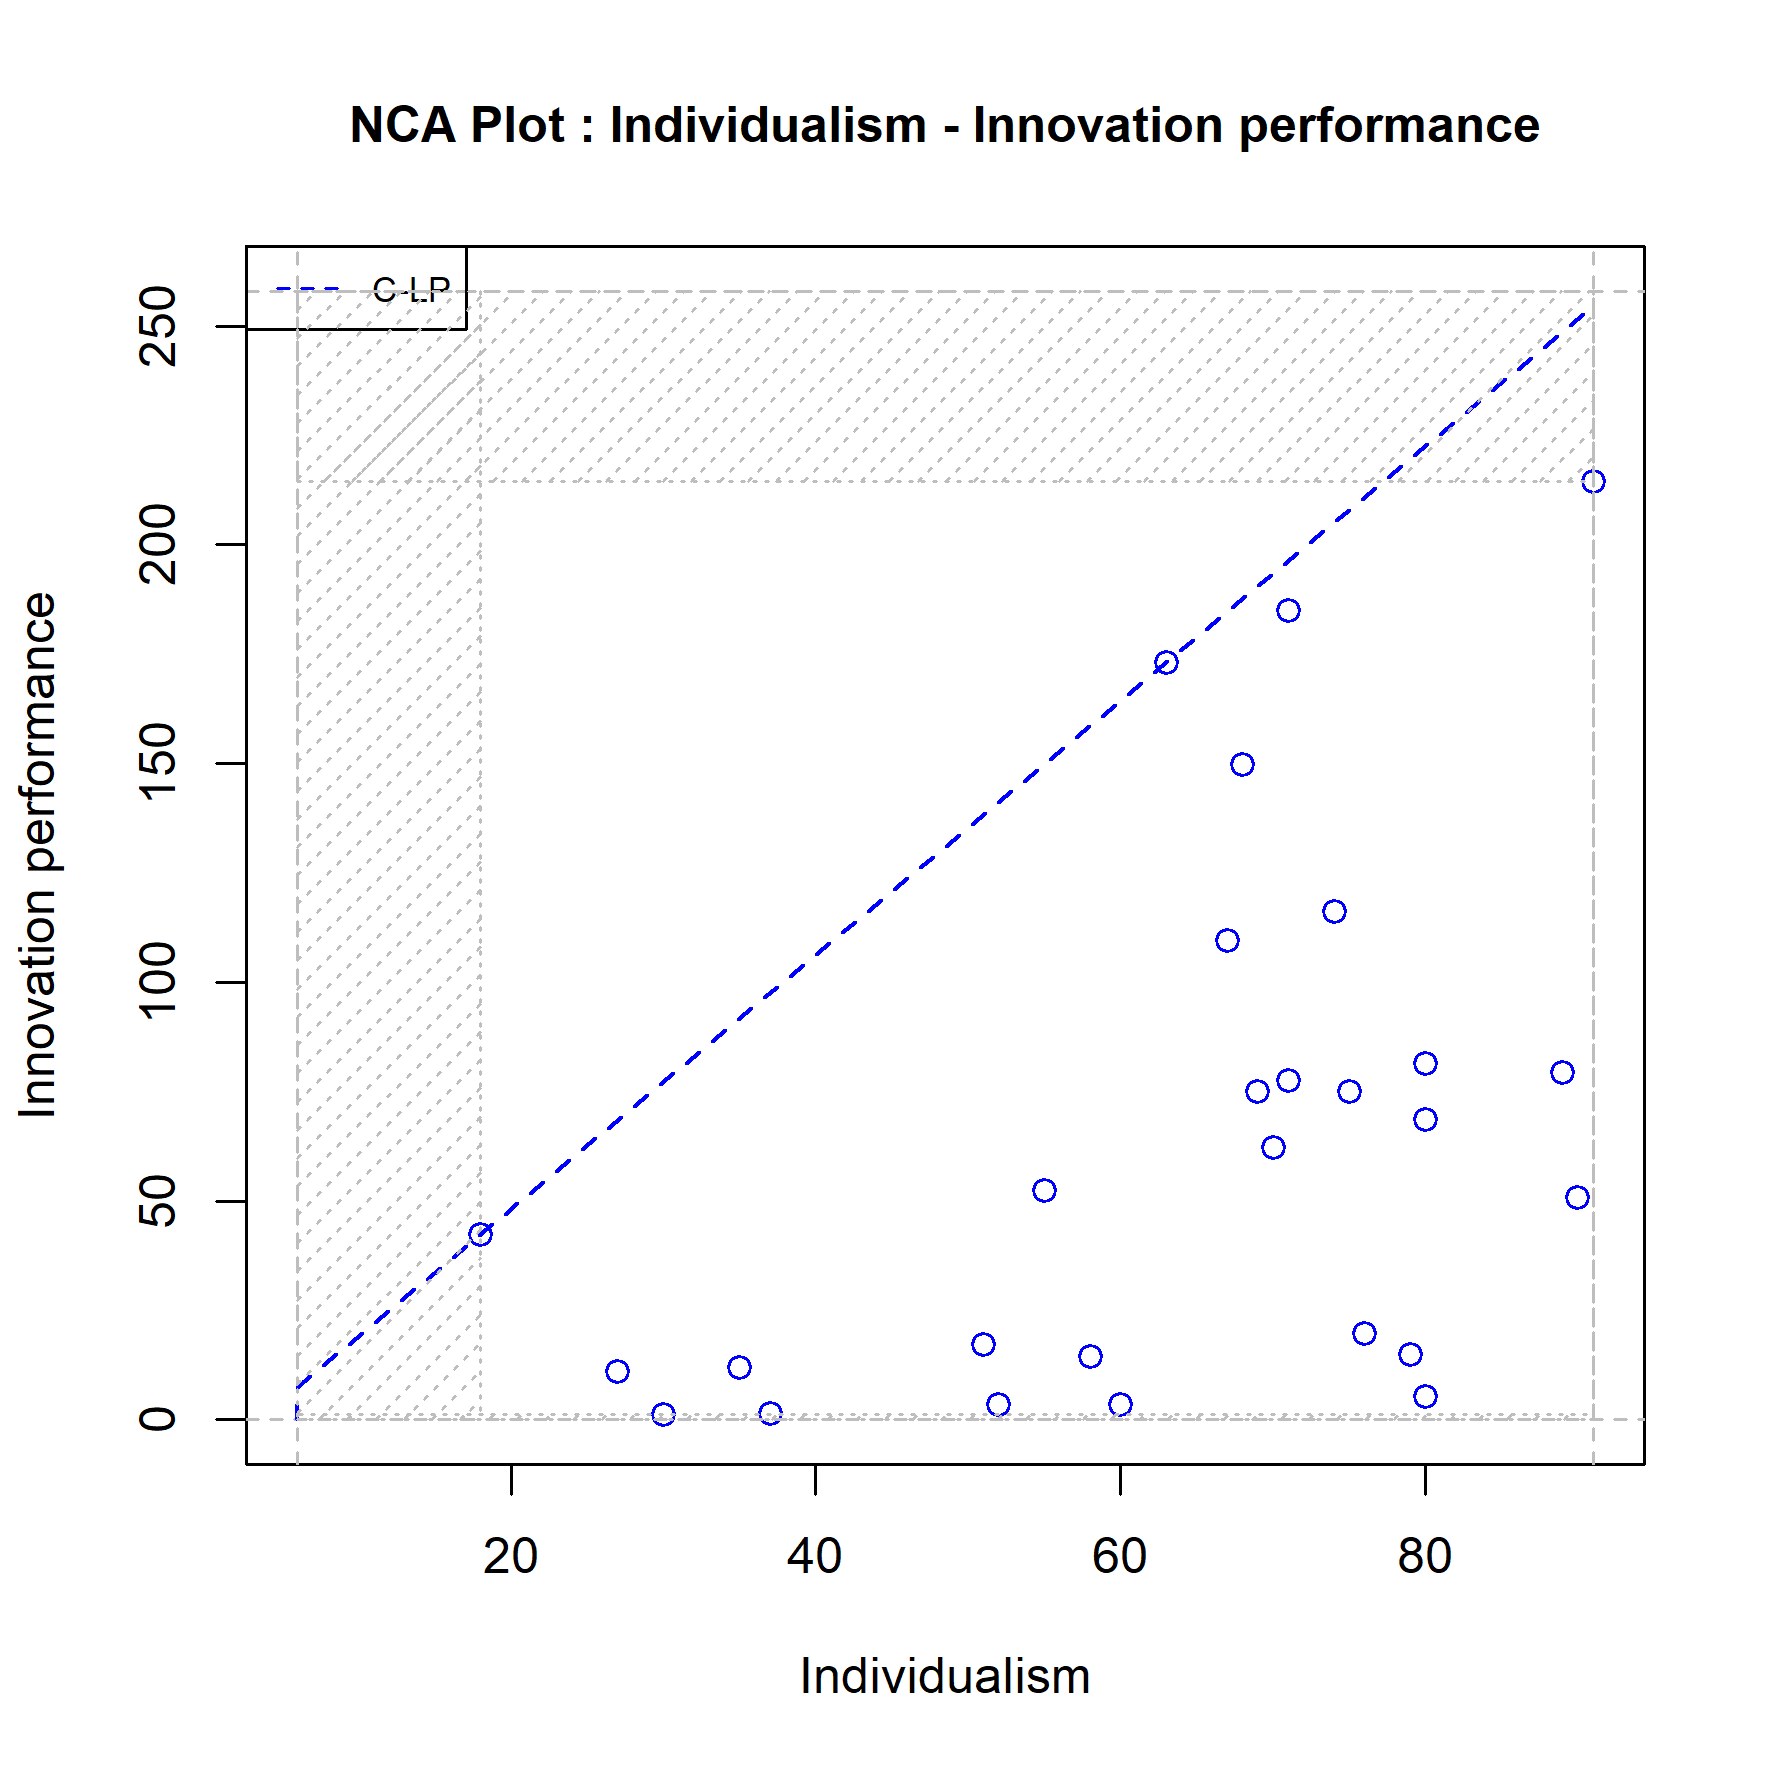
Figure 9.12: Scope robustness check for the illustrative example: Comparing the results with the empirical and with the theoretical scope (difference is shaded).
The check reveals that an analysis with the larger theoretical scope yields a larger effect size. In the current example, this does not change the main conclusion.
9.12.3 Different choice of the threshold level of the effect size
The analyst could also have made another choice for the effect size threshold level. If the threshold level is changed from the common 0.10 value (“small effect”) to a larger value of 0.20 (“medium effect”), the conclusion for the illustrative example about the hypothesis would not change, as the original effect size \(d\) = 0.33. The robustness check of effect size threshold suggests a robust result.
9.12.4 Different choice of the threshold level of the \(p\)-value
The analyst could also have made another choice for the \(p\)-value threshold level (\(\alpha\)). If the threshold level is changed from the common 0.05 value to a stricter level of \(p\) = 0.01, the conclusion in the above example about the hypothesis would change. This robustness check indicates that the statistical significance of the result is fragile.
9.12.5 Different outlier choice
The fourth robustness check is the outlier robustness check. NCA results can be sensitive to the handling of outliers as they, by definition, influence the effect size estimate (Section 9.8). An earlier decision to include potential outliers could be challenged by excluding one or more potential outliers with the largest influence on the effect size if removed. Similarly, an earlier decision to exclude one or more outliers with a relatively large influence on the effect size, could be challenged by including them, or by excluding additional outliers.
In the illustrative example, one single outlier was removed from the analysis. This decision is challenged in two ways: (1) the removed outlier (Japan) is included again in the analysis, (2) an additional outlier that makes a pair with Japan is also excluded (Finland).
The R-code for this robustness check is as follows:
library (NCA)
data(nca.example)
nca.exampleN <- nca.example[-14,]

#outlier change 1 (include the earlier removed outlier)
set.seed(123)
modelN4 <- nca_analysis(nca.example, 1,3, ceilings = 'c_lp', test.rep = 10000)
## Setting up parallelization, this might take a few seconds... Do test for : c_lp - IndividualismDone test for: c_lp - IndividualismmodelN4##
## ---------------------------------------------------------------------------## c_lp p
## Individualism 0.16 0.319
## ---------------------------------------------------------------------------nca_output(modelN4, summaries = FALSE)
modelN4b <- nca_analysis(nca.example, 1,3, ceilings = "c_lp",
bottleneck.y = 'percentile',
bottleneck.x = 'percentile',
steps = c(85,90,95))
nca_output(modelN4b, summaries = FALSE, bottlenecks = T)##
## ---------------------------------------------------------------------------## ---------------------------------------------------------------------------
## Y 1
## 85 3.6 (1)
## 90 21.4 (6)
## 95 32.1 (9)#outlier change 2 (remove an additional outlier)
nca_outliers(nca.example, 1,3,
ceiling = 'c_lp',
k = 2,
condensed = TRUE) #Japan and Finland## Setting up parallelization, this might take a few seconds... ## outliers eff.or eff.nw dif.abs dif.rel ceiling scope
## 1 Japan - Finland 0.16 0.35 0.19 117.2 X
## 2 Japan - South Korea 0.16 0.34 0.17 106.7 X X
## 3 Japan - Mexico 0.16 0.33 0.16 101.2 X X
## 4 Japan 0.16 0.33 0.16 101.0 X
## 5 USA - South Korea 0.16 0.04 -0.12 -72.7 X X
## 6 USA 0.16 0.06 -0.11 -65.3 X X
## 7 USA - Mexico 0.16 0.06 -0.11 -65.3 X X
## 8 USA - Australia 0.16 0.06 -0.11 -64.8 X X
## 9 Japan - USA 0.16 0.26 0.10 62.4 X X
## 10 South Korea - Portugal 0.16 0.14 -0.03 -16.4 X X
## 11 South Korea 0.16 0.14 -0.02 -12.3 X X
## 12 South Korea - Mexico 0.16 0.14 -0.02 -12.2 X X
## 13 USA - Sweden 0.16 0.15 -0.01 -8.1 X X
## 14 USA - Finland 0.16 0.17 0.00 2.2 X X
## 15 Mexico - Turkey 0.16 0.16 0.00 1.1 X X
## 16 Mexico 0.16 0.16 0.00 0.1 X Xnca.exampleN2 <- nca.example[-c(7,14),]
set.seed(123)
modelN5 <- nca_analysis(nca.exampleN2, 1,3,
ceilings = 'c_lp',
test.rep = 10000)## Setting up parallelization, this might take a few seconds... Do test for : c_lp - IndividualismDone test for: c_lp - IndividualismmodelN5##
## ---------------------------------------------------------------------------## c_lp p
## Individualism 0.35 0.026
## ---------------------------------------------------------------------------nca_output(modelN5, summaries = FALSE)
modelN5b <- nca_analysis(nca.exampleN2, 1,3, ceilings = "c_lp",
bottleneck.y = 'percentile',
bottleneck.x = 'percentile',
steps = c(85,90,95))
nca_output(modelN5b, summaries = FALSE, bottlenecks = T)##
## ---------------------------------------------------------------------------## ---------------------------------------------------------------------------
## Y 1
## 85 19.2 (5)
## 90 23.1 (6)
## 95 42.3 (11)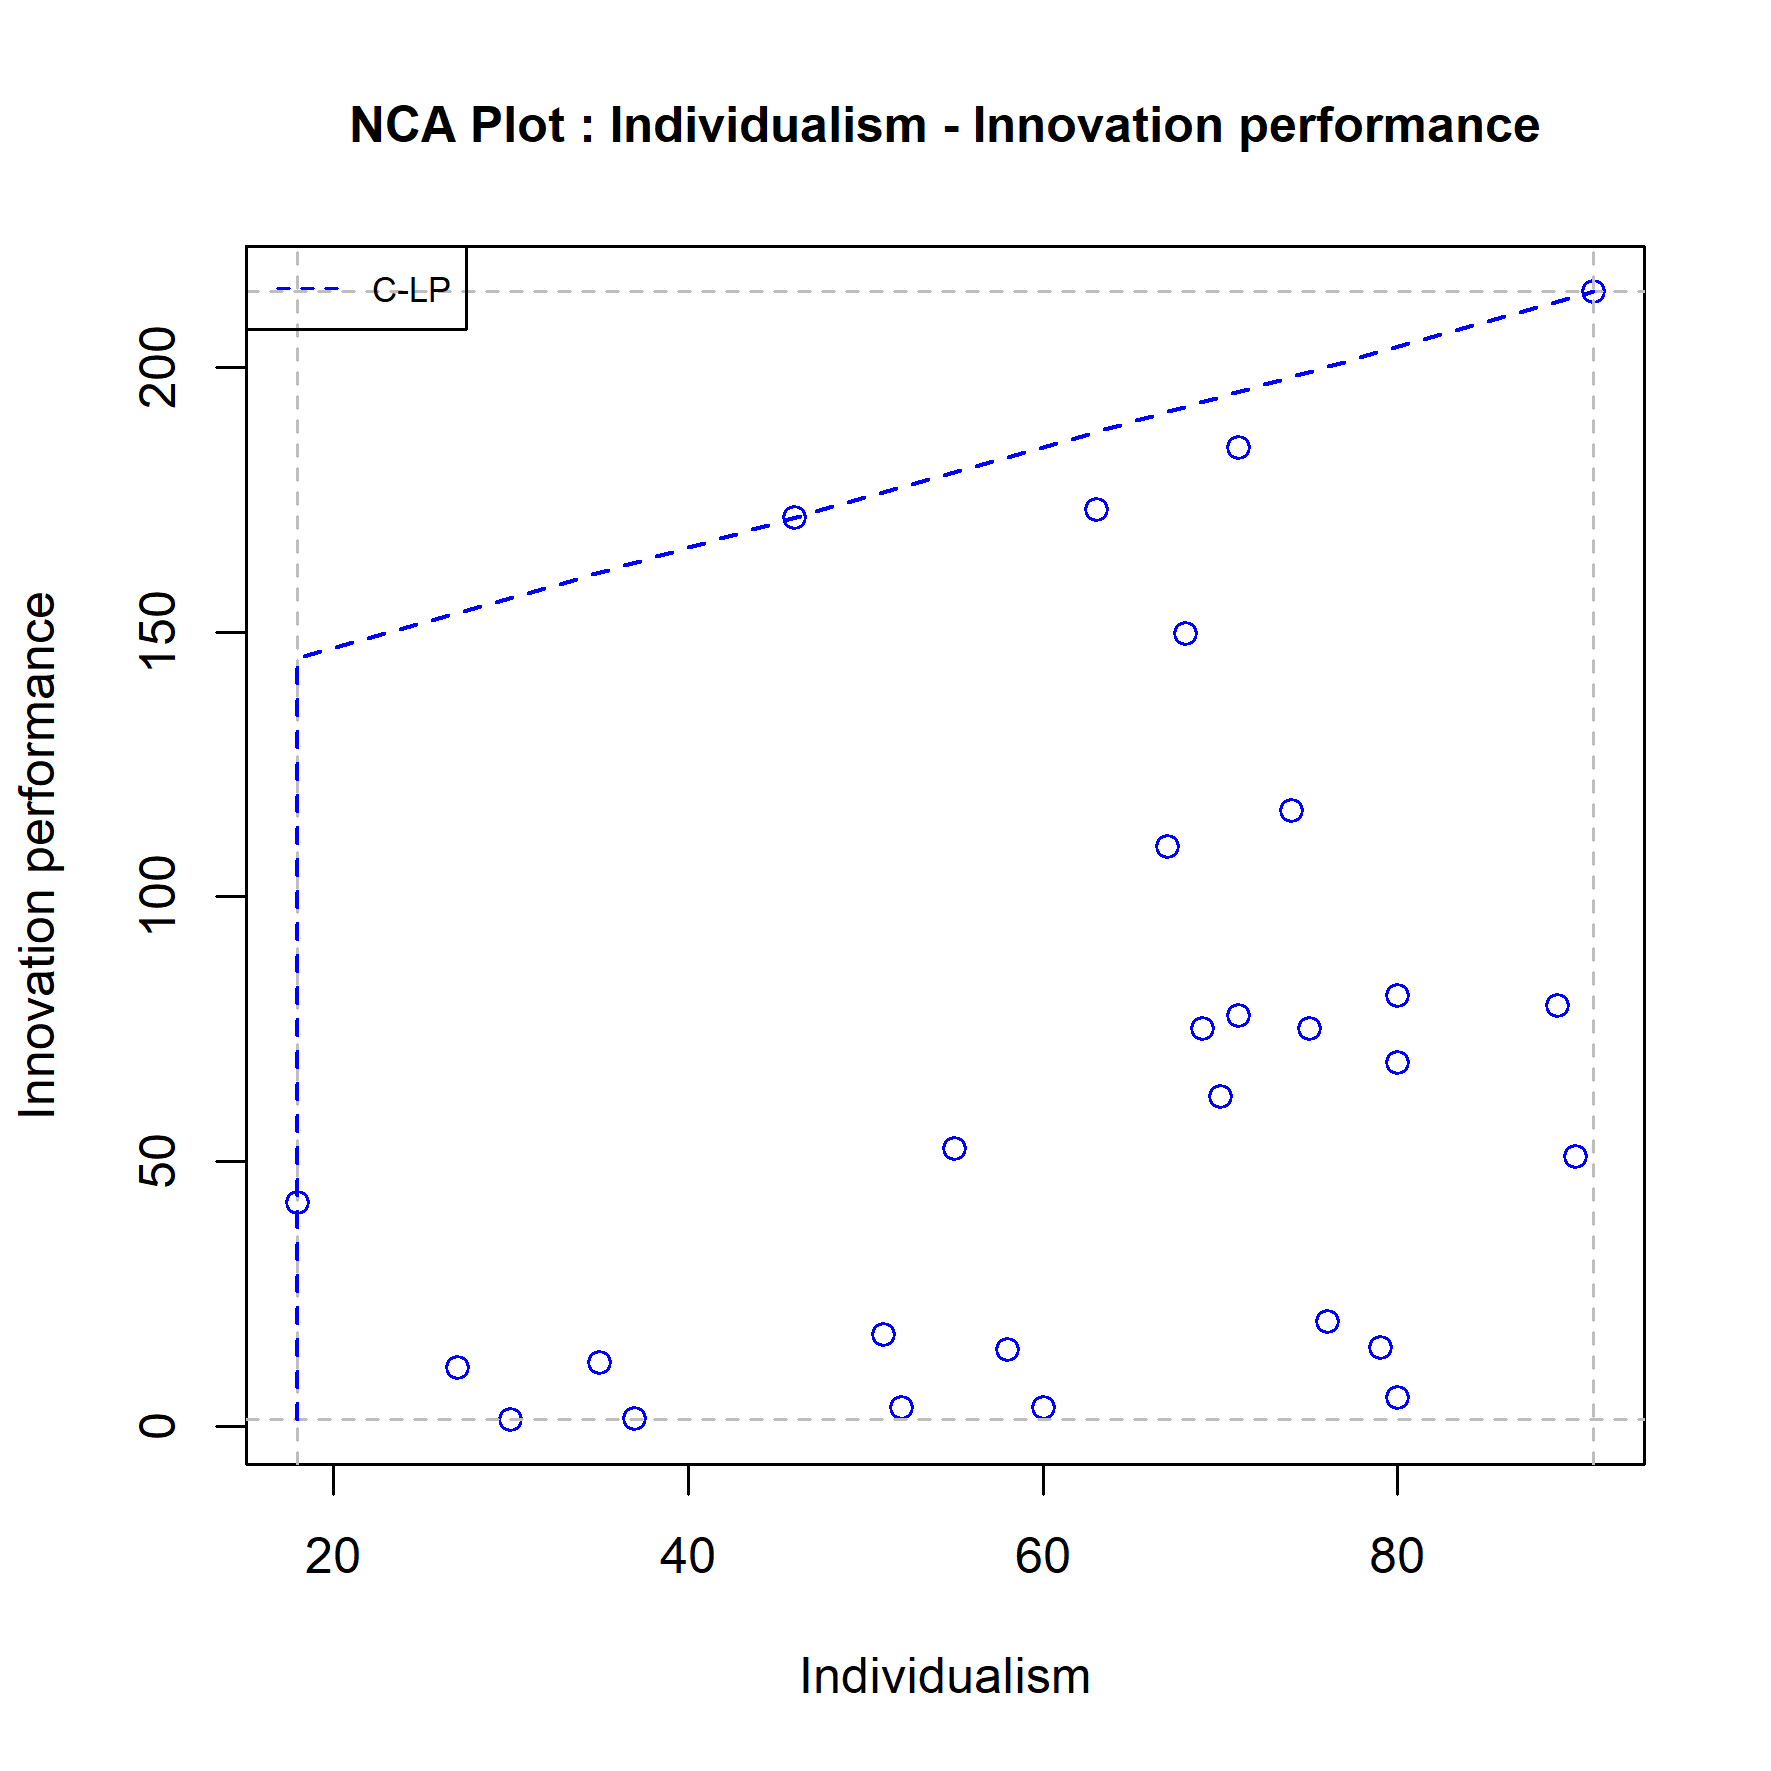
Figure 9.13: Outlier robustness check for the illustrative example: Results with including the outlier (Left), and excluding an additional outlier (Right).
The results of these outlier changes are shown in Figure 9.13. The first outlier change (re-introducing the outlier, Figure 9.13-left) reduces the effect size from 0.33 to 0.16 and produces a statistically non-significant result (\(p\) = 0.319). The second outlier change (removing a second outlier, Figure 9.13-right) increases the effect size slightly to 0.35 while keeping the results significant (\(p\) = 0.026).
The outlier robustness check indicates that the results are sensitive to outliers.
9.12.6 Different choice of the target outcome
The last robustness check explores the stability of the bottleneck analysis in terms of the percentage of cases that cannot achieve the target outcome because the condition is not satisfied. With the 90th percentile specified as the target outcome, one could for example check how the results change if the target outcome is set somewhat lower (85th percentile) or higher (95th percentile).
library(NCA)
data(nca.example)
nca.exampleN <- nca.example[-14,]

modelN <- nca_analysis(nca.exampleN, 1,3, ceilings = "c_lp",
                       bottleneck.y = 'percentile',
                       bottleneck.x = 'percentile',
                       steps = c(85,90,95))

nca_output (modelN, plots = FALSE, summaries = FALSE, bottlenecks = TRUE)
##
## ---------------------------------------------------------------------------## ---------------------------------------------------------------------------
## Y 1
## 85 18.5 (5)
## 90 33.3 (9)
## 95 40.7 (11)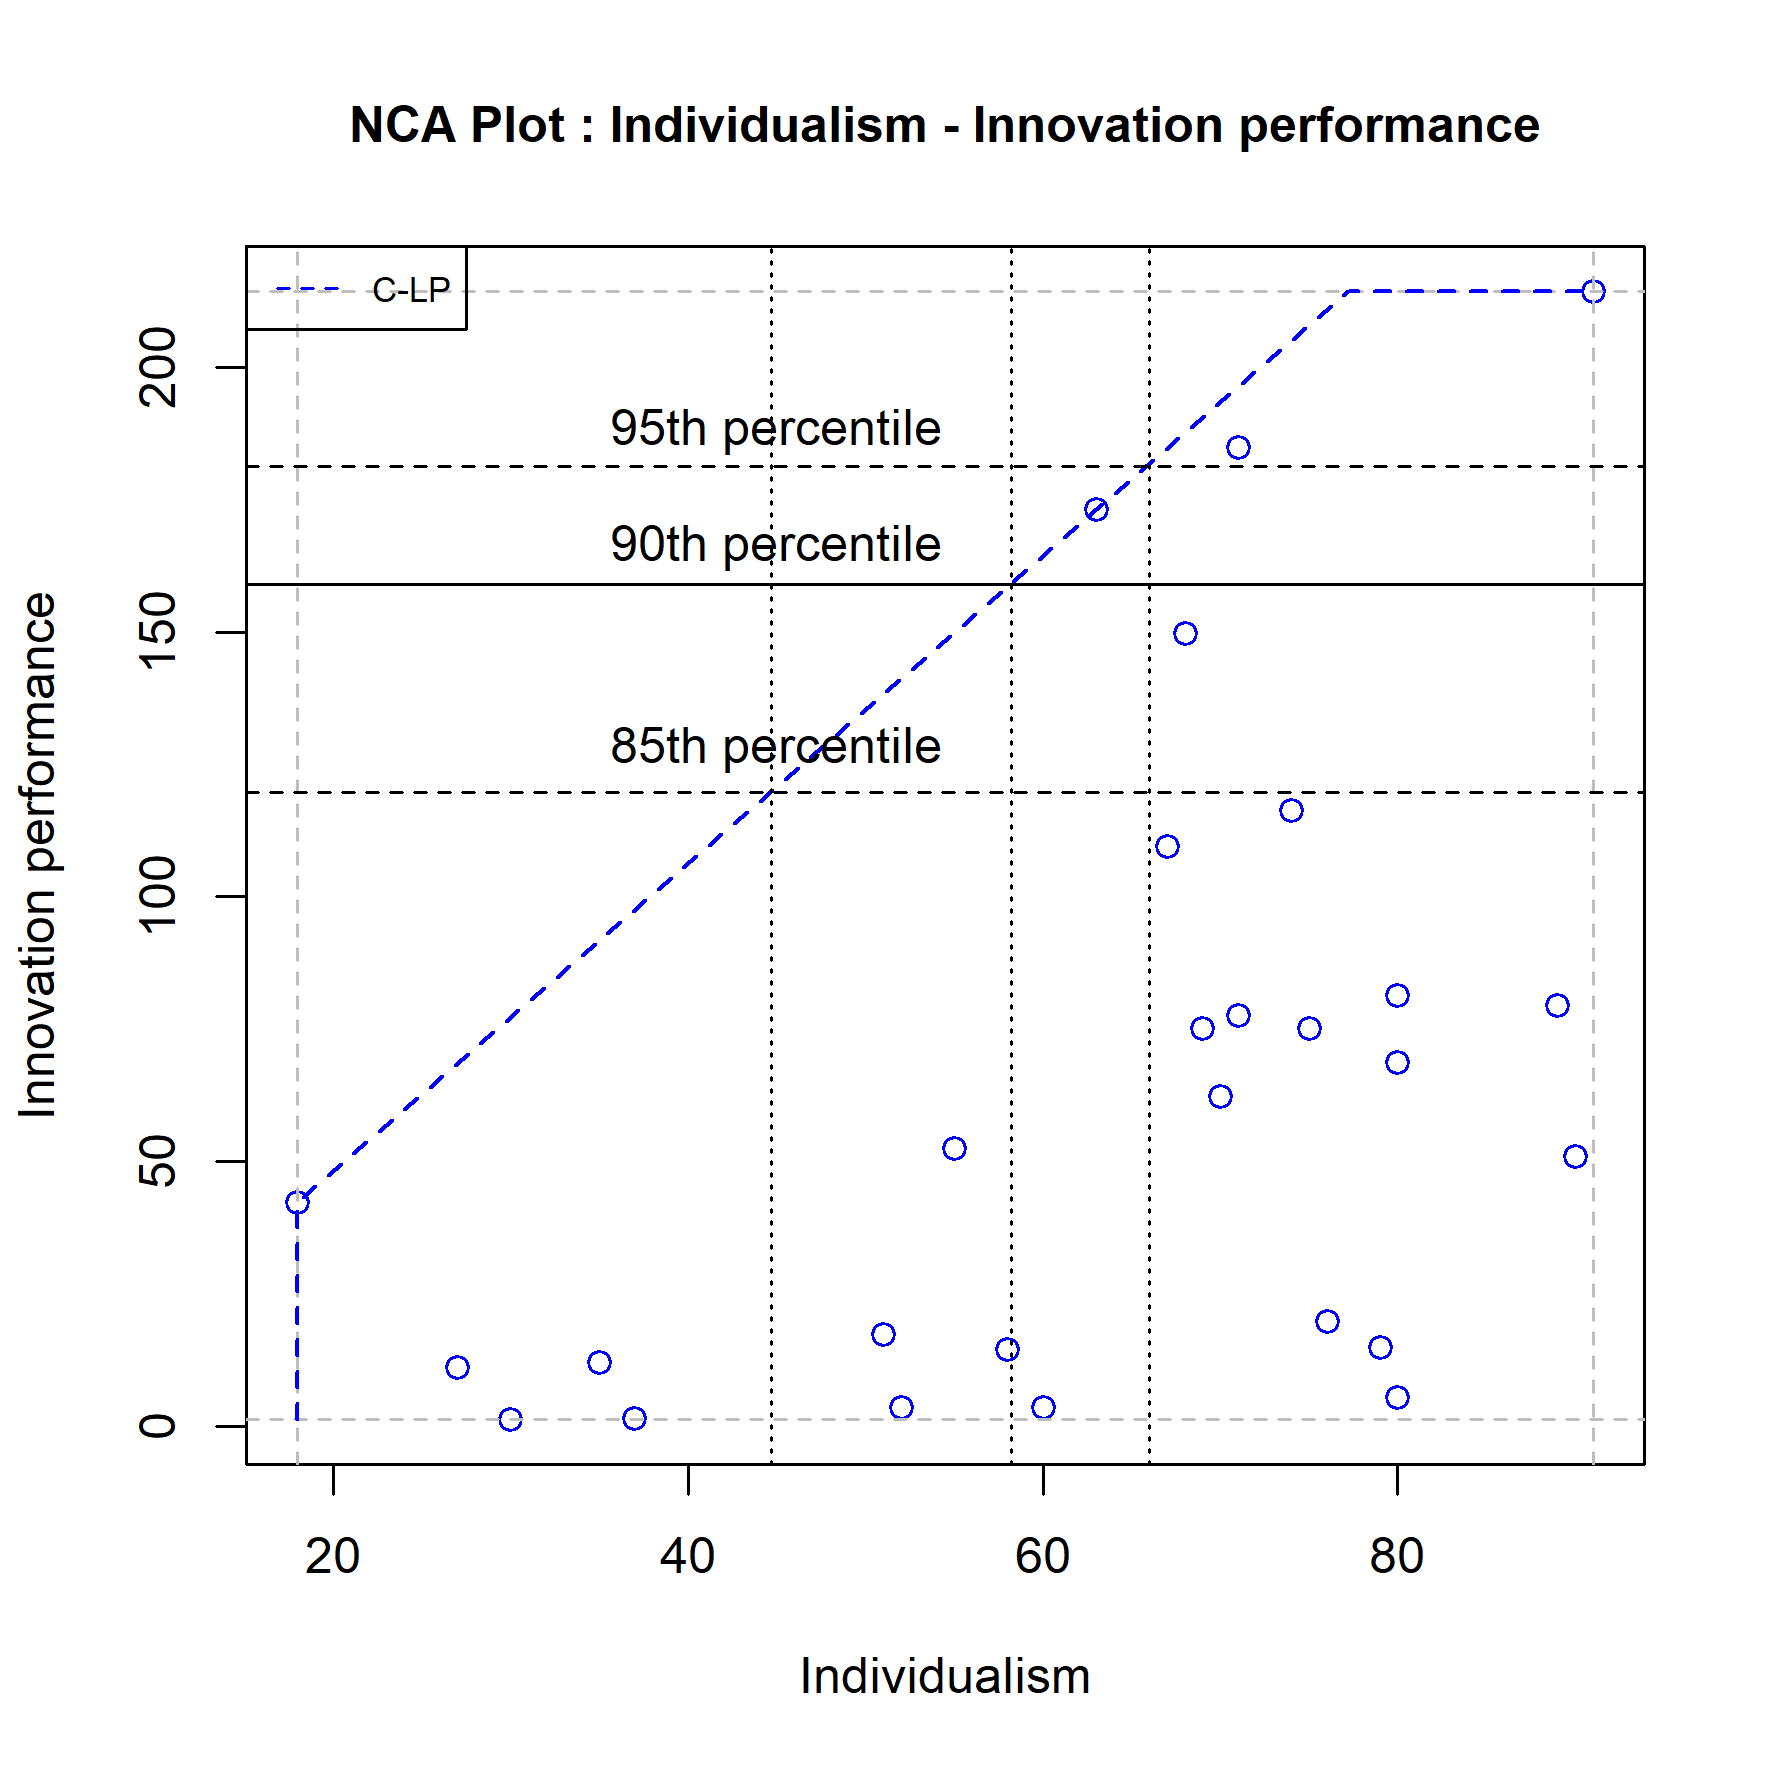
Figure 9.14: Target outcome robustness check. The effect of changing the target outcome from 90th percentile to 85th and 95th percentile.
Figure 9.14 shows that for the original target outcome (90th percentile) 33.3% of the cases (9 cases) did not achieve the required minimum level of the condition. For a target outcome of 85th percentile this percentage reduces to 18.5% (5 cases) and for 95th percentile this percentage increases to 40.7% (11 cases). The percentage of bottleneck cases changes considerably with minor changes of the target outcome.
9.12.7 Robustness table
The results of the robustness checks can be summarized in an NCA robustness table (Table 9.1) where the original NCA results are compared with the results when alternative feasible choices are made. The first row shows the original results, and the next rows display the results under alternative choices. To check robustness of necessity-in-kind, the effect size, the \(p\)-value, and the conclusion about necessity (assuming theoretical support) are presented. To check the robustness of necessity-in-degree, the percentage (%) and number (n) of bottleneck cases that are unable to achieve the required level of the condition for a selected target level of the outcome are presented.
| Robustness check | Effect size | p-value | Necessity | Bottlenecks (%) | Bottlenecks (n) |
|---|---|---|---|---|---|
| Original | 0.33 | 0.034 | yes | 33.3 | 9 |
| Ceiling change | 0.55 | 0.006 | yes | 37.0 | 10 |
| Scope change | 0.49 | 0.031 | yes | 33.3 | 9 |
| d threshold change | 0.33 | 0.034 | yes | 33.3 | 9 |
| p threshold change | 0.33 | 0.034 | no | 33.3 | 9 |
| Outlier change 1 | 0.16 | 0.319 | no | 21.4 | 6 |
| Outlier change 2 | 0.35 | 0.026 | yes | 23.1 | 6 |
| Target lower | 0.33 | 0.034 | yes | 18.5 | 5 |
| Target higher | 0.33 | 0.034 | yes | 40.7 | 11 |
The robustness checks indicate that the original necessity-in-kind result is sensitive to the exclusion/inclusion of the identified single outlier (Japan). When this outlier is added again to the analysis, the effect size reduces and the statistical significance disappears. Considering a rare single outlier as an exception according to the typicality necessity approach is possible, as the other robustness checks generally show more stable results, with effect sizes well above the threshold level of 0.10. The statistical significance is somewhat fragile as changing the significance threshold level from 0.05 to 0.01 makes the results statistically insignificant. This may be related to the relatively small sample size.
The robustness checks regarding the necessity-in-degree results show that the number of bottleneck cases reduces when outliers are handled differently, or when the selected level of the target outcome is somewhat reduced. This suggests that necessity-in-degree results are fragile, which can be explained by the irregular border between the feasible area and the ceiling zone.
Before the original results can be generalized, replications with other samples are needed. Generalization should only be made when a consistent trend emerges across multiple studies. This is a general principle that applies to any single empirical study, including an NCA study.
9.13 Meta-analysis
Given the growth of NCA publications (see Figure C.1), it can become a realistic option to conduct a meta-analysis of NCA studies for a specific topic. The general aim of a meta-analysis is to systematically combine results from multiple independent studies that address the same research question. A common goal is to estimate an overall effect size across studies by combining results from different samples. This gives a better estimate of the ‘true’ effect size in an underlying population from which the samples are assumed to be drawn. In regression analysis, this is done by estimating an overall mean effect size using weighting of the effect sizes of the different samples (e.g., based on sample size). In other words, a weighted average is used as an estimate of the overall effect size. The assumption is made that the effect sizes can be compared (e.g., in each study the \(XY\) variables are measured on the same scale), and that there is no measurement error.
However, this approach does not apply to NCA because the sample necessity effect size is usually larger than the true effect size (Section 5.5.2), such that the weighted average of the sample effect sizes is not a proper representation of the true effect size. Instead, with the same assumptions as in a regular regression-based meta-analysis (no measurement error, comparable effect sizes), and an additional assumption that the scopes of the separate studies are the same (empirically or by setting the same theoretical scope for each study), the minimum of the sample effect sizes may be the best representation of the true effect size. Alternatively, for estimating the overall ceiling, all samples could be combined into one master sample (as they are assumed coming from the same population) and then the effect size of the combined sample could be the estimation of the true effect size. Such meta-analysis is called an “individual participant meta-analysis” (IPD meta-analysis) and assumes that raw data are available. If it cannot be assumed that the samples are from the same (underlying) population, then differences in sample effect sizes could be explained by the different characteristics of the population. If absence of measurement error cannot be assumed, then an NCA outlier-analysis may possibly find cases with measurement error that could have partly caused sample effect size differences (and could be deleted).
References
The scope is the area of the bounding box.↩︎
Note that in fsQCA the ‘ceiling line’ is always predefined as the diagonal of the bounding box \([0,1]×[0,1]\), with ceiling intercept = 0 and ceiling slope = 1. In NCA it is also possible to pre-define the ceiling line. This option is integrated in NCA’s software package for
Rfrom version 5.0.0.↩︎For small-n case studies with purposive selection of cases rather than random sampling (Section 8.3.2), the \(p\)-value is not informative, and the selection is only based on effect size and theoretical support.↩︎
Note that just formulating a necessity hypothesis without challenging it with thought experiments, without specifying the theoretical domain, or without providing a causal explanation for necessity does not qualify as a formal necessity hypothesis.↩︎
See Appendix B for a description and demonstration of the
NCAsoftware forR.↩︎It may be that the ceiling line was not yet selected during the model specification (Section 9.3). Then the two default ceiling lines or another line may be displayed (by using the
ceilingsargument in thenca_analysisfunction of theNCAsoftware) to select the ‘best’ ceiling line after visual inspection.↩︎The annotations are not produced by the
NCAsoftware but added manually for illustration.↩︎Note that cases near the ceiling line can be considered as best cases or innovators (assuming that the outcome is desirable, and the condition is an effort). For a given level of the condition they have the maximum possible outcome compared to other cases.↩︎
Note that a rejection of a necessity hypothesis (if robust) can be an important result: the condition may be important, but is not necessary, and thus compensable if absent or low.↩︎
Note that for brevity potential outliers are called outliers in printed and plotted output. The analyst judges if a potential outlier is a true outlier or not.↩︎
In the software, small changes in effect size can be ignored. By default, combinations that change the effect size by less than 0.01 are left out.↩︎
For \(k\) > 1 the number of combinations of potential outlier cases can be large. The selection of combinations of two potential outliers is as follows. First, all potential single-case outliers (ceiling and scope outliers) in the original dataset are identified (List1). Next, all cases from List1 are removed from the dataset and new single-case outliers are identified in the remaining dataset (List2). Then both lists are combined into one set of outliers. The effect size changes of all combinations of two outliers are evaluated by comparing the effect size without the pair with the effect size with the pair (the original dataset).↩︎
Note that for \(k > 1\) the
plotly\(XY\)-plot only shows the single potential outliers as for \(k = 1\).↩︎Note that the typicality perspective can only be used when rare exceptions exist. Having many points far above the ceiling or having points that are not isolated from the rest of the points, do not qualify for adopting the typicality perspective. The typicality perspective is only meant for a very limited number of isolated points that represent another (unknown) explanation than necessity. Typicality is about “rare exceptions” (Goldstein, 2012) and applied to NCA’s deterministic causal logic (Chapter 2), deterministic necessity becomes “deterministic with exceptions” (Dul, 2024a), not probabilistic necessity. Also see Section 7.5.2.3 on how to deal with exceptions during the development of a formal necessity hypothesis.↩︎
The target condition for a given target outcome can be computed from the inverse of the ceiling line. For a linear ceiling line like the C-LP, the inverse can be computed from the intercept and slope of the ceiling line according to Equation (4.16). The bottleneck table presented in Section 9.11.2 shows how to obtain the value of the target condition for a target outcome value expressed in percentiles.↩︎
Note that the
stepsargument in thenca_analysisfunction interprets a single number as the number of steps to be displayed in the bottleneck table, and multiple numbers as specific \(Y\)-values to be displayed. For displaying a specific \(y\)-value, it must be accompanied by another (e.g., arbitrary) \(y\)-value.↩︎For example, in regression analysis the regression coefficient and its \(p\)-value are the main estimates that can be sensitive to the selection of the functional form of the regression equation (e.g., linear or non-linear), or the inclusion or exclusion of control variables in the regression model (X. Lu & White, 2014). Another example of an analyst’s choice is the threshold \(p\)-value (e.g., 0.05 or 0.01).↩︎